Machine translation solved the sentence a decade ago. Feed DeepL a paragraph and you get something a native speaker will accept, and the remaining argument is about register rather than accuracy.
None of that helps you translate a novel. A book is not a long paragraph — it is a system with recurring characters, invented terminology, an established narrative voice, callbacks that only work if the earlier phrasing is remembered, and a decision made on page 12 that must still hold on page 340.
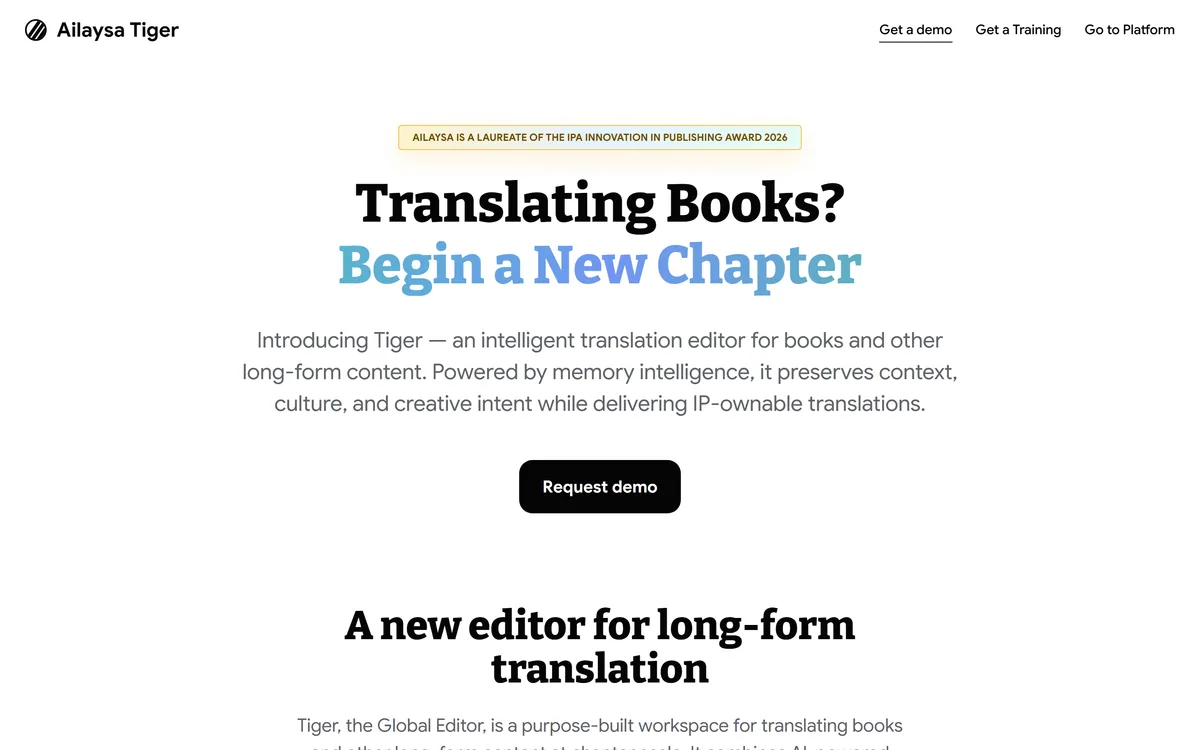
Ailaysa is built around that specific gap, and this review looks at whether the architecture actually addresses it. What follows covers the memory agent model, why publisher file formats matter more than they sound, what IP ownership means in a translation contract, and where a general-purpose model is still the better tool.
| Company | Ailaysa Technologies Private Limited |
|---|
| Category | AI-assisted translation and localisation for long-form content |
|---|
| Flagship editor | Ailaysa Tiger |
|---|
| Designed for | Books, courseware, knowledge bases and creative long-form content |
|---|
| Working unit | Chapter scale, with paragraph-level editing |
|---|
| Named capabilities | Full book intelligence analysis, Memory Agents, auto-formatting, collaboration, API access |
|---|
| File formats | DOCX, IDML, ePub |
|---|
| Target languages | Stated at more than 30 |
|---|
| Positioning on rights | Vendor describes the output as IP-ownable translations |
|---|
| Human role | Vendor states humans are in control with AI agents in the loop |
|---|
| Recognition | IPA Innovation in Publishing Award 2026 |
|---|
| Development background | Vendor describes five years of experimentation with publishers and translators |
|---|
- Ailaysa is an AI-assisted translation workspace built specifically for long-form content — books, courseware, knowledge bases — rather than for interface strings or one-off passages.
- The editor is called Tiger, and it works at chapter scale with paragraph-level editing rather than the sentence-by-sentence grid most translation tools impose.
- Memory Agents are the differentiator: they carry style decisions and terminology forward automatically, which is the single hardest thing about translating a manuscript.
- Formats are publisher formats. DOCX, IDML and ePub, with auto-formatting — meaning the output can go back into production rather than into a rebuild.
- Built by Ailaysa Technologies, an Indian company, with over 30 target languages and an IPA Innovation in Publishing Award in 2026.
Anyone who has actually run a book through a general translation workflow knows the failure modes, and they are not the ones people expect.
The output is rarely wrong. It is inconsistent. The protagonist's nickname is rendered three different ways across four chapters. A technical term settles into one translation early, drifts to another by the middle, and reverts near the end. The narrative voice is warm in chapter two and clinical in chapter nine because those chunks were translated in separate sessions with no shared memory.
None of this is visible sentence by sentence. Every individual line passes review. The damage only appears when a reader — or an editor — reads the whole thing in sequence, and by then the fix is a manual consistency pass across the entire manuscript.
There is a second failure that costs more time than anyone budgets for. Translation tools shred formatting. A manuscript goes in as a designed document and comes back as text, which means the typesetting is done twice.
Both problems are structural rather than model problems. A better language model does not fix them, because neither is caused by the quality of any individual translation.
Nothing in a badly translated book is wrong sentence by sentence. It goes wrong across three hundred pages, which is exactly where sentence-level tools cannot see.
Memory Agents, And What They Are Actually Doing
Ailaysa's answer is described as Memory Agents that apply style and terminology automatically, sitting alongside a full book intelligence analysis of the manuscript.
It is worth separating this from translation memory, the mechanism Lokalise and the rest of the localisation industry have been built on since the 1990s. Classic translation memory is a lookup: it recognises a segment it has seen before and reuses the previous translation. It is excellent for repetitive material — manuals, product listings, contracts — and close to useless for prose, where sentences rarely repeat verbatim.
What a book needs is not repeated segments but held decisions. How this character's voice sounds. Which register the narrator uses. What the invented terms are and how they were rendered. Those are not lookups, they are constraints that should apply to text the system has never seen.
That is the interesting claim here, and it is the right one to be making. It also means the honest evaluation question is not accuracy on any single chapter but consistency across all of them.
The analysis-first sequencing matters too. Reading the whole manuscript before translating any of it is how a human translator works and how almost no automated pipeline does — most chunk the text and translate the chunks.
- Pick a manuscript you know well, with recurring terminology and a distinct narrative voice.
- Translate chapters one, seven and fourteen — deliberately non-adjacent, so nothing benefits from local context.
- Have a native reader check whether character names, invented terms and register match across all three.
- Change one terminology decision deliberately and confirm it propagates rather than requiring a manual find-and-replace.
- Round-trip an IDML file and check whether the layout survives, because that is where the hidden hours live.
DOCX, IDML And ePub Are Not A Trivial Detail
Three formats, and the middle one tells you who built this and for whom.
IDML is Adobe InDesign's interchange format. Nobody outside publishing production has heard of it, and nobody inside publishing production can work without it. Supporting IDML means a designed book can be translated and returned as a designed book, with styles, frames and structure intact.
The alternative — the normal path — is that a designer rebuilds the layout in the target language from scratch. For an illustrated book, a textbook or anything with a complex grid, that is often a bigger cost than the translation itself.
ePub covers the digital edition and DOCX covers the manuscript before design. Together the three formats span the whole production chain, which is a strong signal that the team spent the five years with publishers that they say they did.
It also quietly narrows the audience. A tool that speaks IDML is a tool for publishers and translation vendors, not for someone translating their blog.
- DOCX for manuscripts before typesetting and for editorial rounds
- IDML for designed InDesign books, which is the format that saves the most downstream work
- ePub for digital editions and reflowable content
- Auto-formatting to keep structure rather than returning flat text
- An API for publishers with enough volume to want this inside their own pipeline
The IP Ownership Claim, And Why Publishers Ask
The vendor describes the output as IP-ownable translations, which sounds like marketing and is actually addressing a live commercial anxiety.
A translation is a derivative work with its own copyright. In conventional publishing that copyright is negotiated — usually held by the publisher, sometimes shared with the translator, always assigned explicitly in a contract. It is an asset that gets licensed, sold and inherited.
When a machine produces the translation, publishers reasonably want to know what they are holding. Whose rights attach to the output, whether the platform retains any claim, whether the text was used to train anything, and whether the result can be licensed onward with clean title.
For a trade publisher preparing a foreign edition, an ambiguous answer to that question is disqualifying regardless of translation quality. Stating it plainly is the correct thing for a vendor in this category to do.
It is still a claim rather than a contract. If you are a publisher, the terms of service and any data processing agreement are where the answer actually lives — read those, not the homepage.
Where A General Model Is Still The Better Choice
Being specific about the cases where this is the wrong purchase is more useful than another feature list.
Short-form and interface strings. App copy, marketing pages and UI labels are what Lokalise and its peers are built for, with the developer plumbing — string keys, branches, pull requests — that a book workspace has no reason to carry.
One-off passages. If you need a paragraph rendered well right now, a strong general model gets you there in seconds without a project setup.
Languages outside the supported set. Over 30 languages covers the major commercial markets and leaves a long tail uncovered. Check yours specifically before assuming.
Literary work where the translator is the point. Poetry, experimental prose, and anything where the translation is itself an authored act. Assistive tooling can support that work; it cannot replace the judgement that makes it worth reading.