Global AI assistants such as Gemini and Claude handle Hindi reasonably and everything else in India considerably less well. Bengali, Marathi, Telugu, Tamil, Gujarati and Kannada each have more speakers than most European languages, and each is served as an afterthought by models trained predominantly on English text.
The gap is wider than a translation problem. Most of India interacts with technology by voice rather than by typing, partly because typing in Devanagari or Tamil script on a phone is slow, and partly because a meaningful share of users read less comfortably than they speak.
BharatGPT is built around those two facts rather than adapted to them, and that is the case for taking it seriously against far larger competitors.
BharatGPT, Defined
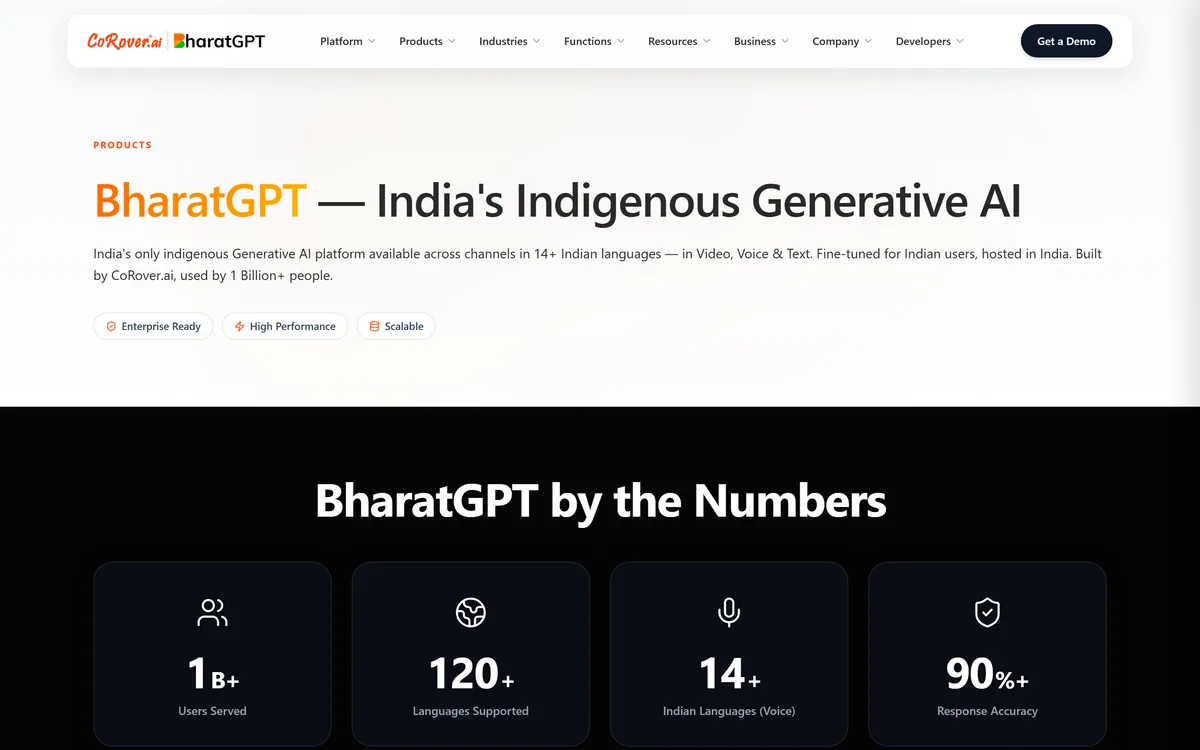
- An Indian-language generative AI platform from CoRover, described as India's only indigenous generative AI platform available across channels.
- 14+ Indian languages by voice, with 120+ languages overall — voice coverage being the number that matters in this market.
- Three modes, not one: video, voice and text, including a VideoBot with an AI avatar and lip-sync.
- Hosted in India on Google Cloud Platform, stated for data sovereignty, privacy and security.
- Integrated with Bhashini, the National Language Translation Mission under MeitY, which ties it to national language infrastructure.
Why Voice Coverage Is The Number That Matters
CoRover states 14 or more Indian languages by voice and 120 or more languages overall. The distinction between those two figures is the important part.
Text support in a language is comparatively easy — a model that has seen the script can generate it. Voice is much harder, because it requires speech recognition trained on real accents and speaking styles, plus speech synthesis that sounds natural rather than robotic, in each language separately.
Speech specialists such as Speechmatics face the same problem, which is why global providers publish long language lists for text and much shorter ones for good voice interaction. And in India voice is not a convenience feature; for a large share of users it is the primary interface.
Fourteen languages by voice is a serious investment. It also invites the obvious question, which the site does not answer: which fourteen. India has twenty-two scheduled languages, and whether your users' language is in the list is a yes-or-no question that determines whether the platform is usable for you at all.
That is the first thing to establish in any conversation with CoRover, along with whether coverage means recognition, synthesis or both — because a language you can speak to but that cannot speak back is a different product.
Text support in a language is easy to claim. Voice support has to be built language by language, which is why the shorter number is the honest one.
What Bhashini Integration Adds
BharatGPT is stated as integrated with Bhashini, the National Language Translation Mission under India's Ministry of Electronics and Information Technology.
This matters more than a typical partnership line. Bhashini is public language infrastructure — a national effort to build translation and speech capability across Indian languages, with datasets and models developed with public participation.
Integrating with it means the platform draws on language resources built specifically for Indian languages rather than on whatever a global model absorbed incidentally. For languages with limited digital text, that difference is substantial.
The same sovereignty argument underpins Jais Chat for Arabic. It also signals institutional alignment, which matters for the government and public-sector deployments this platform is clearly aimed at. A system connected to national language infrastructure is easier to procure in that context than a foreign alternative.
The reasonable caution is that integration is a broad word covering a wide range of technical depth. Ask what specifically is used, and for which languages.
Does Sovereign Hosting Actually Change Anything?
The platform is stated as hosted on Google Cloud Platform in India, for data sovereignty, privacy and security, and described as India's first indigenous LLM fine-tuned for Indian users, culture and context.
For a category of buyer this is decisive rather than preferable. Indian government departments, public-sector undertakings, banks and healthcare providers operate under data localisation expectations that make sending citizen data to servers abroad difficult or impossible. A platform hosted in-country removes that objection entirely.
It is worth being precise about what in-country hosting on a global cloud provider does and does not give you. It means data resides in Indian data centres, which addresses residency requirements directly. It does not by itself make the provider immune to every foreign legal process, and that nuance matters to some buyers and not others.
The cultural fine-tuning claim is harder to assess and genuinely meaningful if true. Indian users ask questions with different assumptions, reference different institutions and use English mixed with local languages in ways a globally-trained model handles poorly. A model tuned on that is measurably better at it — but no evaluation is published, so this has to be tested rather than accepted.
For a public-sector buyer the practical sequence is straightforward: confirm hosting arrangements in writing, then test in the specific languages your citizens actually use.
- Confirm which specific Indian languages are supported by voice, and whether that means recognition, synthesis or both.
- Get hosting and data residency arrangements documented rather than described.
- Ask what Bhashini integration technically involves, and which languages it covers.
- Test with your own users' speech, including regional accents and mixed-language phrasing.
- Establish retention and deletion terms for citizen data before any deployment.
Video, Voice And Text Is The Right Shape For This Market
BharatGPT delivers across video, voice and text, including what CoRover calls a Generative AI VideoBot — an interactive digital twin and AI video avatar with lip-sync.
Multi-channel delivery is more consequential in India than in markets where everyone types comfortably in English. A text-only assistant excludes users who read less easily than they speak, and a voice-only one loses the reassurance that a visible presence provides in a service interaction.
The VideoBot with lip-sync is aimed at exactly that: public-facing service contexts where an avatar answering in the user's own language is more approachable than a text box. For railway enquiries, government services or banking support, that is a real usability difference rather than a novelty.
The realistic expectation is the one that applies to all avatar systems. It works well for informational exchanges — status, procedure, eligibility — and less well where the interaction is emotionally weighted or unusually complex.
For deployments at scale, the questions to press are latency in real conditions on ordinary connections, and how gracefully the system degrades to voice or text when bandwidth is poor. In much of the market that fallback is the normal case rather than the exception.
Can A Billion Users Be Right?
The site carries striking figures: used by more than a billion people, over 90 per cent response accuracy, and 99.9 per cent uptime.
The billion-user figure needs careful reading. CoRover's technology has been deployed in very high-traffic public services, and a platform embedded in a service used by a large share of India's population can accumulate an enormous cumulative reach. That is plausible as an aggregate exposure figure and it is not a count of active users of BharatGPT as a product.
The accuracy figure is unfalsifiable as stated, because accuracy depends entirely on the question set. Ninety per cent on scheduled, procedural queries in a defined domain is a very different achievement from ninety per cent on open questions in eleven languages, and both could be reported the same way.
The uptime figure is the most conventional and the easiest to hold a vendor to — ask for it as a contractual service level rather than a marketing claim.
None of this suggests the platform underperforms. It means the numbers cannot substitute for your own evaluation, and a public-sector buyer should be testing accuracy on their actual query mix in their actual languages before signing anything.
Running A Realistic Pilot
This is enterprise and government software, so evaluation happens through CoRover rather than a signup. Going in with your own tests matters more than usual, because the published claims cannot be interpreted from outside.
The bar is step three. Accuracy on your real query mix in your real languages is the only number that predicts a deployment.
- Establish first which specific languages are supported by voice, and confirm your users' languages are among them.
- Assemble two hundred real queries from your existing support or service logs, in the languages they actually arrived in.
- Run those through the system and score the answers with native speakers, counting only errors that would affect a citizen or customer outcome.
- Test mixed-language phrasing deliberately, since English mixed with a local language is how a great many Indian users actually speak.
- Check VideoBot latency on a poor connection and confirm it degrades cleanly to voice or text rather than failing.
- Get hosting, residency, retention and deletion terms in writing before any live citizen data is involved.
BharatGPT: What CoRover States
| Product type | Generative AI platform for Indian languages across video, voice and text |
|---|
| Positioning | Described as India's only indigenous generative AI platform available across channels |
|---|
| Indian language voice support | 14+ languages |
|---|
| Total language support | 120+ languages |
|---|
| National integration | Bhashini, the National Language Translation Mission under MeitY |
|---|
| Video capability | Generative AI VideoBot — interactive digital twin and AI video avatar with lip-sync |
|---|
| Hosting | Google Cloud Platform, in India, stated for data sovereignty |
|---|
| Stated accuracy | 90%+ response accuracy |
|---|
| Stated uptime | 99.9% |
|---|
| Stated reach | 1 billion+ users served |
|---|
| Company | CoRover P. Limited |
|---|
| Headquarters | BHIVE Premium Tech Park, HSR Campus, Hosur Road, Bengaluru 560068 |
|---|
| Other offices | London and New Delhi |
|---|
| Contact | chat@CoRover.ai |
|---|
| Developer resources | Certifications, a HuggingFace LLM listing, and a published research paper |
|---|
Who Should Consider BharatGPT
The correct fit when
- You serve Indian citizens or customers who interact primarily by voice in a language other than English.
- Data residency in India is a requirement rather than a preference, as it is for most public-sector deployments.
- You need video, voice and text delivery, because your users are not uniformly comfortable with text.
- Alignment with national language infrastructure such as Bhashini matters for your procurement.
- Your use case is service delivery — enquiries, procedures, eligibility — rather than open-ended reasoning.
The wrong choice when
- You need general reasoning, coding or analysis, where global frontier models are considerably stronger.
- Your users' specific language is not among the supported voice languages, which is the first thing to check.
- You want to evaluate by self-serve trial, since access runs through the company.
- You need published benchmarks to make a decision, as the stated figures carry no methodology.
- You operate outside India, where the sovereignty and Bhashini advantages do not apply.