AI and human transcription and subtitles in 150+ languages
Video & Audio Review
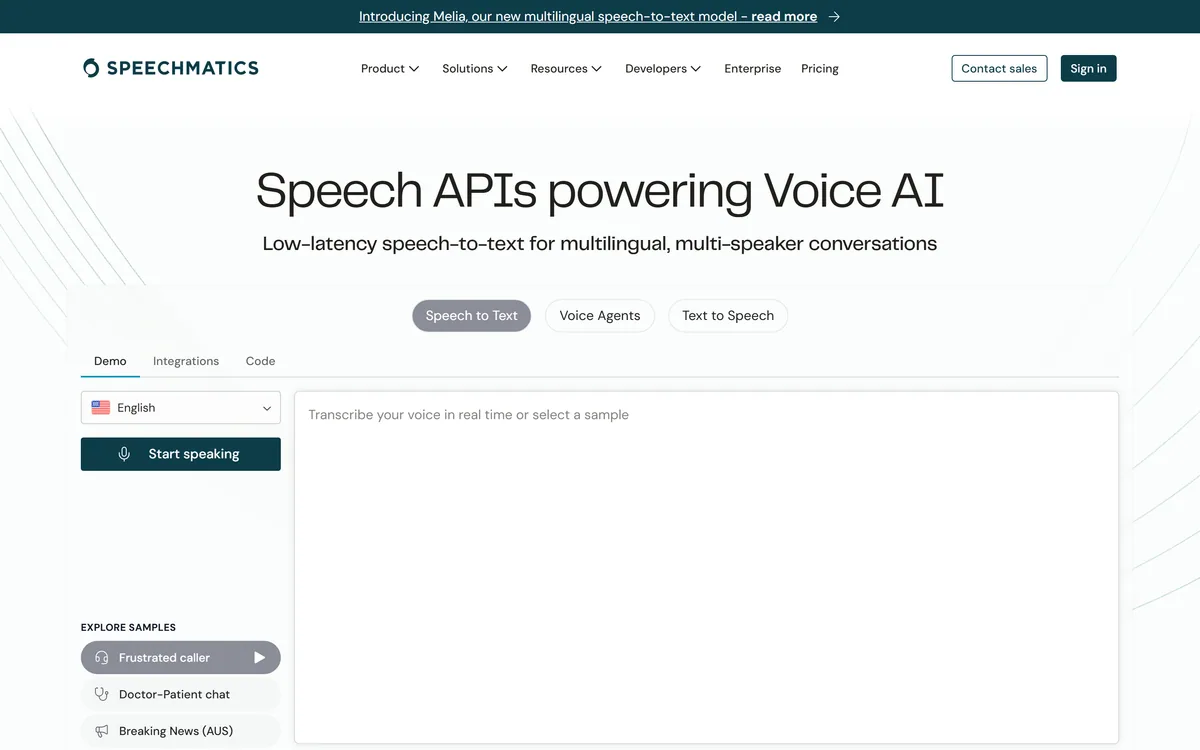
Speechmatics is a speech-to-text API covering 55+ languages with speaker diarization, custom vocabulary and mid-sentence code-switching. It runs on-device, on-premises or in the cloud, and posted the lowest word error rate in an independent 12-service benchmark in August 2026.
Excellent
Speechmatics has an AInexfinder Editor Score of 4.6/5.
Best for: Teams building voice AI agents where transcript quality drives everything downstream; Healthcare and legal deployments that cannot send audio to a third-party cloud
The visit link goes to speechmatics.com, the official site. Paid placements on AInexfinder are always labelled. How we make money
Speech-to-text benchmarks are usually run on audio nobody actually has: one speaker, a good microphone, a neutral accent, no interruptions. Every engine looks excellent on that. The differences appear the moment you feed in a real meeting, a doctor's consultation, or two people talking over each other in two languages.
Speechmatics is built for that second case, and it is the rare vendor in this space with an independent result to point at rather than a self-reported number. In Pipecat's August 2026 benchmark of twelve services, it recorded a 1.07% pooled word error rate — the lowest in the test.
This review covers what that benchmark does and does not tell you, why code-switching is the capability worth caring about, what on-device deployment changes for regulated buyers, and where a transcription API stops being the hard part of your problem.
This is the strongest claim on the page, so it deserves to be read carefully rather than quoted.
A 1.07% pooled word error rate means roughly one word in a hundred is wrong — inserted, deleted or substituted. Against eleven competitors including Deepgram, AWS and Azure, that is a real result, and the fact it comes from Pipecat rather than from Speechmatics is what makes it worth citing at all. Nearly every accuracy claim in this category is the vendor grading its own homework.
What it does not tell you is how it performs on your audio. 'Pooled' means averaged across a test set, and word error rate is exquisitely sensitive to domain: medical terminology, product names, industry jargon and heavy background noise all move it substantially. A service that wins a pooled benchmark can still be second-best on your particular recordings.
The other thing WER hides is which words were wrong. One error in a hundred is excellent if the misses are 'the' and 'a', and much worse if they are drug names or dollar amounts. Custom vocabulary exists precisely because the words that matter most are the ones a general model gets wrong most.
An independent benchmark tells you the engine is good. Only your own audio tells you it is good at the words you cannot afford to lose.
Most engines handle multiple languages by asking you to pick one per file. That model breaks on how enormous numbers of people actually speak.
A speaker moving between Hindi and English inside one sentence, or Spanish and English, or Arabic and French, is not an edge case — it is ordinary conversation across much of the world, and a single-language engine transcribes half of it as nonsense.
Handling that mid-sentence is genuinely hard, because the model cannot settle on a language and stay there. It is also the capability most likely to matter if your users are outside a monolingual market, and the one least visible in an English-only demo.
Speaker diarization sits alongside it: labelling who said what. For meetings, interviews and contact-centre calls, an undiarized transcript of four people is close to useless — you have the words and none of the structure.
Cloud, on-premises and on-device deployment, with data non-logging as standard, plus ISO 27001:2022, GDPR, HIPAA and SOC 2 Type II.
In consumer software that list is procurement boilerplate. In healthcare and legal it is the whole conversation. A hospital cannot send patient consultations to a third-party cloud, and a law firm cannot send privileged material, regardless of how accurate the transcription is.
On-device is the strongest version of that answer: audio never leaves the machine, so the compliance question largely evaporates rather than being managed. It also removes latency and network dependence, which matters for live captioning where a two-second lag is the difference between usable and not.
The named customers — Adobe, LiveKit, Ubisoft, Stenograph — are a useful signal here. Stenograph in particular is a court-reporting company, which is about as unforgiving an accuracy environment as exists.
The evaluation everyone should run, and almost nobody does, takes an afternoon.
It is worth being clear about scope. Speechmatics is infrastructure — an API that turns audio into accurate text. It is not a meeting-notes product, a podcast editor, or an analytics platform.
If you want summaries, action items, searchable archives or speaker analytics, you are building that on top, or you want a product like Otter or Rev that ships the whole workflow with transcription inside it. Choosing an API when you wanted an app is the most common mismatch in this category.
The flip side is that infrastructure is the right choice when transcription quality is the constraint and you control the product around it. A voice AI agent, a live captioning system, a clinical documentation tool — these live or die on the accuracy of the text, and a two-percent difference in error rate compounds through everything downstream.
Finally, accuracy on paper is not accuracy in your pipeline. Audio capture quality, sample rate and how you chunk streaming input can cost you more than the difference between the top three vendors.
Comparing transcription vendors is impossible without these.
| Category | Speech-to-text API and infrastructure |
|---|---|
| Languages | 55+ |
| Independent benchmark | 1.07% pooled word error rate, lowest of 12 services (Pipecat, August 2026) |
| Benchmarked against | Deepgram, AWS and Azure among others |
| Speaker handling | Built-in diarization |
| Multilingual | Code-switching supported mid-sentence |
| Customisation | Custom vocabulary |
| Latency | Low-latency, suitable for live captioning |
| Deployment | On-device, on-premises, cloud |
| Data handling | Non-logging as standard |
| Certifications | ISO 27001:2022, GDPR, HIPAA, SOC 2 Type II |
| Named customers | Adobe, LiveKit, Ubisoft, Stenograph |
| Sectors | Healthcare, legal, media, contact centres, meeting platforms |
Speech-to-text across 55+ languages
Code-switching support for speakers changing language mid-sentence
Speaker diarization built in
Custom vocabulary for domain terms and product names
Low-latency streaming suitable for live captioning
On-device deployment, with audio never leaving the machine
On-premises and cloud deployment options
Data non-logging as standard
ISO 27001:2022, GDPR, HIPAA and SOC 2 Type II compliance
The first decision is not which engine — it is whether you want infrastructure or an application.
| Tool | What you get | Deployment | Best when |
|---|---|---|---|
| Speechmatics | A transcription API you build on | On-device, on-prem or cloud | Accuracy is the constraint and you own the product around it |
| Deepgram | A transcription API you build on | Cloud, with self-hosted options | You want an alternative API to benchmark against |
| Otter.ai | A finished meeting-notes product | Cloud only | You want notes and summaries, not an API |
| Rev | Transcription service with human options | Cloud | Accuracy must be guaranteed by a person |
| HappyScribe | Transcription and subtitling workflow | Cloud | Subtitles and an editor matter more than an API |
APIs, finished apps and human services solve the same sentence in very different ways.
Last checked . Read from speechmatics.com during this check, with the screenshot above captured at the same time.
The benchmark figure is reported by Speechmatics as coming from a third party; we have not read the Pipecat test ourselves. Commentary on how word error rate behaves across domains describes the metric generally rather than this engine specifically.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Speechmatics website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Speechmatics earns an AInexfinder Editor Score of 4.6/5 (excellent). Best for: Teams building voice AI agents where transcript quality drives everything downstream; Healthcare and legal deployments that cannot send audio to a third-party cloud; Live captioning products where latency matters as much as accuracy.
Visit SpeechmaticsLog in to write a review.
No reviews yet. Be the first to share your experience with Speechmatics.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Speechmatics from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
AI and human transcription and subtitles in 150+ languages
AssemblyAI sells voice AI infrastructure: production APIs for pre-recorded and real-time speech-to-text on its Universal models, a Speech Understanding API that turns transcripts into structured insight, a Voice Agent API over a single WebSocket, and guardrails including PII redaction and content moderation.
Rev has repositioned from transcription into an investigative intelligence platform for legal teams, combining AI evidence analysis with human-verified transcription guaranteed 99%+ accurate in 12 hours, plus court reporting, deposition summaries and a speech-to-text API.
Deepgram provides speech-to-text and text-to-speech through its Flux models, plus a Voice Agent API that combines transcription, speech synthesis and LLM orchestration into a single interface. Everything runs in real time or batch, in the cloud or self-hosted, with text-to-speech latency stated as low as 80ms.
Cockatoo transcribes audio and video across 100+ languages with a stated accuracy of up to 99.8%, exports to SRT, DOCX, PDF and TXT, imports from Dropbox and YouTube, and offers three free transcripts daily with no card required.

ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.
Related Pages