AI and human transcription and subtitles in 150+ languages
Video & Audio Review
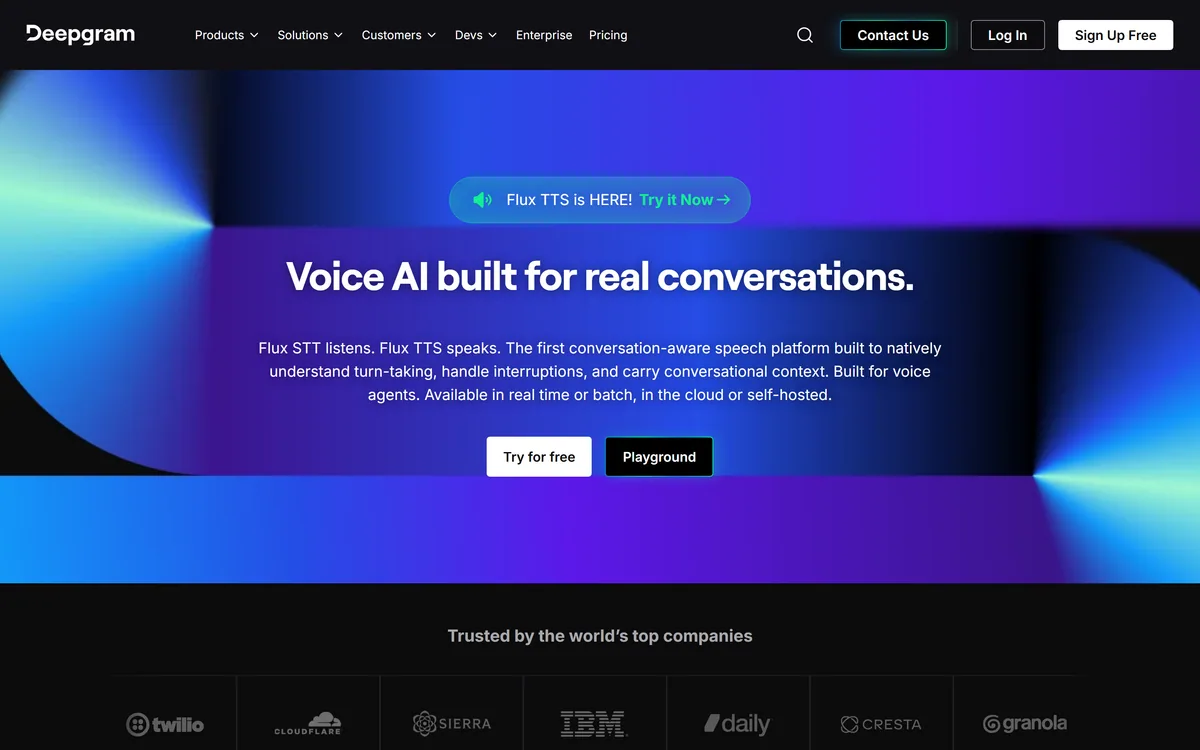
Deepgram provides speech-to-text and text-to-speech through its Flux models, plus a Voice Agent API that combines transcription, speech synthesis and LLM orchestration into a single interface. Everything runs in real time or batch, in the cloud or self-hosted, with text-to-speech latency stated as low as 80ms.
Very good
Deepgram scores highly because it built for the use case that actually stresses voice infrastructure — real-time agents — rather than for transcription with agents added later. Collapsing speech-to-text, text-to-speech and LLM orchestration into one API removes latency hops that make automated calls feel broken, 80ms synthesis latency is genuinely competitive, and self-hosting is offered as a normal option rather than an enterprise afterthought. The customer list, including Twilio, Cloudflare and IBM, is infrastructure buyers rather than logos. It loses ground because language counts, accuracy figures and compliance certifications are absent from the pages a buyer reads first. AInexfinder Editor Score: 4.4/5.
Best for: Teams building real-time conversational voice agents; Organisations that need on-premise voice processing for compliance
The visit link goes to deepgram.com, the official site. Paid placements on AInexfinder are always labelled. How we make money
Everyone has heard the moment a voice agent fails. You finish speaking, nothing happens, you start to repeat yourself, and the system talks over you. The technology was not wrong — it was late.
That single property, latency, decides whether a voice interface feels like a conversation or like an automated phone menu. And it is where the conventional architecture falls down: chain speech-to-text, then a language model, then text-to-speech, and every hop adds delay that accumulates into exactly that pause.
Deepgram's product decisions all point at that problem. It is worth understanding why, because it explains what the company is good at and what it does not tell you.
Deepgram's Voice Agent API combines speech-to-text, text-to-speech and LLM orchestration into a single API, stated as reducing complexity, latency and cost.
The latency argument is the substantive one. In a chained architecture, audio travels to a transcription service, the text travels to a model, the response travels to a synthesis service, and the audio comes back. Each leg has network time, queuing and processing, and they add rather than overlap.
Human conversational turn-taking has a narrow tolerance. Past roughly a second of silence people assume something has gone wrong and start speaking again, which produces the collision everyone recognises. Removing hops is the only structural way to buy that headroom back — you cannot optimise your way out of three round trips.
The complexity argument matters too, and is less discussed. Three services means three sets of credentials, three failure modes, three billing relationships and three places for a version change to break your agent at two in the morning.
The trade is control, and it is real. A chained pipeline lets you swap in a different language model, tune each stage independently and inspect what happened at each step. An integrated API is faster and gives you fewer places to intervene when something is subtly wrong.
The alternative is assembling the same stack from parts: transcription from one vendor, synthesis from ElevenLabs, orchestration of your own. That is entirely workable, and it leaves you owning three latency budgets instead of one.
You cannot optimise your way out of three network round trips. Removing a hop is the only thing that actually buys latency back.
Deepgram describes Flux STT as conversation-aware and Flux TTS as the first voice model that thinks before it speaks. Both phrases are doing real work, though neither is defined on the site.
For transcription, conversation-awareness most plausibly refers to turn detection — knowing when a speaker has actually finished rather than merely paused. That is the hardest part of real-time speech and the source of most agent interruptions, because a system that treats every pause as a turn will cut people off mid-sentence.
For synthesis, thinking before it speaks suggests the model plans an utterance's prosody before generating audio, rather than producing it word by word. That would explain more natural emphasis and intonation, which is what separates a voice that sounds human from one that sounds like a reader.
Both are plausible and neither is documented in detail on the pages we read. Test them directly: interrupt the agent mid-sentence, pause mid-thought, and see whether it waits or jumps in. Turn handling is where voice agents actually fail, and it is easy to evaluate in five minutes.
Deepgram states that its models run in real time or batch, in the cloud or self-hosted, with dedicated self-hosting documentation.
That single option determines whether the platform is usable for a whole category of buyer. Voice data is unusually sensitive: a recorded call contains a person's voice — which is biometric identity — plus whatever they said, which in healthcare, finance and legal contexts is regulated separately.
For organisations under strict data residency rules or handling protected health information, sending audio to a third-party cloud is frequently prohibited outright, regardless of the vendor's certifications. On-premise deployment removes that objection rather than arguing with it.
What makes Deepgram's position notable is that self-hosting is presented as an ordinary deployment mode rather than an enterprise concession extracted in negotiation. Many competitors treat it as a bespoke arrangement, which in practice means slow and expensive.
The questions to settle before relying on it are practical: what hardware the models need, whether self-hosted versions track cloud releases, and how licensing works. Self-hosted AI infrastructure has real operational cost, and it is worth knowing that cost before choosing it over a compliance conversation you might have won.
Deployment terms are also the axis on which its closest competitors differ. AssemblyAI and Speechmatics each make a different case here, and which matters more is a procurement question rather than a technical one.
Deepgram names Twilio, Cloudflare, Sierra, IBM, Daily, Cresta, Granola, VAPI, Decagon, Kore.ai, NICE-Cognigy and Coval.
This list is worth more scrutiny than a typical logo wall, because of what these companies are. Twilio, Daily and VAPI are communications infrastructure providers. Sierra, Decagon, Cresta and Kore.ai build conversational AI products. These are not end users who bought a subscription; they are companies whose own products depend on the voice layer working.
That kind of customer evaluates differently. An infrastructure provider integrating a speech API tests latency under load, failure behaviour and accuracy on real traffic, because their own reliability inherits from it. Passing that scrutiny repeatedly is stronger evidence than any published benchmark.
It also tells you where Deepgram sits in the market. This is a supplier to the people building voice products, which fits the infrastructure-first positioning and explains why the marketing pages assume an engineering audience.
The corollary for a smaller buyer is that you are buying something built to satisfy demanding integrators, which is generally good — and that the documentation assumes you are one.
If your need is transcription of recorded audio rather than live agents, a service like Rev solves that problem more directly and at far less architectural cost.
Voice infrastructure is unusually easy to evaluate badly, because a demo in a quiet room with clear speech tells you almost nothing about production.
The bar is step three. Turn detection is where voice agents fail, and it fails on real speech rather than on scripted prompts.
Pricing is not disclosed on the pages we read. In this category billing is normally by audio duration for transcription and by characters or duration for synthesis, with self-hosting licensed separately.
That structure means cost scales with usage rather than seats, which suits an infrastructure product — a small team processing heavy volume pays more than a large team processing little, which is the correct shape.
More notable is what else is missing from the marketing pages. No language count appears anywhere we read, which is the first specification most buyers need. No word error rate or accuracy figure is published. No compliance certifications — SOC 2, HIPAA, GDPR — are stated where procurement would look for them, despite self-hosting being offered specifically for regulated buyers.
None of that means the answers are unfavourable; infrastructure companies frequently keep these in documentation or supply them on request. It does mean a buyer cannot complete an evaluation from the website, which is a real friction for a product otherwise aimed at developers who prefer to self-serve.
We do not publish amounts. Request the language list, accuracy data and compliance pack together in your first contact, since you will need all three.
Five terms that determine whether a voice product feels usable.
| Product type | Voice AI infrastructure — speech-to-text, text-to-speech and voice agents |
|---|---|
| Speech-to-text model | Flux STT, described as conversation-aware |
| Text-to-speech model | Flux TTS, described as the first voice model that thinks before it speaks |
| Stated TTS latency | As low as 80ms |
| Voice agents | Voice Agent API combining STT, TTS and LLM orchestration in one API |
| Processing modes | Real time or batch |
| Deployment | Cloud or self-hosted, with dedicated self-hosting documentation |
| Named customers | Twilio, Cloudflare, Sierra, IBM, Daily, Cresta, Granola, VAPI, Decagon, Kore.ai, NICE-Cognigy, Coval |
| Buyer | Developers and companies building voice into their own products |
| Pricing model | Not disclosed on the pages we read |
Flux STT for real-time and batch speech-to-text
Flux TTS for expressive speech synthesis with stated 80ms latency
Voice Agent API combining transcription, synthesis and LLM orchestration in one interface
Conversation-aware turn handling for real-time interaction
Real-time streaming and batch processing modes
Cloud or self-hosted deployment with dedicated documentation
Developer-oriented API surface rather than an end-user application
Used as infrastructure by communications and conversational AI platforms
Voice vendors differ on whether they optimise for transcription accuracy or for agent latency. Those pull in different directions.
| Tool | Optimised for | Self-hosting | Voice agents |
|---|---|---|---|
| Deepgram | Real-time agent latency | Yes, as a normal deployment option | Single-API agent path with 80ms TTS |
| AssemblyAI | Transcription accuracy plus an understanding layer | Not advertised | Voice Agent API over one WebSocket |
| Speechmatics | Language and accent coverage | Deployment options available | Recognition rather than full agents |
| ElevenLabs | Voice generation quality | No | Strong on synthesis, less on recognition |
| Rev | Accuracy including human transcription | No | Not an agent platform |
Last checked . Read from deepgram.com, including the footer, with the screenshot above captured in the same session.
What we could not confirm: no language count or list appears on the pages we read, which is the first specification most buyers need; no word error rate or accuracy figure is published; no compliance certifications such as SOC 2, HIPAA or GDPR are stated on those pages, despite self-hosting being offered for regulated buyers; no pricing is disclosed; the hardware requirements and licensing terms for self-hosting are not described; and we did not build against the API, so nothing here reflects measured latency or accuracy.
Compare on whether a vendor optimised for latency or accuracy, and whether self-hosting is genuinely available.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Deepgram website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Deepgram earns an AInexfinder Editor Score of 4.4/5 (very good). Best for: Teams building real-time conversational voice agents; Organisations that need on-premise voice processing for compliance; Communications platforms embedding voice as infrastructure.
Visit DeepgramLog in to write a review.
No reviews yet. Be the first to share your experience with Deepgram.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Deepgram from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
AI and human transcription and subtitles in 150+ languages
AssemblyAI sells voice AI infrastructure: production APIs for pre-recorded and real-time speech-to-text on its Universal models, a Speech Understanding API that turns transcripts into structured insight, a Voice Agent API over a single WebSocket, and guardrails including PII redaction and content moderation.
Rev has repositioned from transcription into an investigative intelligence platform for legal teams, combining AI evidence analysis with human-verified transcription guaranteed 99%+ accurate in 12 hours, plus court reporting, deposition summaries and a speech-to-text API.
Cockatoo transcribes audio and video across 100+ languages with a stated accuracy of up to 99.8%, exports to SRT, DOCX, PDF and TXT, imports from Dropbox and YouTube, and offers three free transcripts daily with no card required.

ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.

Runway is an AI video platform built around generative world models — Gen-4.5, Aleph 2.0, and Act-Two for performance capture — split across Runway Creative for filmmakers, Runway Dev for builders, and Runway Robotics.
Related Pages