AI and human transcription and subtitles in 150+ languages
Video & Audio Review
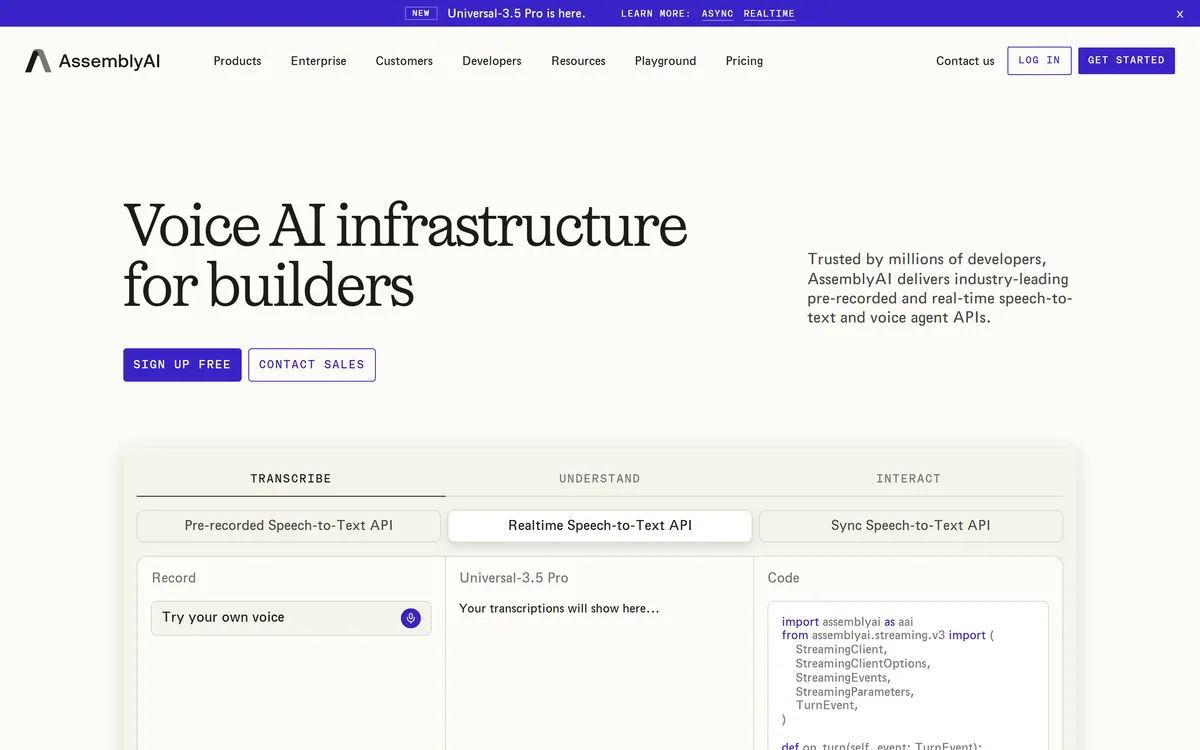
AssemblyAI sells voice AI infrastructure: production APIs for pre-recorded and real-time speech-to-text on its Universal models, a Speech Understanding API that turns transcripts into structured insight, a Voice Agent API over a single WebSocket, and guardrails including PII redaction and content moderation.
Very good
AssemblyAI scores highly because it sells to the right buyer in the right shape: developers who need speech as infrastructure, given documented models, a streaming path, and an understanding layer that turns a transcript into something a product can act on. Splitting Universal-3.5 Pro for accuracy from Universal-2 for breadth of language coverage is an honest acknowledgement that no single model wins on both. It loses ground because the marketing pages do not publish word error rates, language counts or compliance certifications where a buyer would look for them, so the specifications that decide a build have to be dug out of documentation. AInexfinder Editor Score: 4.4/5.
Best for: Product teams embedding speech recognition in their own applications; Voice agent builders where conversational latency is the experience
The visit link goes to assemblyai.com, the official site. Paid placements on AInexfinder are always labelled. How we make money
There is a category error that costs teams months, and it is worth naming before anything else: a transcription product and a speech API are not the same purchase.
A transcription product such as Otter.ai gives you an interface, a file list and an export button. A speech API gives you an endpoint, and everything a user would touch is yours to build. Buying the second when you wanted the first means paying to develop a product you could have subscribed to.
AssemblyAI is unambiguously the second. It describes itself as voice AI infrastructure for developers, and every part of the platform assumes there is an engineering team on the other side. This review covers what the models do, why the understanding layer matters more than the transcript, and the specifications you will have to dig for.
AssemblyAI documents two pre-recorded models with an explicit division of labour. Universal-3.5 Pro is described as the highest-accuracy model and the recommended default. Universal-2 is positioned for broad language coverage and legacy feature support.
That split is more useful than a single flagship, and the honesty is worth crediting. Speech recognition accuracy and language breadth pull against each other — the best English model is rarely the best Vietnamese one, because the training data and the acoustic modelling differ.
For a buyer the implication is concrete. If your audio is English-language customer calls, take the Pro model and expect the better result. If your product serves a long tail of languages, check Universal-2's coverage against your actual language mix before committing, because a model that is excellent in twelve languages is useless if your users speak the thirteenth.
Around the models sit the features that make transcripts usable: speaker labels for diarisation, word-level timestamps, language detection, custom spelling, key terms, and medical terminology support. Custom spelling matters more than it sounds — every product has proper nouns, product names and jargon that a general model will render phonetically and wrongly, forever, until you tell it otherwise.
The best English model is rarely the best model for your thirteenth language. A vendor offering two and telling you which is which is being straight with you.
No speech system is perfect, and the way they fail matters more than the rate at which they fail.
Recognition errors are not random. They cluster on exactly the words that carry meaning — names, numbers, technical terms, and anything spoken quickly or over background noise. A transcript can be 95 per cent accurate overall and wrong on the account number, which is the only part anyone needed.
This has a direct design consequence. If a transcript drives an automated action — routing a case, updating a record, triggering a payment — build a confidence threshold and a human path for anything below it. Word-level timestamps exist partly so a person can jump to the audio and check rather than reading the whole thing.
It also means you should measure on your own audio rather than trusting any benchmark. The same caution applies to Speechmatics and every rival: vendor accuracy figures are measured on clean corpora; your audio has hold music, crosstalk, accents and a caller in a car. Transcribe fifty of your own recordings, count the errors that would actually matter, and that number is the only one worth planning around.
AssemblyAI sells a Speech Understanding API for structured insight from transcripts, separately from the transcription itself. That separation reflects where the real work sits.
A transcript is not an answer. Nobody wants ten thousand words of a support call; they want to know what the customer asked for, whether it was resolved, how the caller sounded, and whether anything needs escalating. Getting from one to the other used to mean building a second pipeline with its own models and its own maintenance burden.
Buying that layer rather than building it is usually the right call for a product team, for an unglamorous reason: the second pipeline is the one that rots. Transcription is stable; summarisation, classification and sentiment analysis have to be revised every time the underlying models improve, and that is a permanent cost on your roadmap rather than a one-off.
Pairing it with a voice generator such as ElevenLabs completes an agent, and the LLM Gateway points at the same idea — a route to language models over the same platform, so the understanding step does not require separate vendor management.
The judgement to apply is where the derived output is trusted. Summaries are fine as an aid to a human reading the transcript. Sentiment scores driving an automated escalation decision deserve considerably more scepticism, because inferring emotional state from words is unreliable in exactly the cases — sarcasm, restraint, cultural difference — where it would matter.
The Voice Agent API runs speech-to-speech agents over a single WebSocket, and the architectural detail in that sentence is the whole point.
The conventional way to build a voice agent chains three services: speech-to-text, then a language model, then text-to-speech, each with its own connection and its own latency. The delays add, and the result is the stilted pause everyone recognises from automated phone systems — the thing that makes callers press zero.
Collapsing that into one connection is a latency argument rather than a feature. Conversational turn-taking has a fairly narrow tolerance; past roughly a second of silence, people start talking over the system or assume it has failed. Every hop you remove buys headroom.
The trade is control. A chained pipeline lets you swap the language model, tune the voice, and inspect each stage independently. A single integrated path is faster and gives you fewer places to intervene.
The right choice follows from what the agent does. For a scripted, high-volume interaction where speed is the experience — checking an order, booking a slot — integrated latency wins. For an agent that needs careful reasoning, tool use and auditable steps, the chained approach remains easier to build and debug.
Every speech vendor publishes accuracy measured on clean corpora, and your audio is not clean. The only benchmark that predicts what you will get is one you run yourself, and it takes an afternoon.
The bar is step four. An error rate on words that carry meaning is the number your product actually depends on, and it is very different from an overall rate.
Speech APIs in this category are metered by audio duration rather than by seat, and the practical unit is hours or minutes of audio processed.
That model has a property worth designing around: cost scales with volume, not with team size. A three-person startup processing a large volume of calls pays more than a hundred-person company processing few, which is unusual and generally fair.
The variables that move a bill are duration, whether you use the real-time path, and how many understanding features you layer on. Streaming is typically priced differently from pre-recorded because it is a different service, and each derived output is additional work.
The engineering lever most teams miss is not sending audio you do not need. Silence trimming, voice activity detection, and simply not transcribing hold music are the difference between a predictable bill and a surprising one at scale.
We do not publish amounts, since rates change. Model your cost on real audio duration from a representative week, and check whether committed-volume terms exist before you scale — in this category they usually do, and they are worth asking about.
| Product type | Voice AI infrastructure — APIs, not an end-user application |
|---|---|
| Pre-recorded models | Universal-3.5 Pro (highest accuracy, recommended default) and Universal-2 (broader language coverage, legacy features) |
| Real-time | Streaming speech-to-text as a separate API |
| Voice agents | Voice Agent API running speech-to-speech over a single WebSocket |
| Understanding layer | Speech Understanding API for structured insight from transcripts |
| Model access | LLM Gateway for language model calls through the same platform |
| Transcript features | Speaker labels, word-level timestamps, language detection, custom spelling, key terms, medical terminology, transcript post-processing |
| Guardrails | PII redaction, profanity filtering, content moderation |
| Buyer | Developers and product teams building speech into their own applications |
| Pricing model | Usage-based on audio duration; streaming and pre-recorded priced separately |
Five terms that determine whether a speech platform fits what you are building.
Universal-3.5 Pro for highest-accuracy pre-recorded transcription
Universal-2 for broader language coverage and legacy feature support
Real-time streaming speech-to-text as a separate API path
Voice Agent API running speech-to-speech agents over a single WebSocket
Speech Understanding API producing structured insight from transcripts
Speaker labels, word-level timestamps and automatic language detection
Custom spelling and key terms for product names, proper nouns and jargon
Guardrails covering PII redaction, profanity filtering and content moderation
Speech vendors differ on whether they sell you an endpoint or a finished product. Buying the wrong shape is the most expensive mistake in this category.
| Tool | Sells | Strongest at | Watch out for |
|---|---|---|---|
| AssemblyAI | APIs for developers | Documented models plus an understanding layer you would otherwise build | Specs like WER, language counts and certifications are not on the marketing pages |
| Speechmatics | APIs for developers | Breadth of language and accent coverage | Compare on your own audio, not on published benchmarks |
| Rev | A finished transcription service, plus an API | Human transcription where accuracy must be near-perfect | Human review costs more and takes longer than an API call |
| Otter.ai | A meeting product for end users | Meeting notes with no engineering work at all | Not infrastructure — you cannot build a product on it |
| Notta | A transcription app | Fast multilingual note-taking for individuals | Same shape mismatch if you need an API |
Last checked . Read from assemblyai.com, including the speech-to-text product page, with the screenshot above captured in the same session.
What we could not confirm: no word error rate or accuracy figure is published on the pages we read; the number of supported languages is not stated on either the homepage or the speech-to-text product page; compliance certifications such as SOC 2, HIPAA and GDPR are not stated there either, so request them directly if procurement requires them; SDK languages and streaming latency figures are not given on those pages; and no company legal name, headquarters or funding detail appears on them.
The first question is whether you need an API or an application. Everything else follows from that.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official AssemblyAI website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
AssemblyAI earns an AInexfinder Editor Score of 4.4/5 (very good). Best for: Product teams embedding speech recognition in their own applications; Voice agent builders where conversational latency is the experience; Teams handling regulated audio who need PII redaction at ingest.
Visit AssemblyAILog in to write a review.
No reviews yet. Be the first to share your experience with AssemblyAI.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research AssemblyAI from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
AI and human transcription and subtitles in 150+ languages
Rev has repositioned from transcription into an investigative intelligence platform for legal teams, combining AI evidence analysis with human-verified transcription guaranteed 99%+ accurate in 12 hours, plus court reporting, deposition summaries and a speech-to-text API.
Deepgram provides speech-to-text and text-to-speech through its Flux models, plus a Voice Agent API that combines transcription, speech synthesis and LLM orchestration into a single interface. Everything runs in real time or batch, in the cloud or self-hosted, with text-to-speech latency stated as low as 80ms.
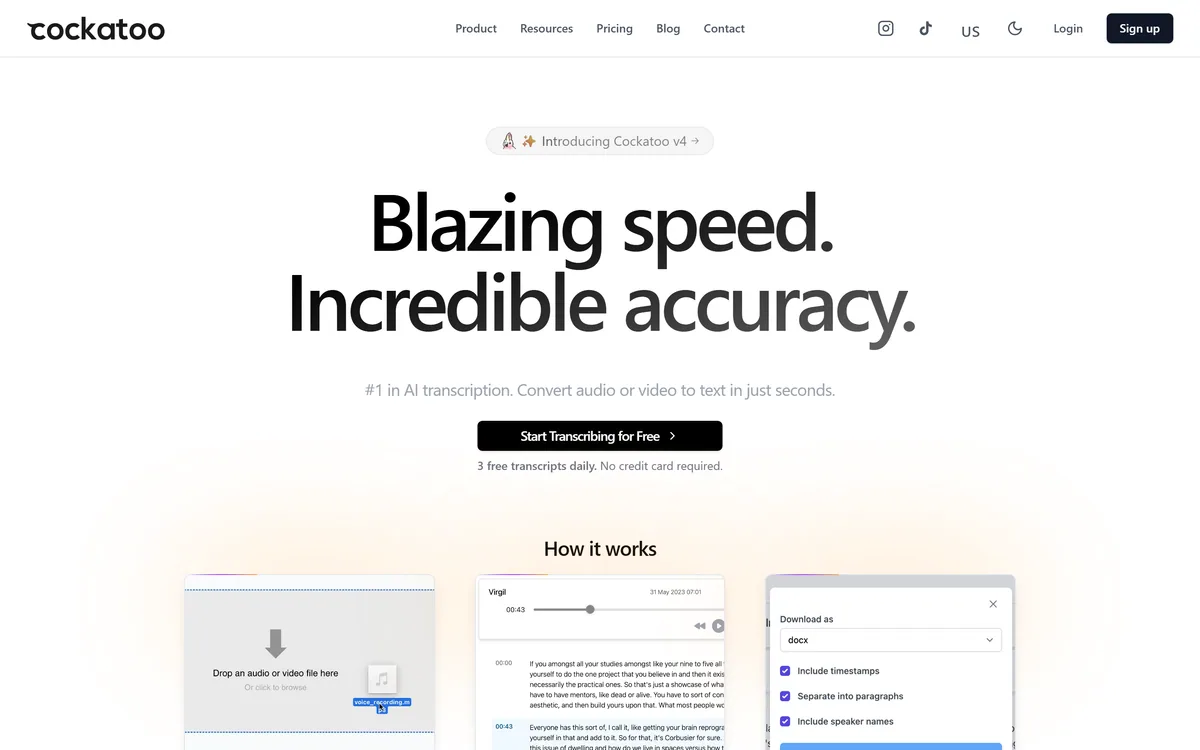
Cockatoo transcribes audio and video across 100+ languages with a stated accuracy of up to 99.8%, exports to SRT, DOCX, PDF and TXT, imports from Dropbox and YouTube, and offers three free transcripts daily with no card required.

ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.

Runway is an AI video platform built around generative world models — Gen-4.5, Aleph 2.0, and Act-Two for performance capture — split across Runway Creative for filmmakers, Runway Dev for builders, and Runway Robotics.
Related Pages