
ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.
Video & Audio Review
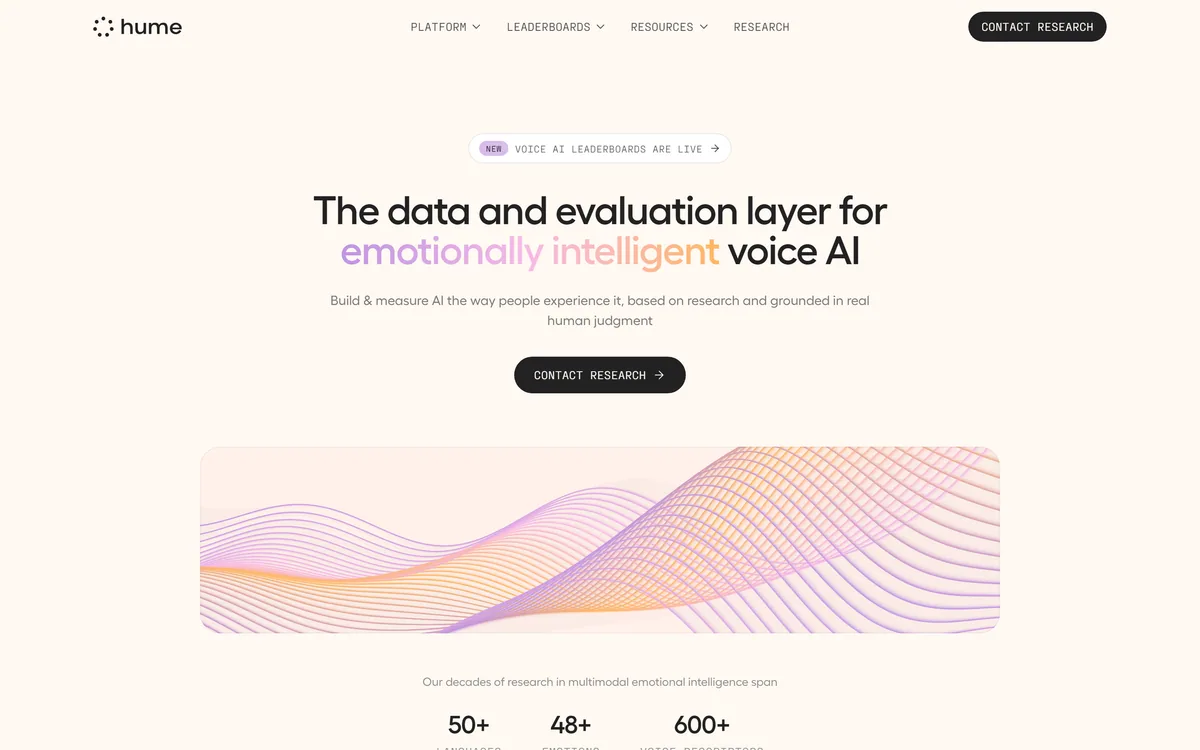
Hume AI supplies data and evaluation infrastructure for voice AI teams: custom data collection, the Kairos simulation and evaluation platform, an expression measurement API covering 48-plus emotions across 50-plus languages, and a human feedback API returning scored ratings from pre-screened participants in hours.
Very good
Hume AI has built the thing this field has been missing. Voice agents are judged on metrics that measure accuracy while people judge them on whether they want to keep talking, and nothing bridged those two until someone put human raters behind an API. Publishing leaderboards is good; publishing a leaderboard of the automated judges — ranking which small models track human ratings most closely — is a genuinely original contribution, because it tells you which cheap evaluator you can actually trust. This is infrastructure for teams shipping voice, not a product for end users. AInexfinder Editor Score: 4.4/5.
Best for: Teams building voice models rather than consuming them; Conversational AI products where tone is part of the experience
The visit link goes to hume.ai, the official site. Paid placements on AInexfinder are always labelled. How we make money
Every voice AI team hits the same wall. The word error rate is good, latency is inside target, the transcripts look fine — and people still hang up.
That gap exists because the metrics measure whether the system was accurate, while users are deciding whether they want to keep talking to it. Those are different questions with different answers.
Hume AI's proposition is to make the second question measurable: put real people behind an API, get scored ratings back in hours, and treat human judgement as infrastructure rather than as a research project.
Hume frames voice quality as three layers: reliability, safety and trustworthiness at the base; expressivity, naturalness and flow above it; and emotional intelligence at the peak, described as the dimension that determines whether people actually want to keep talking.
That hierarchy is the most useful thing on the page, because it explains why teams optimise the wrong thing.
The base layer is where all the standard metrics live — recognition accuracy, uptime, refusal behaviour. It is table stakes, it is measurable, and it is what every dashboard shows.
The middle layer is where most complaints actually originate. An agent that is accurate but stilted, or interrupts, or delivers a joke in the same tone as a refund policy, fails on expressivity while scoring perfectly on accuracy.
The top layer is the one nobody can measure with a metric, and Hume states this directly: metrics measure accuracy, while expression, emotion and alignment require human judgement. That is an honest admission from a company selling measurement, and it defines exactly what it is selling.
Metrics tell you the system was accurate. People are deciding whether they want to keep talking. Those are different questions.
Alongside four leaderboards ranking voice models, Hume publishes a fifth that is different in kind: not a model leaderboard but a leaderboard of the judges, ranking which small language models track human ratings most closely.
This is the most original idea on the site and worth explaining, because it addresses the central practical problem with human evaluation.
Human ratings are the gold standard and they are slow and expensive. So every team eventually uses a model as an automated judge to score outputs at volume — and then has no idea whether that judge agrees with the humans it replaced.
Measuring the agreement directly, and publishing it, tells you which cheap evaluator is safe to run at scale and which one is quietly rewarding the wrong things.
It is the same insight that makes evaluation frameworks like Promptfoo useful — a test suite is only as good as the assertion behind it — applied one level up, to the assertion itself.
Kairos is described as letting voice teams build evaluation suites from real-world use cases, simulate agent-to-agent and human-to-agent conversations, and track regressions over time.
Simulation is what makes voice evaluation tractable at all, and the reason is arithmetic.
A voice agent's behaviour depends on what the caller says, and callers say an unbounded number of things. Testing by hand means someone calling the system repeatedly, which caps you at dozens of conversations per release and misses the interaction that actually breaks it.
Agent-to-agent simulation removes that cap. One model plays a difficult caller — interrupting, changing its mind, going off-topic — while the system under test responds, and you can run thousands of those.
Regression tracking is the half that matters over time. Voice systems get worse in ways nobody notices: a prompt change fixes one behaviour and breaks turn-taking; a model upgrade improves accuracy and flattens tone. Without a scored suite running every release, you find out from a customer. Designing the agent under test is a separate discipline, handled on a canvas by Voiceflow.
The Real World VoiceEQ benchmark spans four leaderboards — speech recognition, speech understanding, text-to-speech and speech-to-speech — ranked by human judgement rather than automated scoring.
Publishing a benchmark you also sell services around invites an obvious question, and it is worth addressing rather than ignoring.
The mitigation is that the benchmark ranks other companies' models rather than a product Hume sells into the same comparison, and that the evaluation questions are published. The site lists them plainly: does the voice fit the persona, does the model sustain character voices when reading a story, are jokes and reassurances delivered in distinct tones, can it reliably read out web search results.
Those are unusually concrete evaluation criteria, and publishing them is what makes a benchmark checkable rather than merely authoritative.
The remaining caution applies to any vendor-published benchmark: read the methodology, note who funded it, and treat the ranking as one input. That the criteria are this specific makes it easier to do, not harder.
The human feedback product is described as pre-screened participants returning per-sample scores, free-response feedback and aggregated analysis in hours rather than days, through a single API call from study creation to results.
Turning human evaluation into an API call is a bigger operational change than it sounds.
Running a human study conventionally means recruiting, screening, briefing, distributing, chasing, and cleaning the results — days of coordination that no engineering team wants to own, which is why human evaluation gets skipped and automated proxies get used instead.
Collapsing that to one request changes when it happens. Evaluation that takes hours can run inside a development cycle; evaluation that takes days runs before a launch and never again.
Screening and quality monitoring are the parts to interrogate. Paid rating populations attract bad-faith responses, and the difference between a carefully screened panel and a poorly monitored one is the difference between data and noise. Hume names screening and quality monitoring as built in — the questions for procurement are how participants are recruited, what the exclusion criteria are, and how disagreement between raters is handled. None of it replaces the telephony layer, where an open framework like Vocode does the unglamorous work.
Voice agents fail in production on the dimensions nobody instrumented, and by then the users who left are not coming back to tell you why.
This sequence builds evaluation in the order the layers actually matter.
| Company | Hume AI, Inc., per the footer |
|---|---|
| Positioning | The data and evaluation layer for emotionally intelligent voice AI |
| Research scope | 50-plus languages, 48-plus emotions and 600-plus voice descriptors |
| Product one | Data solutions — custom collection around your scenarios and evaluation requirements |
| Product two | Kairos — evaluation suites, conversation simulation and regression tracking |
| Product three | Expression measurement API, real-time and offline |
| Product four | Human feedback API with pre-screened raters, in hours rather than days |
| Benchmark | Real World VoiceEQ, across four leaderboards ranked by human judgement |
| Meta-benchmark | An SLM judge leaderboard ranking which models track human ratings most closely |
| Quality model | Three layers — reliability and safety, expressivity and flow, emotional intelligence |
| Screening | Participant screening and quality monitoring stated as built in |
| Community | Discord, plus published research and publications pages |
Human feedback API with pre-screened raters
Kairos evaluation suite building from real use cases
Agent-to-agent and human-to-agent conversation simulation
Regression tracking across releases
Real-time and offline expression measurement
48-plus emotion categories across 50-plus languages
Public voice AI leaderboards ranked by human judgement
A leaderboard ranking automated judges against human ratings
Evaluation tooling differs by modality and by who does the judging.
| Tool | Evaluates | Judged by | Best for |
|---|---|---|---|
| Hume AI | Voice, speech and conversation | Human raters, plus ranked judges | Teams building voice models and agents |
| Promptfoo | LLM outputs and prompt injection | Assertions and red teaming | Teams shipping text AI features |
| Voiceflow | Nothing — it builds agents | Not applicable | Designing the agent being evaluated |
| Vocode | Nothing — it runs calls | Not applicable | The telephony layer underneath |
| Testsigma | Functional software behaviour | Automated test agents | Regression testing outside AI |
Other layers of the stack around building and testing voice systems.
Last checked . Read from hume.ai in a browser session on the date above, including the full footer. The screenshot was captured at the same time.
What we could not confirm: how raters are recruited, what the exclusion criteria are, or how disagreement between raters is resolved; the methodology behind the Real World VoiceEQ benchmark, which is published by a company selling services in the same area; how the 48 emotion categories were derived or validated; what a single API call covers operationally for a study; and pricing, which requires contacting the research team. We did not run an evaluation.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Hume AI website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Hume AI earns an AInexfinder Editor Score of 4.4/5 (very good). Best for: Teams building voice models rather than consuming them; Conversational AI products where tone is part of the experience; Engineering teams whose metrics look fine while users leave.
Visit Hume AILog in to write a review.
No reviews yet. Be the first to share your experience with Hume AI.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Hume AI from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.
PlayHT review on AInexfinder — freemium AI tool for Video & Audio. Features, pricing notes, and alternatives.
TTSReader turns text, PDFs, and EPUB files into speech in the browser, with voice and language selection, speed control, text highlighting, and MP3 export — the free tier runs on browser voices with no usage cap.
VMEG from PixRipple translates and dubs video into 170+ languages using 17,000+ voices, with voice cloning, lip-sync, subtitle generation, batch processing, and API and MCP access for automated localisation.
AI and human transcription and subtitles in 150+ languages

Runway is an AI video platform built around generative world models — Gen-4.5, Aleph 2.0, and Act-Two for performance capture — split across Runway Creative for filmmakers, Runway Dev for builders, and Runway Robotics.
Related Pages