
Claude is Anthropic's AI assistant, available on web, desktop, mobile, and in Chrome, with Projects for persistent context, Artifacts for generated documents and apps, Skills, Connectors, and Claude Code for developers.
AI Chatbots & Assistants Review
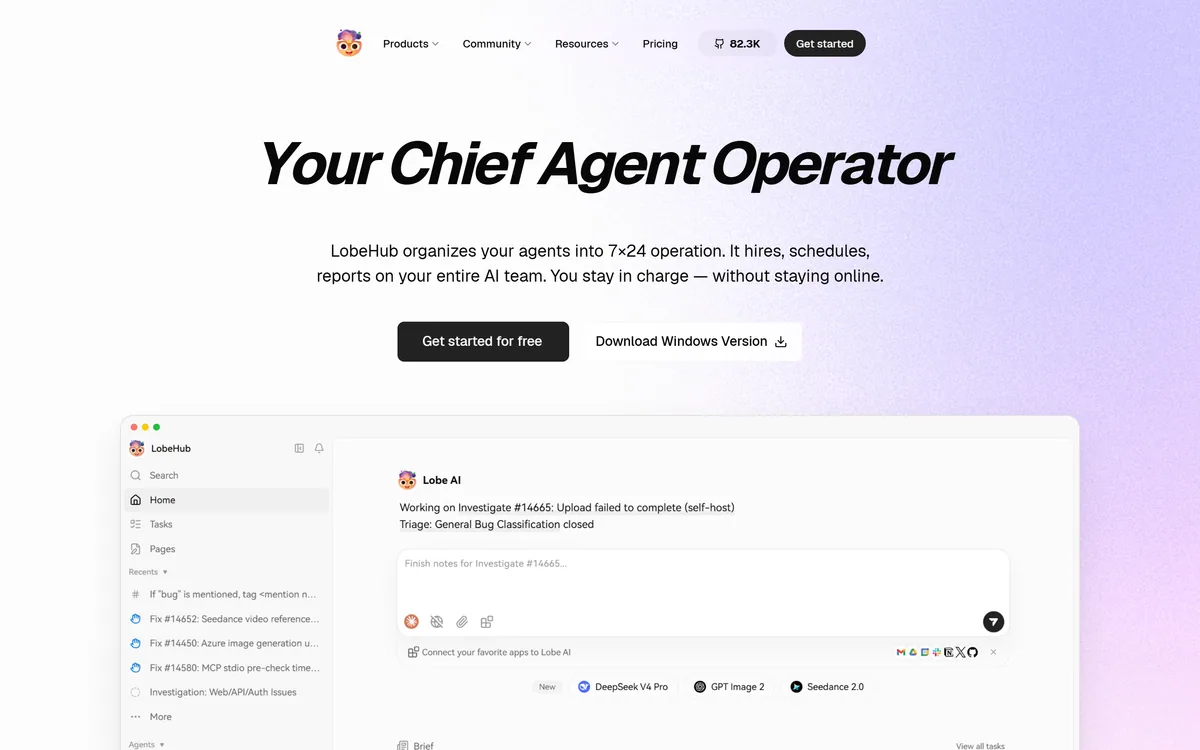
LobeHub has grown from an open-source universal chat interface into what it calls a Chief Agent Operator: a system that assembles agents from a skills marketplace, runs them continuously, groups them into teams for parallel work, and reports back through the chat tools you already use.
Very good
LobeHub started as the open-source chat interface everyone recommended for running any model in one place, and it has repositioned around something considerably more ambitious: operating a fleet of agents that run whether or not you are watching. White-box memory — structured and editable rather than opaque — is the feature that makes that defensible, because an agent acting on a wrong belief is only fixable if you can see what it believes. The scale claims are enormous and the marketplace numbers deserve reading carefully. AInexfinder Editor Score: 4.2/5.
Best for: Teams with recurring work that separates into parallel tasks; Developers who want model choice and key ownership
The visit link goes to lobehub.com, the official site. Paid placements on AInexfinder are always labelled. How we make money
LobeHub's framing is unusually specific: it organises your agents into round-the-clock operation, hiring, scheduling and reporting on your entire AI team, so you stay in charge without staying online.
The word doing the work is operation, and it names a problem that only appears once agents actually work.
A single agent you supervise is a tool. Ten agents running unattended is an operation, and operations need things tools do not: someone deciding what runs, a schedule, a record of what happened, and a way of finding out when something went wrong.
That is a management problem rather than a modelling one, and it is exactly the layer most agent products skip — they make agents easier to create and leave you to work out what happens next.
Its own example is illustrative: five hundred open issues, fifty agents dispatched, and the user went to bed. Whether that is a good idea depends entirely on how reviewable the output is, which is the question the memory design below is trying to answer.
One agent you supervise is a tool. Ten running unattended is an operation, and operations need a schedule, a record, and a way to find out what broke.
Among the features under an Evolve heading sits the most important one: white-box memory, described as structured and editable, alongside personal memory, continual learning and adaptive behaviour.
Editable memory is the feature that makes long-running agents governable, and almost nothing else has it.
The failure mode with persistent memory is specific and infuriating. An agent forms a wrong belief — that you prefer a format you do not, that a project ended when it did not, that a colleague holds a role they left — and then acts on it consistently. Every subsequent output is subtly wrong for a reason you cannot see.
With opaque memory the only remedy is to reset everything and lose what was correct. With structured, editable memory you open it, find the wrong entry and change it.
That difference matters more the longer agents run and the less you watch them, which is precisely the mode this product is built for. Continual learning without inspectable memory is a system that drifts and cannot be corrected.
The site displays a skills marketplace counted in the hundreds of thousands and MCP servers counted in the tens of thousands, alongside an agent marketplace and an agent builder that configures names, roles, skills and behaviours from one sentence.
Those numbers deserve reading as listings rather than as capabilities.
Marketplace counts in this category are inflated by the same dynamics everywhere: many entries are variations, many are unmaintained, and a large proportion of any listing directory has never been used by anyone but its author. A community post quoted on the same page cites a different skill figure entirely, which suggests the number moves quickly.
What the count does establish is that the platform bet on MCP early and built around it, and that is the strategically correct bet — a standard interface means agents reach systems nobody wrote a bespoke connector for.
The agent builder taking one sentence and configuring role, skills and behaviour automatically is the more practical feature. The barrier to using agents has never been capability; it has been that configuring one properly takes longer than doing the task. Hosted assistants like Kimi remove that setup entirely, and remove the control along with it.
Under a Collaborate heading the site describes agent groups working as real teammates, with automatic team formation, parallel collaboration, multi-task execution and iterative improvement, alongside Pages written by multiple agents sharing context, plus projects, schedules and a shared workspace.
Multi-agent collaboration is the least proven idea in this field, and it is worth separating the plausible part from the speculative.
The plausible part is parallelism on separable work. Fifty independent issues genuinely can be worked in parallel, because nothing about issue seven depends on issue twelve. That is a scheduling win and it is real.
The speculative part is agents improving each other's work iteratively. Models are poor judges of quality, including their own, and a group that agrees with itself can converge confidently on something wrong — with more conviction than a single agent would have managed.
The shared context in Pages is the mitigating design. Agents working from one visible document rather than passing messages means you can read what they collectively believe, which is the only practical way to supervise a group at all. Evaluating what a group actually produced is a separate discipline, and Promptfoo's.
The community quotes on the page tell the product's history plainly: an open source ChatGPT interface, a universal LLM web UI, one-click installable on any local machine, with tens of thousands of stars on a public repository.
That heritage is worth weighing alongside the new positioning, because the two serve different people.
The original proposition was control — run any model, keep your keys, host it yourself, own the interface. That audience cares about independence, and it is why the project accumulated the following it did.
The Chief Agent Operator positioning is a hosted, managed proposition. Agents running around the clock in the cloud with reports arriving in Slack is not something you run on a laptop, and the two versions of the product pull in opposite directions.
The site still offers a desktop download and states any model under your control, so both appear to be available. Anyone choosing it for the original reason should verify how much of the new capability survives self-hosting, because that is exactly the sort of thing that quietly becomes cloud-only — the same tension Khoj navigates between its hosted and self-hosted versions.
The step from using an agent to operating a fleet is where people either get real leverage or create a mess nobody can audit.
This sequence builds the oversight before the scale.
| Positioning | Your Chief Agent Operator — hires, schedules and reports on your AI team |
|---|---|
| Operating model | Agents in continuous operation, described as round the clock |
| Agent creation | One-sentence builder configuring names, roles, skills and behaviours automatically |
| Skills marketplace | Counted in the hundreds of thousands on the homepage |
| MCP servers | Counted in the tens of thousands |
| Collaboration | Agent groups with automatic team formation and parallel execution |
| Shared surfaces | Pages, projects, schedules and a team workspace |
| Memory | Personal memory, continual learning, adaptive behaviour and white-box editable memory |
| Model support | Any model, any modality, stated as under your control |
| Reporting | An IM gateway putting agents in the chat tools you already use |
| Clients | Web plus a downloadable Windows version |
| Heritage | Open source, with a public repository and community endorsements from named developers |
Continuous, scheduled agent operation
One-sentence agent builder
Skills marketplace and MCP server directory
Agent groups with automatic team formation
Shared Pages written by multiple agents
Projects and a team workspace
White-box editable memory
Reporting through existing chat tools
Agent tooling differs by who operates the agents and where they run.
| Tool | Operates | Hosting | Best for |
|---|---|---|---|
| LobeHub | A fleet, scheduled and reported on | Cloud, with a desktop version | Running agents unattended |
| Kimi | Agents you task per request | Hosted only | Producing artefacts on demand |
| Khoj | One assistant over your documents | Hosted or self-hosted | Personal knowledge |
| Warp | Coding agents, measured | Your cloud or theirs | Software engineering specifically |
| Promptfoo | Nothing — it tests them | Local or CI | Evaluating what your agents do |
Other tools across agents, self-hosting and evaluation.
Last checked . Read from lobehub.com in a browser session on the date above, with the screenshot captured at the same time.
What we could not confirm: our capture did not reach the site footer, so we make no claim in either direction about what is published there, including the operating company or licence terms. We also could not confirm how the skills marketplace count is calculated, since a community post on the same page cites a different figure; how much of the Chief Agent Operator capability works in a self-hosted deployment; what the open-source licence covers relative to the hosted product; where agent execution and data reside; and pricing. We did not deploy an instance or run an agent.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official LobeHub website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
LobeHub earns an AInexfinder Editor Score of 4.2/5 (very good). Best for: Teams with recurring work that separates into parallel tasks; Developers who want model choice and key ownership; Anyone already building with MCP servers.
Visit LobeHubLog in to write a review.
No reviews yet. Be the first to share your experience with LobeHub.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research LobeHub from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Claude is Anthropic's AI assistant, available on web, desktop, mobile, and in Chrome, with Projects for persistent context, Artifacts for generated documents and apps, Skills, Connectors, and Claude Code for developers.

ChatGPT is OpenAI's AI assistant, covering conversation, document and image work, web browsing, Projects, Tasks, custom GPTs, agent actions, and the Codex coding agent, across web, desktop, and mobile.

Perplexity AI is an answer engine that runs live web searches and returns cited answers, with Deep Research for long agentic reports, Spaces for persistent projects, the Comet browser, and the Sonar API for developers.
AI speaking tutor for natural language conversations Category: AI Chatbots & Assistants.
Naver's Korean-optimized AI assistant and chatbot Category: AI Chatbots & Assistants.
Open-source workspace to build and deploy AI agents Category: AI Chatbots & Assistants.
Related Pages