
ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.
Video & Audio Review
PolyAI is an enterprise platform for building and governing voice agents, powered by Raven, a proprietary model it states was trained on over a billion enterprise conversations, with a frontier dialog model called Dialog-RSN-1 and published customer outcomes across health, hospitality, retail and delivery.
Very good
PolyAI has aimed at the part of voice automation everyone else avoids: the calls that are already going badly. Financial-crime reports, outages, triage and multilingual disputes are named on the homepage as the proving ground, and that is a meaningfully harder claim than handling appointment bookings. The published compliance posture is the right one for the sector, the customer names are real and checkable, and a Forrester economic impact study exists — but the outcome figures are single-customer results, and a 75 percent resolution rate at one company predicts very little about yours. AInexfinder Editor Score: 4.4/5.
Best for: Contact centres in regulated industries; Organisations handling calls in several languages
The visit link goes to poly.ai, the official site. Paid placements on AInexfinder are always labelled. How we make money
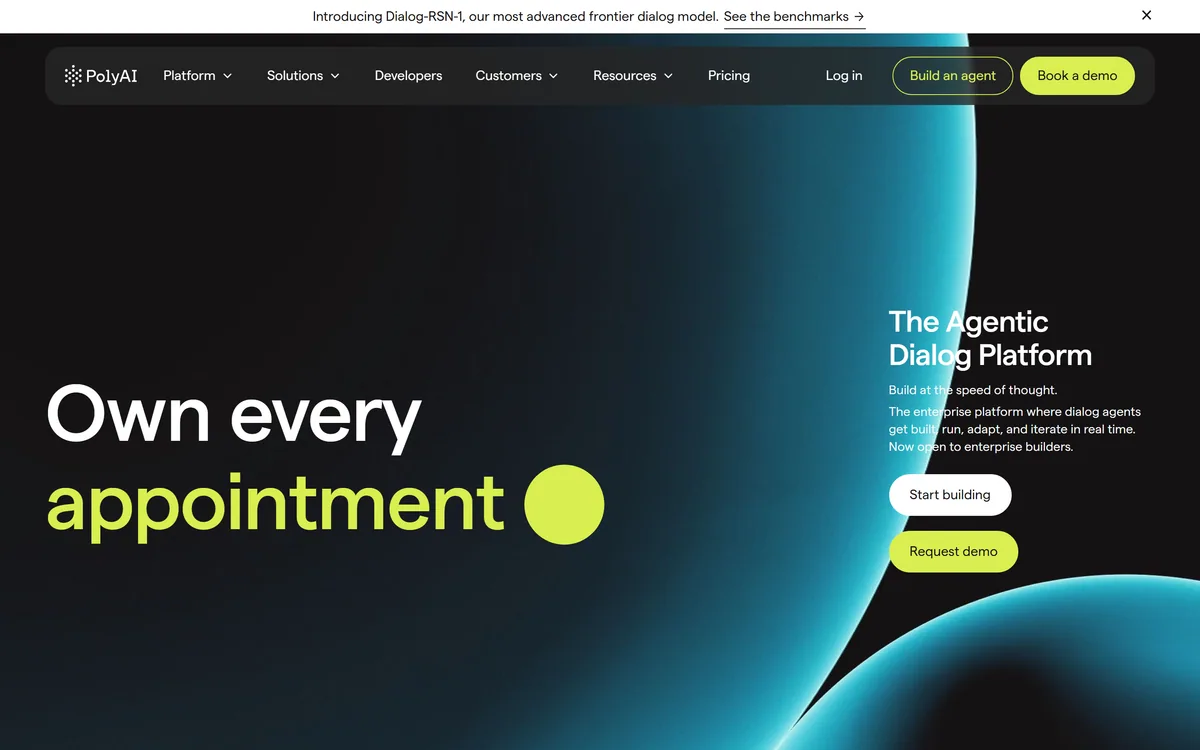
PolyAI describes an agentic dialog platform where enterprise agents get built, run, adapted and iterated in real time, and it names the proving ground precisely: financial-crime reports, outage, triage and multilingual disputes.
That list is the most informative thing on the page, because of what it excludes.
The easy voice automation problems are transactional and cooperative. A caller wants to check a balance or book a table, knows what they want, and follows the prompts. Those calls have been automatable for years, and every vendor demonstrates them.
The calls in PolyAI's list share the opposite properties. The caller is stressed, the situation is unusual, the required information is not on a script, and the conversation will not proceed in order. Someone reporting a compromised card interrupts, backtracks and supplies details out of sequence.
Choosing to be measured on those is a defensible strategic position, and it is also the reason the platform's guardrail and governance features are prominent rather than buried. An agent handling a disputed-transaction report is one bad sentence away from a regulatory problem. At the other end of the market, Phonely AI addresses businesses whose problem is simply that nobody answers the phone.
The easy calls are transactional and cooperative. Financial-crime, outage and triage calls are none of those things — the caller is stressed, off-script and out of order.
The site's claim is the world's most lifelike voice AI agents, and one customer quote sharpens it usefully: it did not sound robotic, it sounded like one of our own agents.
Lifelike is widely misunderstood as a property of the voice, and it is mostly not.
Speech synthesis stopped being the bottleneck some time ago. Modern voices are, in isolation, close to indistinguishable from a recording. What still gives a system away is everything around the words: when it starts speaking, whether it can be interrupted, what it does when you change your mind halfway through a sentence.
Those are dialog problems, not audio problems, which is precisely why PolyAI insists on the phrase dialog-native and states plainly that this is not voice bolted onto chat.
That distinction is architectural. A chat system handles a turn, produces a reply and waits. A dialog system must handle overlapping speech, repair its own mistakes mid-utterance, and decide whether a two-second pause means the caller is thinking or finished. Getting that wrong is the tell, and no amount of voice quality compensates for it. Compact platforms such as Vogent compete on exactly this dimension rather than on model scale.
The Raven model is stated as proprietary and trained on over a billion enterprise conversations. Whatever else that number means, it points at the correct training distribution: enterprise service calls sound nothing like the internet text most models learn from.
Three mechanics decide whether callers accept a voice agent, and none of them appear in a marketing comparison table.
Barge-in comes first. A caller who has heard the greeting before wants to say what they need immediately, and a system that talks over them fails at the first exchange.
Latency comes second, and the tolerance is much tighter than people expect. Gaps in human conversation average around two hundred milliseconds. A delay of a full second is not perceived as slow — it is perceived as a machine, and the caller adjusts their behaviour accordingly, speaking in the flattened voice people use with automated systems.
Turn taking is the hardest of the three. Deciding whether a pause means finished or thinking has no reliable acoustic answer, and both errors are costly: cutting someone off is rude, and waiting too long is uncanny.
The practical consequence for a buyer is that these must be tested on real calls with real accents, real background noise and real hold music, not in a demo. Every platform sounds excellent in a demo, because a demo is a cooperative caller in a quiet room.
A banner introduces Dialog-RSN-1 as the company's most advanced frontier dialog model, with an invitation to see the benchmarks.
Publishing benchmarks in this category is worth acknowledging, because almost nobody does.
Voice AI vendors typically compete on demonstrations, which are unfalsifiable — the demo call is chosen by the vendor and goes the way the vendor expects. A published benchmark at least fixes a target that a competitor or a customer can shoot at.
The caveat applies here as everywhere: vendor-published benchmarks are constructed by the party with an interest in the result, and dialog evaluation is genuinely hard to standardise because the same response can be correct or wrong depending on what the caller meant.
The customer outcomes on the same page deserve reading the same way. A 15-point CSAT boost, 7.2 million dollars of incremental revenue, a 60 percent reduction in seasonal hiring saving over a million dollars, and 75 percent of calls resolved without a human are all specific and all attributed to a single named sector. They describe what happened somewhere. They do not describe a rate you should plan around, and a Forrester Total Economic Impact study — which the site links — is commissioned research rather than independent audit.
The platform is presented as one place to build, run, adapt and govern dialog agents at enterprise scale, with two entry points: Poly Agent Builder for non-technical teams and an ADK for developers, both over the same runtime.
Two build surfaces over one runtime is the right architecture, and it is rarer than it should be.
The usual failure is a no-code builder for business users and a separate developer product, which diverge within a year — the visual tool cannot express what the code can, so anything serious migrates and the business team loses access to their own agents.
Sharing a runtime means an agent built by a service manager and one built by an engineer behave identically, which is what makes governance possible at all.
Governance is where the enterprise claim is made concrete: agents governed by default with SOC 2, HIPAA, GDPR and PCI DSS named as standard, brand voice held consistent across channels and languages, and full visibility into every agent decision. That last item is the one worth pressing on in procurement, because decision-level auditability is what turns an incident from an unexplainable failure into a fixable one. Analyst Agents extend the same idea to reading what happened across conversations, which is a different job from OpenMic.ai and similar tools aimed at getting a first agent live quickly.
Voice deployments fail on the calls nobody scoped, not on the ones in the demo.
This sequence surfaces those before they reach customers.
| Category | Enterprise voice and dialog agents for customer engagement |
|---|---|
| Positioning | The Agentic Dialog Platform, stated as open to enterprise builders |
| Core model | Raven, proprietary, stated as trained on 1 billion-plus enterprise conversations |
| Frontier model | Dialog-RSN-1, announced with published benchmarks |
| Build surfaces | Poly Agent Builder for non-technical teams; an ADK for developers |
| Architecture | Described as dialog-native full stack, explicitly not voice bolted onto chat |
| Hard cases | Financial-crime reports, outage, triage and multilingual disputes named as proving ground |
| Compliance | SOC 2, HIPAA, GDPR and PCI DSS stated as standard |
| Governance | Guardrails by default, consistent brand voice, visibility into agent decisions |
| Analytics | Analyst Agents answering questions about interactions in plain language |
| Industries | Financial services, healthcare, hotels, insurance, restaurants, retail, telecom, travel, utilities |
| Company | PolyAI Ltd, per the 2026 footer copyright |
Dialog-native voice agents for enterprise service
Raven, a proprietary conversational model
Dialog-RSN-1 frontier dialog model
Agent Builder for non-technical teams
An agent development kit for engineers
Guardrails and governance applied by default
Multilingual agents with consistent brand voice
Analyst Agents for plain-language interaction analysis
Voice platforms differ by who they are built for and how hard the calls are.
| Tool | Built for | Model | Best for |
|---|---|---|---|
| PolyAI | Enterprise contact centres | Proprietary, dialog-native | Regulated and difficult conversations |
| Vogent | Developers building call flows | Focused on dialog realism | Natural-sounding automated calls |
| OpenMic.ai | Smaller teams | Built on general models | Getting a first agent live quickly |
| Phonely AI | Businesses answering inbound calls | Hosted | Never missing a phone call |
| A staffed contact centre | Everything | People | Judgement, escalation and genuine exceptions |
Other platforms for automated and assisted phone conversations.
Last checked . Read from poly.ai in a browser session on the date above, with the screenshot captured at the same time.
What we could not confirm: what the Dialog-RSN-1 benchmarks measure or how they were constructed; how the billion-conversation training figure is counted; whether the published customer outcomes are typical, since each is attributed to a single organisation; which certifications apply to which regions and deployment models; how containment is defined and whether abandoned calls count; and pricing. We did not build an agent or place a call.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official PolyAI website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
PolyAI earns an AInexfinder Editor Score of 4.4/5 (very good). Best for: Contact centres in regulated industries; Organisations handling calls in several languages; Teams that need auditability as much as automation.
Visit PolyAILog in to write a review.
No reviews yet. Be the first to share your experience with PolyAI.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research PolyAI from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.
PlayHT review on AInexfinder — freemium AI tool for Video & Audio. Features, pricing notes, and alternatives.
TTSReader turns text, PDFs, and EPUB files into speech in the browser, with voice and language selection, speed control, text highlighting, and MP3 export — the free tier runs on browser voices with no usage cap.
VMEG from PixRipple translates and dubs video into 170+ languages using 17,000+ voices, with voice cloning, lip-sync, subtitle generation, batch processing, and API and MCP access for automated localisation.
AI and human transcription and subtitles in 150+ languages

Runway is an AI video platform built around generative world models — Gen-4.5, Aleph 2.0, and Act-Two for performance capture — split across Runway Creative for filmmakers, Runway Dev for builders, and Runway Robotics.
Related Pages