Undermind review on AInexfinder — freemium AI tool for AI Chatbots & Assistants. Features, pricing notes, and alternatives.
AI Chatbots & Assistants Review
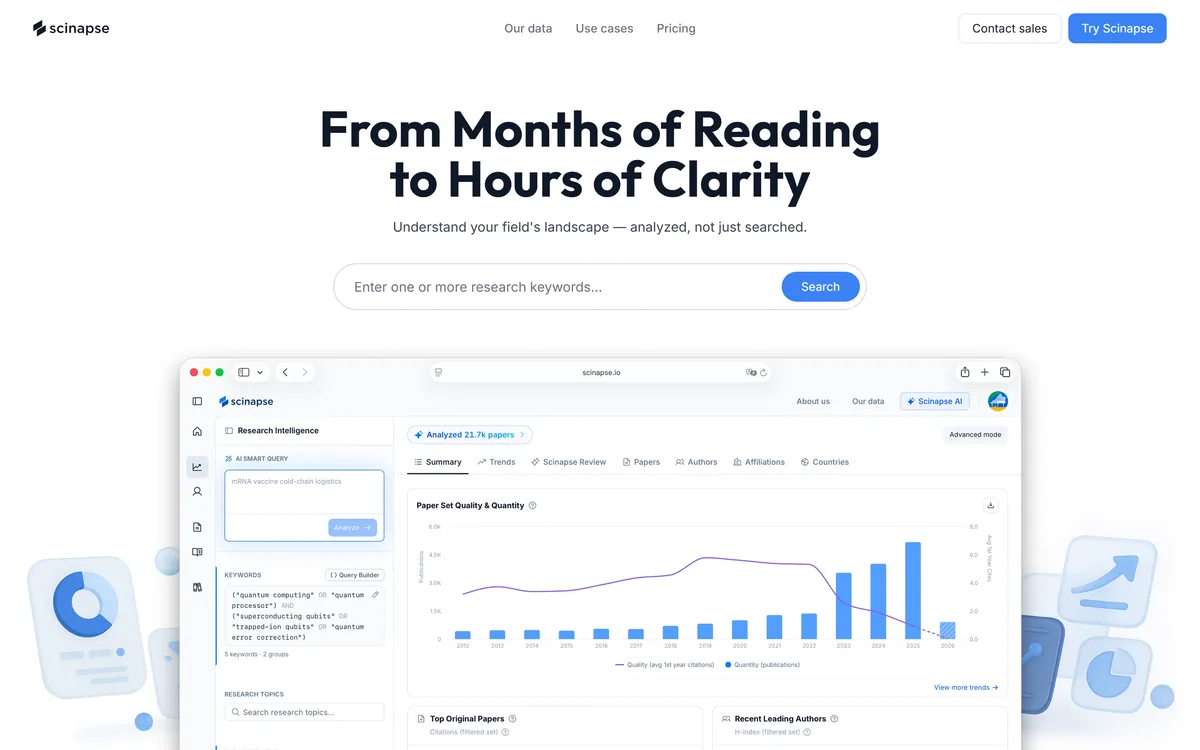
Scinapse analyses research landscapes rather than merely searching them, ranking papers and researchers by citation impact within a filtered set of a field instead of by global totals, generating review papers on request, and mapping how work and authors connect.
Very good
Scinapse is built on a correction that bibliometricians have argued for since the 1980s and that most literature tools still ignore: citation counts are not comparable across fields. A molecular biology paper and a pure mathematics paper of identical importance will differ by an order of magnitude in citations, because the fields cite at different rates. Measuring impact inside a defined set rather than against all of science is the right fix, and the generated review papers are the feature to treat most carefully — a review is an argument, and reading one you did not construct is not the same as knowing a field. AInexfinder Editor Score: 4.1/5.
Best for: Researchers entering an unfamiliar field; Postgraduates orienting before a literature review
The visit link goes to scinapse.io, the official site. Paid placements on AInexfinder are always labelled. How we make money
| Category | Research landscape analysis and expert discovery |
|---|---|
| Core method | Analysis within a filtered set of papers rather than across all literature |
| Impact measure | Citation influence assessed inside a field, not by global totals |
| Grounding | Stated as based on how papers actually cite each other rather than inference |
| Reviews | Generated review papers on topics where none exists |
| Expert ranking | Researchers ranked by influence within a field rather than overall fame |
| Query building | Describe your research in words and a search query is constructed |
| Visualisation | A network map of paper and researcher connections |
| Analytics | Journal influence analysis, researcher profiles and a full article view |
| Classification | Papers structured by topic, year, type, journal and citation impact |
| Coverage | Stated as field-specific analysis across every discipline |
| Company | Pluto Labs, per the 2026 footer copyright, with institutional access offered |
The positioning is a single distinction repeated in several forms: understand your field's landscape, analysed rather than just searched, with impact measured where it counts.
The FAQ states the difference plainly — most tools rank papers by total citations across all fields, while Scinapse analyses within your field's trends, influential papers and experts.
That is not a marketing refinement. It is a correction to a well-documented flaw in how research is commonly evaluated.
Citation practices differ enormously between disciplines. Biomedical papers carry long reference lists and cite recent work heavily; mathematics papers cite sparsely and reach back decades. A paper with 300 citations is unremarkable in one field and field-defining in another.
Ranking everything on a single scale therefore does not measure importance — it measures which discipline you are in, plus some importance. Anyone who has searched a general index and found the top results dominated by adjacent biomedical work has experienced the problem directly.
A paper with 300 citations is unremarkable in one field and field-defining in another. A single ranking scale measures your discipline first and your importance second.
If impact is measured within a set, then everything depends on how the set is drawn — which is why the FAQ gives the filtered set its own question.
This deserves attention rather than acceptance, because the boundary is a methodological choice and the results follow from it.
Draw the set narrowly and a paper looks foundational because it dominates a small pond. Draw it broadly and genuinely important specialist work disappears into the noise of a larger field. Neither is wrong; they answer different questions, and only the person asking knows which one they meant.
The practical implication is that a field-weighted score should be read as a comparison you specified rather than as a property of the paper.
Two other cautions apply to any citation measure. Citation lag means recent work is systematically undervalued, which is a problem precisely for anyone working in an emerging area. And citations record attention rather than merit — papers are cited for being wrong, for being convenient to cite, and for being written by someone whose name lends weight. Bibliometrics measures conversation, not truth. Evidence-focused tools like Elicit work on what papers found rather than on who cited them.
The site states it directly: a paper's total citations are noisy, so impact is measured where it counts.
Noise is the right word, and it is worth unpacking the sources because they affect how you read any number.
Field is the largest, as above. Age is the second — a paper from 2010 has had fifteen years to accumulate citations and one from last year has had months, so any ranking by total citations is substantially a ranking by publication date.
Document type is the third and least appreciated. Review papers and methods papers attract citations far out of proportion to their originality, because everyone working in an area cites the review and everyone using a technique cites the method. A widely used statistical method can out-cite the discoveries it enabled by an order of magnitude.
The fourth is self-reinforcement: highly cited papers get read more and therefore cited more, independent of merit. Analysing within a filtered set addresses the first source directly and helps with the others by making comparison local. It does not eliminate any of them, and no tool can, because they are properties of how science communicates rather than defects in the data.
The boldest feature is stated without hedging: the perfect review for your topic rarely exists, so we build it for you.
The observation behind that is entirely correct and familiar to every researcher. Review articles exist for topics somebody chose to review, at the moment they chose to write it — so a review of your exact intersection either does not exist or is six years old, which in a fast-moving area is the same thing.
What the feature is genuinely good for is orientation. Entering an unfamiliar field means learning what the questions are, who the camps are and which papers everyone assumes you have read, and a synthesis gets you there in an afternoon rather than a fortnight.
What it cannot be is a substitute for the reading. A review paper is an argument: it selects, weights, dismisses and connects, and those judgements are the substance. Reading a generated synthesis leaves you knowing what the literature says without having formed a view about which parts are convincing — a difference that becomes obvious the moment a supervisor or reviewer asks why you believe something.
The grounding claim matters here, and the FAQ addresses accuracy directly. Insights tied to how papers actually cite each other is a meaningfully stronger position than generating from a model's memory, which is where fabricated references come from. Verify anything you will cite by opening the paper — always, from any tool. R Discovery takes the reading-list approach to the same problem.
Expert discovery is framed the same way as paper ranking: find collaborators by real influence, not reputation, with researchers ranked by impact inside your field rather than overall fame.
This is the most practically valuable feature and the one hardest to replicate by hand.
The person you actually want for a collaboration, a review, a citation or a conference invitation is rarely the most famous name in the adjacent field. It is the person doing the most influential work on your specific question, who may be mid-career, at a less visible institution, or publishing in a specialist venue nobody outside the area reads.
Finding them manually means reading enough of the literature to notice the same name recurring, which takes months and is exactly the knowledge a newcomer does not have.
Supporting tools follow the same logic: a query builder that turns a description of your research into a search, a network map showing how papers and researchers connect, journal analytics, researcher profiles and a single article view. The network map is the one worth spending time in — citation structure reveals things keyword search cannot, including where a field split into camps and which paper bridges them. Institutional access is offered with setup handled by the vendor, which is how research tools are usually bought. For a question outside your own discipline entirely, a general cited-answer tool such as Perplexity AI is usually the faster first step.
The claimed transformation is months of reading into hours of clarity, and the honest version is narrower: hours to orient, then read properly.
This sequence uses it that way.
Field-relative citation impact analysis
Generated review papers on demand
Expert ranking by influence within a field
Natural language query builder
Network map of papers and researchers
Journal influence analytics
Researcher profiles and full article views
Classification by topic, year, type, journal and impact
Research tools differ by what they do with the literature.
| Tool | Method | Answers | Best for |
|---|---|---|---|
| Scinapse | Citation analysis within a field | Who and what matters here | Mapping a field and finding experts |
| Elicit | Extraction from paper contents | What studies found | Systematic evidence synthesis |
| R Discovery | Personalised reading feeds | What to read next | Keeping up with a field |
| Perplexity AI | General search with citations | Quick orientation | Questions outside your discipline |
| A supervisor | Accumulated judgement | Which of it to believe | Everything a citation graph cannot see |
Other tools for finding, reading and synthesising research.
Last checked . Read from scinapse.io in a browser session on the date above, with the screenshot captured at the same time.
What we could not confirm: which databases the citation data comes from or how complete the coverage is; how a filtered set is constructed and what defaults apply; how field-normalised impact is calculated; what accuracy checking is applied to generated reviews beyond the stated citation grounding; and pricing. We did not run a search or generate a review.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Scinapse website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Scinapse earns an AInexfinder Editor Score of 4.1/5 (very good). Best for: Researchers entering an unfamiliar field; Postgraduates orienting before a literature review; Anyone seeking collaborators or reviewers by genuine influence.
Visit ScinapseLog in to write a review.
No reviews yet. Be the first to share your experience with Scinapse.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Scinapse from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Undermind review on AInexfinder — freemium AI tool for AI Chatbots & Assistants. Features, pricing notes, and alternatives.
Visual literature discovery and citation mapping for research Category: AI Chatbots & Assistants.
Clarivate's Web of Science Research Assistant is a generative and agentic AI layer over the Web of Science Core Collection, turning a research question into guided literature-review, author and trend workflows with visible grounding in trusted data.
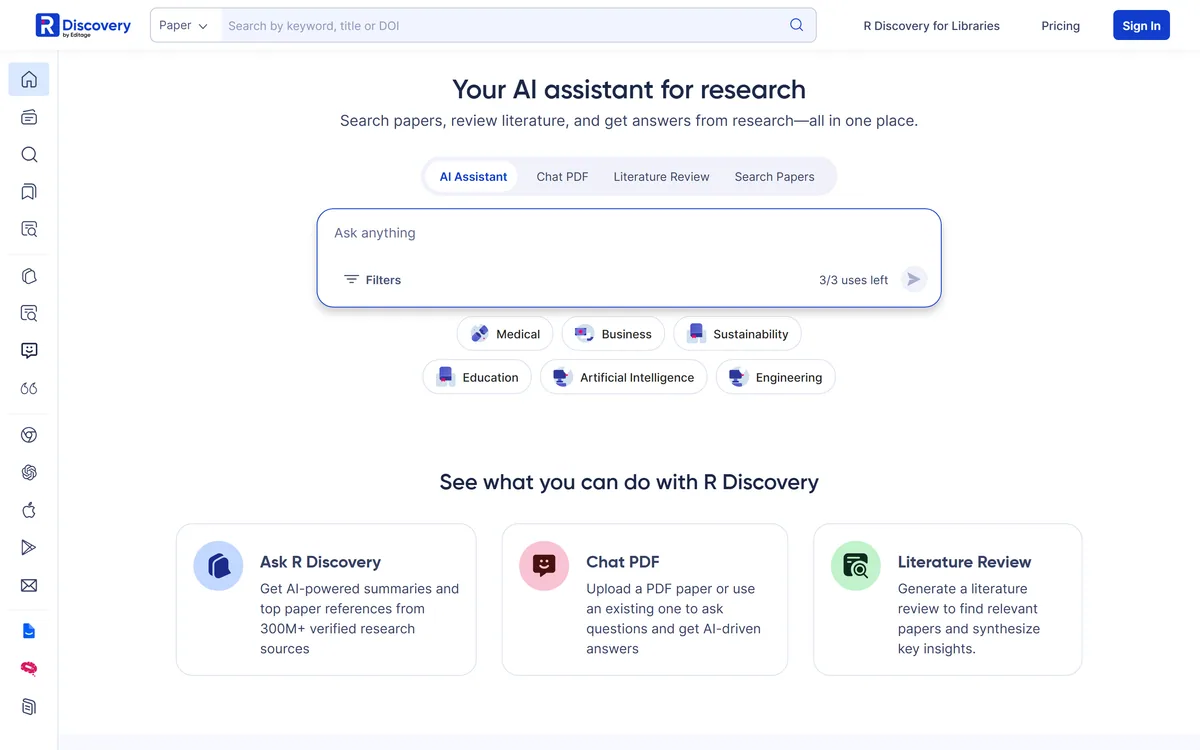
R Discovery is a research reading and literature search app from Cactus Communications, covering 150M+ journal articles, 78M+ open access papers and 10M+ conference documents. It offers AI summaries with citations, chat with a PDF, generated literature reviews, audio papers and translation into 30+ languages.
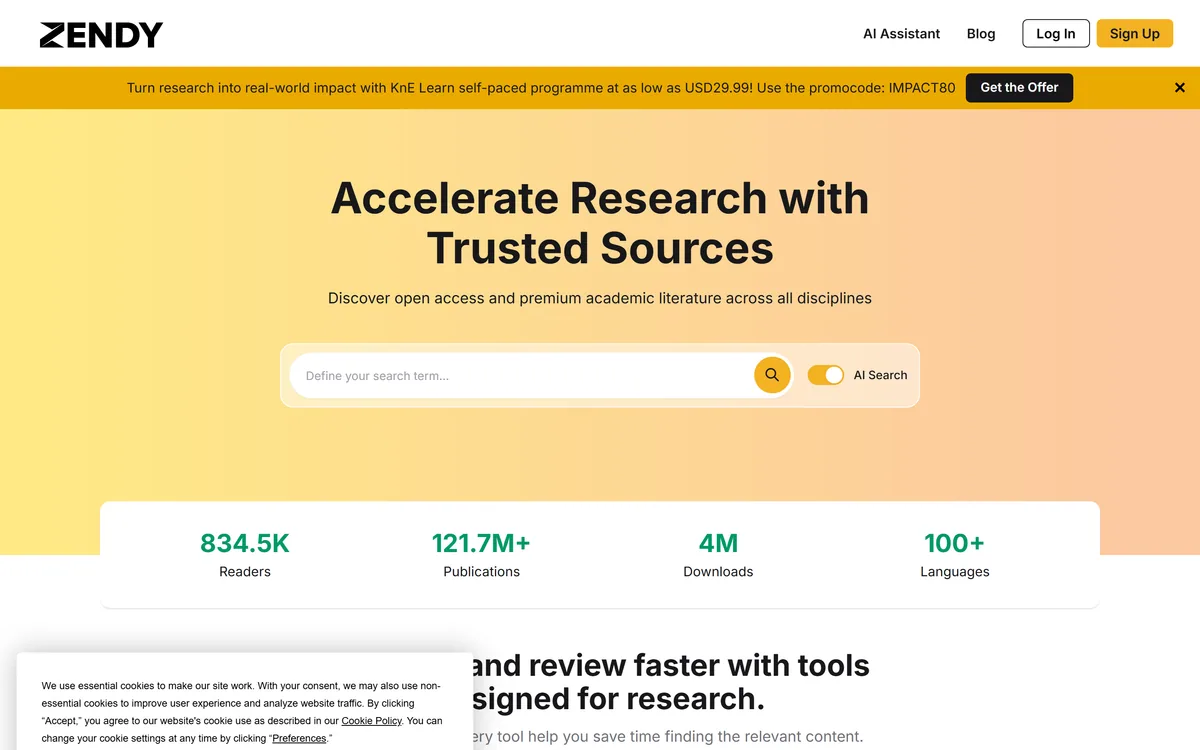
Zendy is an AI-powered research library combining open-access and premium academic literature with ZAIA, an assistant that summarises papers, highlights key phrases and gives reference-backed answers, aimed at independent researchers and institutions.

Claude is Anthropic's AI assistant, available on web, desktop, mobile, and in Chrome, with Projects for persistent context, Artifacts for generated documents and apps, Skills, Connectors, and Claude Code for developers.
Related Pages