AI content detection and plagiarism checking in one platform Category: Education & Research.
Education & Research Review
Elicit is an AI research assistant for scientific literature. It searches across more than 125 million papers, screens and extracts data at systematic-review scale, and produces research reports where every claim carries a sentence-level citation back to its source.
Excellent
Elicit has an AInexfinder Editor Score of 4.6/5.
Best for: Researchers conducting systematic and scoping reviews; Pharmaceutical and medical device evidence teams
The visit link goes to elicit.com, the official site. Paid placements on AInexfinder are always labelled. How we make money
Five terms that make the difference between understanding this tool and misreading its claims.
| Category | AI research assistant for scientific literature and systematic review |
|---|---|
| Corpus | More than 125 million academic papers |
| Named features | Research Reports, Systematic Literature Review, Library, Alerts, Research Agent |
| Analysis scale | Vendor states up to 1,000 relevant papers analysed and up to 20,000 data points processed |
| Citation approach | Sentence-level citations from source material on every AI-generated claim |
| Benchmark basis | 994 Cochrane reviews |
| Stated benchmark results | 95% search recall, 97% abstract screening, 99% full-text screening, 96% extraction |
| Stated extraction accuracy | 99.4% |
| Stated user base | More than 5 million researchers, per the vendor |
| Sectors served | Pharmaceuticals, academia, medical devices and technology, policy and government, consumer goods, industrials, software and technology |
| Charging model | Tiered access with a free entry point and paid plans, plus institutional arrangements; no prices published here |
Elicit is not built to answer questions. It is built around a specific and enormously expensive research method, and understanding that method explains the whole product.
A systematic review is the process of answering a research question by finding and assessing all the relevant evidence, according to a protocol declared in advance. It underpins clinical guidelines, drug approvals and policy decisions, and it is the highest form of evidence synthesis there is.
It is also brutal to conduct. A team designs a search, runs it across databases, and retrieves several thousand records. Two reviewers independently screen every title and abstract. The survivors are read in full, again independently. Data is extracted from each included study into a structured table. Disagreements are resolved by a third reviewer.
That process routinely takes twelve to twenty-four months and consumes hundreds of hours of skilled time — most of it spent reading abstracts of papers that turn out to be irrelevant.
Faster tools like Consensus answer a question; this one builds a defensible search. It is exactly the shape of work that should be automated: high-volume, rule-governed, exhausting, and where the human contribution to each individual decision is genuinely small even though the aggregate matters enormously.
That Elicit organises itself around this rather than around a chat interface is the strongest signal about who built it and for whom.
Screening four thousand abstracts by hand is not research. It is the tax you pay before the research, and it is the right thing to automate.
Most AI tools publish accuracy figures that cannot be checked. This one is different in a way worth explaining.
Cochrane reviews are the gold standard of evidence synthesis in medicine. They are conducted to a published protocol, by trained reviewers, with documented inclusion and exclusion decisions for every record considered.
That makes them a genuine benchmark rather than a marketing exercise. If you can obtain 994 completed Cochrane reviews, you have 994 cases where humans already decided, transparently, which papers were relevant and what data they contained. You can run a system against the same starting point and compare.
The stated results — 95% search recall, 97% abstract screening, 99% full-text screening, 96% extraction — describe agreement with expert human reviewers on tasks where the correct answer was independently established.
The figure that matters most is search recall at 95%, because in systematic review a miss is the defining failure. Missing 5% of relevant literature is not a small error — a review that omits a relevant trial can reach the wrong conclusion, and that conclusion may inform treatment.
So the honest reading is that 95% is genuinely impressive for automation and is not sufficient on its own for a review that will be published or submitted. Which is precisely why it is used to accelerate the process rather than replace the second reviewer.
If you take one thing from this listing, take this: the citation architecture is more important than the corpus size.
General assistants like Perplexity cite the open web; academic work needs more. Language models fabricate references. This is not an occasional bug but a well-documented characteristic — plausible author names, plausible journals, plausible years, describing papers that do not exist. It is the single reason general chat models are dangerous for literature work, and it has already produced retractions and court sanctions in other fields.
A researcher who cannot instantly verify a claim has to check every reference by hand, which eliminates the time saving that motivated using the tool in the first place.
Grounding every generated sentence in a specific passage of a specific retrieved paper changes that entirely. The claim is traceable, and the check takes a click rather than a search.
It also changes the failure mode in a useful direction. A grounded system that cannot find support tends to say less rather than inventing more — which is the correct behaviour for research and the opposite of what a general assistant does.
The corollary is that you must still read the cited papers before relying on them. A citation proves the source exists and was retrieved; it does not prove the summary characterised its findings correctly, and characterisation is where the remaining errors live.
This site does not publish plan prices. Elicit's structure is tiered, and the shape is worth knowing because it differs by who you are.
There is a free entry point with paid tiers above it, and separate institutional arrangements for universities, pharmaceutical companies and government bodies.
The meter in research tools of this kind is usually work volume rather than seats — how many papers a run can analyse, how many extractions or reports you can perform, and whether the heavier systematic review workflows are available at your level. Screening 1,000 papers is a materially different unit of consumption from asking a question.
For individual academics the practical question is whether your institution already has an arrangement, since library-negotiated access is common for research tools and much cheaper than an individual subscription.
For commercial research teams the comparison worth running is against the fully loaded cost of the analyst hours currently spent screening. A systematic review consuming several hundred hours of skilled time makes the arithmetic unusually clear.
One thing to confirm regardless of tier: what happens to your uploaded documents and your queries, particularly if you are working on unpublished research or commercially sensitive questions.
Being specific here matters more than usual, because the accuracy figures invite over-trust.
It cannot assess study quality the way a methodologist does. Risk of bias assessment — was randomisation adequate, was blinding maintained, was the outcome measure appropriate — requires domain judgement about how a study was actually conducted. Extraction finds what a paper reports; it does not evaluate whether the paper should be believed.
It sees published literature only. Publication bias is one of the most serious distortions in evidence synthesis: studies with negative results are systematically less likely to be published. A perfect search of published papers still inherits that bias, and grey literature and unpublished trial data sit largely outside any corpus.
Cross-checking against Semantic Scholar is a cheap sanity test. Coverage is not universal. 125 million papers is enormous and it is not everything — non-English literature, older material, some regional journals and paywalled content vary in how well they are represented.
The synthesis is still yours. Deciding what a body of evidence means, where studies conflict and why, and what should follow from it, is the actual intellectual work. Elicit gets you to the point where that work can begin, much faster.
For anything that will be published, submitted to a regulator, or used to inform clinical practice, treat this as a powerful assistant to a properly conducted review and not as the review itself.
Search across more than 125 million academic papers
Automated abstract and full-text screening
Structured data extraction into tables across many studies
Research Reports built on systematic review methodology
Sentence-level citations on every generated claim
Library for organising and reusing sources
Alerts for new research on tracked questions
Research Agent environment for high-stakes work
Analysis of up to 1,000 papers in a single piece of work
These differ sharply in rigour and in what they are actually for, despite looking similar.
| Tool | Built for | Citation grounding | Depth |
|---|---|---|---|
| Elicit | Systematic review and data extraction | Sentence-level, on every claim | Review-scale, up to 1,000 papers |
| Consensus | Quick evidence answers to a question | Cited, study-level | Fast rather than exhaustive |
| Scite | How papers cite each other, supporting or contrasting | Citation statements | Citation context specifically |
| Semantic Scholar | Free literature discovery | Standard indexing | Search, not synthesis |
| Perplexity | General web research | Cited web sources | Broad, not academic-grade |
Most serious research uses several of these — one for discovery, one for synthesis, one for checking how a paper has been received.
Last checked . Read from elicit.com during this check, with the screenshot above captured at the same time.
All accuracy and scale figures are the vendor's own, benchmarked against Cochrane reviews but not independently audited. Search recall of 95% means roughly one relevant paper in twenty is missed, which is not acceptable on its own for a review intended for publication or regulatory submission — this accelerates a properly conducted review rather than replacing the second reviewer. It also cannot assess study quality, and inherits publication bias from the literature it searches.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Elicit website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Elicit earns an AInexfinder Editor Score of 4.6/5 (excellent). Best for: Researchers conducting systematic and scoping reviews; Pharmaceutical and medical device evidence teams; Policy analysts synthesising research for government.
Visit ElicitLog in to write a review.
No reviews yet. Be the first to share your experience with Elicit.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Elicit from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
AI content detection and plagiarism checking in one platform Category: Education & Research.
Gemini Notebook is Google's research and thinking tool, grounded in sources you upload rather than the open web. Renamed from NotebookLM on 16 July 2026, it now also runs code in a secure cloud environment and syncs notebooks with the Gemini app.

SciSpace review on AInexfinder — freemium AI tool for Education & Research. Features, pricing notes, and alternatives.
Consensus is an AI-powered academic search engine that searches and analyses hundreds of millions of peer-reviewed research papers, with a Deep Search that automates literature review, a Medical mode for clinical sources, and natural-language filters, used across university libraries.
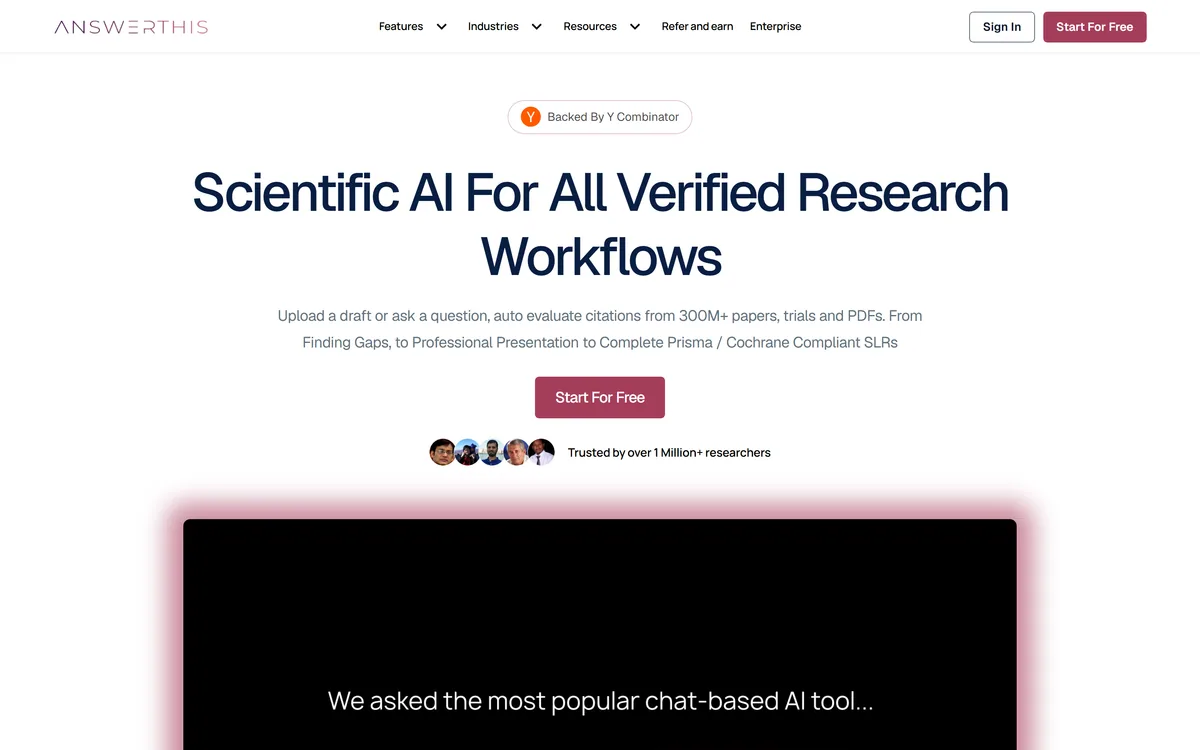
AnswerThis is an AI research assistant for literature reviews that searches a large database of papers and trials, checks citations and claims against their sources, supports PRISMA- and Cochrane-style systematic reviews, and helps draft, revise and collaborate on research writing.
Answer AI review on AInexfinder — freemium AI tool for Education & Research. Features, pricing notes, and alternatives.
Related Pages