
Cursor is an AI-first code editor and agent platform from Anysphere — now a SpaceX subsidiary — that plans, writes, tests, and reviews code across your repository from the desktop editor, a CLI, the web, and Slack.
Coding & Development Review
Amp is an agentic coding tool from Sourcegraph that runs in the terminal and in editor extensions, using Sourcegraph's code intelligence to give frontier models deep repository context. It plans multi-step work, edits across files, runs tests and iterates, on pay-as-you-go credits with no markup on provider pricing.
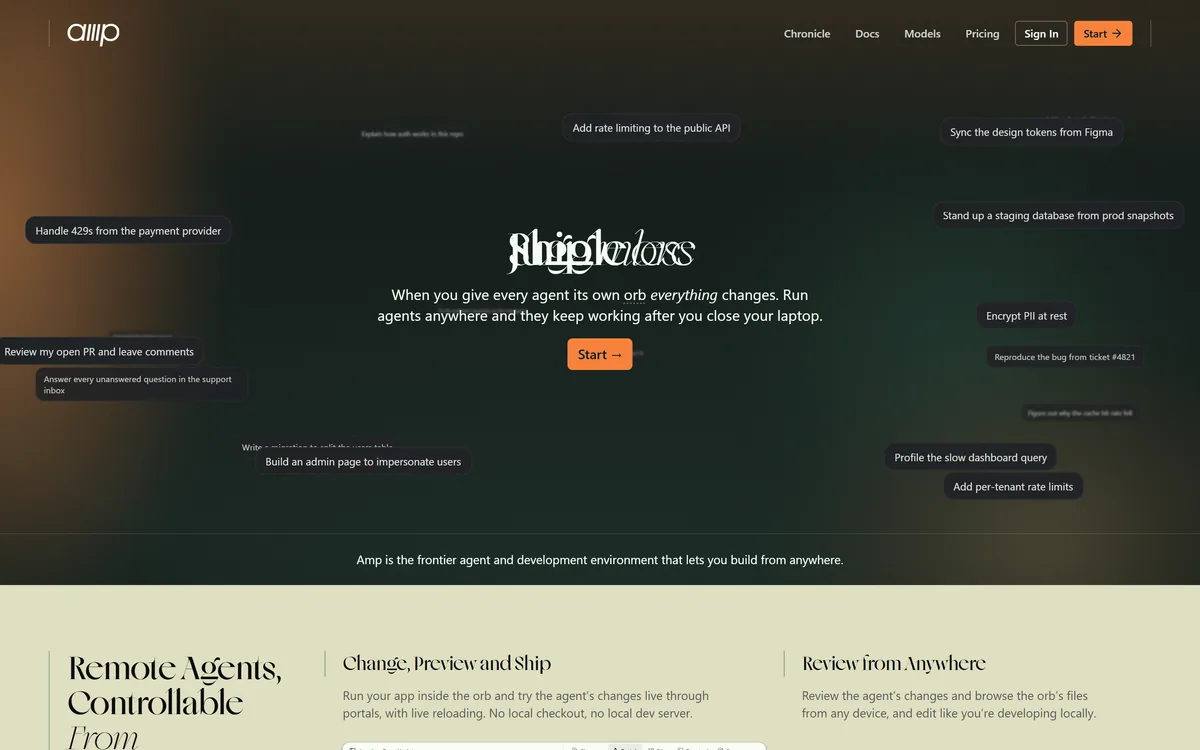
Very good
Amp scores well for two reasons that are unusual together. Sourcegraph has spent a decade building code intelligence over large repositories, and pointing that at a frontier model gives the agent context most rivals approximate — which is why it holds up on multi-file refactors rather than single-file edits. And charging provider cost with no markup is a genuinely different commercial posture from a seat subscription: you pay for what the model actually did. It loses ground because pay-as-you-go makes budgeting harder than a flat fee, because the free tier is ad-supported which some teams will not accept, and because the privacy difference between tiers is a real decision rather than a detail. AInexfinder Editor Score: 4.3/5.
Best for: Developers working in large or complex codebases; Multi-file refactors where finding every call site is the hard part
The visit link goes to ampcode.com, the official site. Paid placements on AInexfinder are always labelled. How we make money
Sourcegraph spent a decade solving one problem: understanding very large codebases well enough to answer questions about them. Code search, cross-repository references, the tooling that lets an engineer at a big company find every caller of a function across millions of lines.
That turns out to be the exact capability agentic coding needs and mostly lacks. A frontier model can write excellent code; what it cannot do is know what else in your repository depends on the thing it is about to change.
Amp is what happens when the second problem is solved by a company that already solved the first. That lineage is the main reason to take it seriously, and the pricing posture — provider cost, no markup — is the second.
The industry's default answer — including in Cursor — has been to make context windows larger and paste in more files. Amp's approach is different, and better suited to how code actually works.
Code is a graph, not a document. What matters about a function is not the text near it but what calls it, what it calls, what types flow through it and what tests cover it — and those live in files scattered across the tree. Pasting in adjacent text gives a model proximity rather than relevance.
Sourcegraph's code intelligence resolves those relationships properly, which means the model can be given the specific definitions and call sites that bear on a change rather than a large sample of nearby code and a hope.
The practical consequence shows up on exactly the tasks that matter most and demo least well: multi-file refactors, changing a shared interface, renaming something used in forty places. Those are the changes engineers avoid because they are tedious and risky, and they are where an agent with real reference data earns its cost.
The complementary limitation is worth stating. Code intelligence is strongest where a language has good static analysis. Dynamically typed code with heavy runtime magic resolves less cleanly, for the same reasons your IDE struggles with it — the references genuinely are harder to determine.
A model given the file next door has proximity. A model given every actual caller has relevance. Only the second one can refactor safely.
Amp's Threads feature saves and shares interactions, and this is more consequential than a convenience feature.
The problem it addresses is that agentic sessions are currently invisible work. A colleague sees the resulting pull request but not the eleven steps, the two wrong turns and the reasoning that produced it. When something is subtly wrong, nobody can reconstruct how it happened.
A shareable thread turns that into a reviewable artefact. Another engineer can read the sequence, see where the agent misunderstood the requirement, and correct the prompt rather than the code.
It also has an underrated teaching use. The fastest way for a team to get good at agentic coding is to read sessions that worked, and threads make that shareable rather than each person rediscovering the technique privately.
Amp charges pay-as-you-go credits with zero markup on provider API pricing for individuals, alongside a free tier that requires no card.
This is a materially different posture from the seat subscriptions that dominate the category, and it is worth understanding what it implies about incentives.
A seat subscription is a bet by the vendor that you will use less than you pay for. That creates a quiet incentive to make heavy usage inconvenient, and it means light users subsidise heavy ones. Charging provider cost inverts it: the vendor makes nothing on your token consumption, so there is no reason to ration it, and no reason to route you to a cheaper model than the task deserves.
For a user the consequences are concrete. A month you barely code costs almost nothing. A month spent on a large migration costs what that migration's model usage actually cost, which may be more than a subscription would have — and you can see exactly why.
The trade is budgeting. Finance departments prefer a predictable line item, and a variable one is harder to approve even when it is cheaper on average. If your organisation needs a fixed number, this model will be an argument rather than a feature.
Amp's free tier includes its Tab autocomplete, access to the core agent with no hard token caps, and thread sharing — and it is ad-supported.
Take the generosity seriously first: a free tier with no hard token cap on the core agent is unusual, and it means the tool can be evaluated properly rather than through a crippled trial.
The ad-supported model deserves plain treatment though, because it is uncommon in developer tooling and people have reasonable questions about it. The relevant question is not whether ads are annoying; it is what they imply about data.
The paid tier is described as offering zero data sharing, with code, prompts and agent threads not used to train models. Read the inverse carefully: if that is the differentiator, then the free tier does not carry the same guarantee.
For personal projects and open-source work that may be entirely acceptable. For employer code it usually is not, and the decision should be made deliberately rather than by defaulting to the free tier because it was there. If your code is proprietary, the paid tier is the only sensible starting point, and the pricing model makes that a small step rather than a big one.
The free tier makes evaluation easy, but evaluate it on the task type that distinguishes it rather than on the one that is easiest to test.
The bar is step three. Single-file edits tell you nothing about Amp specifically, because every agent in the category handles those.
Amp competes in a crowded category, and the honest summary is that the differences are narrowing on code generation and widening on everything around it.
Against an editor-first tool, Amp gives up ambient context — it does not know what you have selected or which test just failed — and gains repository-scale reference data plus the ability to run in a terminal, in CI or over SSH.
Against an open-source terminal agent such as Aider, it gives up model flexibility and full local operation, and gains Sourcegraph's code intelligence, which is a genuinely hard thing to replicate.
Against an enterprise orchestration platform such as Zencoder, it gives up compliance certifications, on-premise deployment and administrative controls, and gains simplicity and a pricing model that does not require a procurement process.
The buyer this suits best is a developer or a small team working in a large or complex codebase, who wants an agent with real reference data and does not need a compliance conversation to adopt one.
| Product type | Agentic coding tool |
|---|---|
| Built by | Sourcegraph |
| Runs in | Terminal, plus editor extensions including VS Code and compatible forks |
| Context method | Sourcegraph code intelligence over your repository |
| Agent behaviour | Multi-step planning, multi-file editing, running tests, interpreting output and iterating |
| Models | Claude, GPT-4o, Gemini and other frontier models, user-selectable |
| Collaboration | Threads — saved and shareable agent sessions |
| Free tier | Tab autocomplete, core agent with no hard token caps, thread sharing; ad-supported, no card required |
| Paid tier | Smart Mode, with zero data sharing — code, prompts and threads not used to train models |
| Pricing model | Pay-as-you-go credits at provider cost, stated as zero markup for individuals |
Sourcegraph code intelligence giving frontier models repository-wide reference data
Multi-step task planning before implementation
Multi-file editing across an entire codebase
Runs tests, reads the output and iterates without being prompted each time
Threads for saving and sharing complete agent sessions
User-selectable frontier models including Claude, GPT-4o and Gemini
Runs in the terminal and in VS Code and compatible editor forks
Tab autocomplete included even on the free tier
These tools differ most on where their context comes from and how they charge. Both questions matter more than raw code quality, which has largely converged.
| Tool | Context source | Model choice | Billing |
|---|---|---|---|
| Amp | Sourcegraph code intelligence across the repository | Frontier models, user-selectable | Pay-as-you-go at provider cost; free tier is ad-supported |
| Aider | Its own repository map | Any model, including local | Free tool, you pay your provider |
| Cursor | Editor context plus indexing | Bundled | Per-seat subscription |
| Zencoder | Multi-repo indexing with dependency mapping | Routed across three models by task | Enterprise subscription |
| GitHub Copilot | Editor and repository context | Bundled | Per-seat subscription |
Compare on context source and billing model — code generation quality has largely converged, and those two have not.
Last checked . The site returned a header error to our automated fetch, so product facts here come from the captured screenshot above and from published third-party coverage rather than from a full page read.
What we could not confirm: our automated fetch of ampcode.com failed with a header parsing error, so we could not read the site's own footer, privacy policy or terms, and the details above rest on the captured screenshot plus third-party coverage rather than on the vendor's full pages. No compliance certifications, data residency terms or enterprise deployment options were established. Pricing specifics and the exact scope of the free tier's data handling should be confirmed directly with the vendor before putting proprietary code through it.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Amp website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Amp earns an AInexfinder Editor Score of 4.3/5 (very good). Best for: Developers working in large or complex codebases; Multi-file refactors where finding every call site is the hard part; Teams that want agent sessions colleagues can read and learn from.
Visit AmpLog in to write a review.
No reviews yet. Be the first to share your experience with Amp.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Amp from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Cursor is an AI-first code editor and agent platform from Anysphere — now a SpaceX subsidiary — that plans, writes, tests, and reviews code across your repository from the desktop editor, a CLI, the web, and Slack.

GitHub Copilot is an AI coding assistant that spans completion, chat, agent mode, automated code review, and a cloud agent that opens pull requests, working across VS Code, Visual Studio, JetBrains, Xcode, Neovim, Eclipse, the CLI, and github.com.
OpenCode is an open source AI coding agent built for the terminal, with desktop and IDE clients alongside. It connects to 75+ model providers, configures language servers automatically, runs parallel agent sessions, keeps conversations locally in SQLite, and is built by the team behind SST.
Aider is an open-source AI pair programming tool that runs in your terminal, builds a map of your whole repository for context, works with almost any LLM including local models, and commits each change to git with a written message so every edit can be diffed and undone.
Traycer review on AInexfinder — freemium AI tool for Coding & Development. Features, pricing notes, and alternatives.
Generate native iOS, Android and web apps from prompts Category: Coding & Development.
Related Pages