AI agents are only as good as the information they can reach, and a consumer search engine was never designed to feed one. Exa is search rebuilt for that job: an API an agent calls, not a page a person reads.
It gives agents real-time web access through its own index, embedding and retrieval models and a vector database, with selectable latency, search verticals and token-efficient highlights. It sits between consumer AI search like Perplexity AI and the developer infrastructure layer, serving the retrieval that agents and apps are built on.
This review covers how Exa feeds an agent the right data, where it earns its place in a build, how its API is priced, and when it is the wrong call.
Exa, The Short Picture
- Exa is a search API for AI agents: real-time web data designed to be consumed by software, not read by a person.
- It runs its own stack: a large index, embedding and retrieval models, and a vector database, not a resold engine.
- It is built for agent context: selectable latency, search verticals and token-efficient highlights.
- Its scale claims are the vendor's: 'world's largest independent index' and benchmark leads are stated, worth verifying.
A Search Engine Built For AI Agents, Not People
Exa's premise is that searching for a machine is a different problem from searching for a human. A person wants ten blue links; an agent wants the most relevant content, in the fewest tokens, fast, in a structure it can act on. Exa optimises for the second.
The clearest expression of that is 'highlights': rather than returning whole pages, a specialised model extracts the most relevant excerpts, which the vendor says cuts the tokens an agent consumes dramatically. For anyone paying per token, that is a direct cost lever, not just a nicety.
It also builds its own index and retrieval models rather than reselling another engine, which is a meaningful difference: the behaviour is Exa's to tune for agent use, not a wrapper around someone else's search.
A person wants ten blue links; an agent wants the most relevant content, in the fewest tokens, fast, in a structure it can act on. Exa optimises for the second.
How Does Exa Feed An Agent The Right Data?
The API is shaped around the choices an agent build actually needs to make.
Latency Modes, Verticals And Highlights
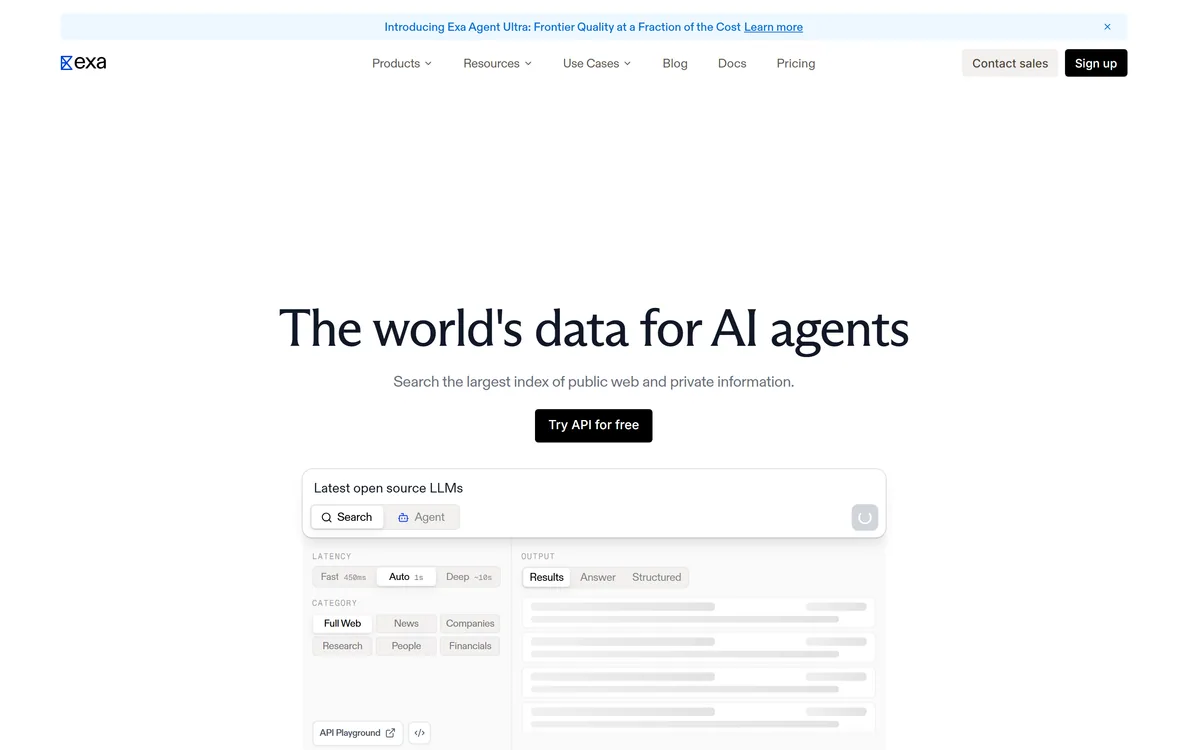
You can trade latency for depth, from near-instant results to a deep mode that takes longer, choose output as results, a direct answer or structured data, and search verticals like news, companies, research, people and code rather than the whole web indiscriminately.
That control is what makes it usable inside a real agent loop. A consumer AI search like Felo answers a person's question; Exa gives a developer the knobs, latency, vertical, format, to wire search into an agent's reasoning step.
Its Own Index And Retrieval Models
Underneath sits Exa's own large index, a vector database built for high query volume, and embedding and retrieval models it trains itself, plus structured enrichments across millions of companies with grounded citations.
Owning the stack is why it can promise things a reseller cannot, like zero data retention and tuned agent behaviour. It pairs naturally with model infrastructure such as Replicate: one runs the models, the other feeds them fresh, grounded context.
Where Exa Earns Its Place In A Build
Exa earns its place anywhere an agent or app needs current, grounded information: research assistants, coding agents that must read the live web, lead-enrichment pipelines, and anything that would otherwise hallucinate without retrieval.
Its benchmark positioning, which the vendor states shows it leading rivals on several retrieval benchmarks, and named customers using it at scale, are real signals, though the benchmark figures are Exa's own and worth verifying against your use case.
One honest note: Exa indexes public web content including information about people, and offers people-search as a vertical. That is a legitimate capability, but it carries privacy responsibilities for whoever builds on it, which sit with the developer, not the API.
How Exa Prices Its API
Exa is usage-based: you can try the API free, with pricing scaling by use, and enterprise agreements adding data-security terms like a DPA or BAA and custom arrangements. We do not publish rates, which change; check the site.
The token-efficient highlights matter to the economics here: because they cut how much content your model has to process, Exa can reduce downstream model cost, not just its own charge, which is a subtler value than a headline rate suggests.
The sensible way to size it is to run your real agent's query pattern against the free tier and measure both Exa's cost and the token savings on your model side.
A Fast Way To Prove Out Exa
Because the value is retrieval quality inside an agent, test it on your real queries, not demo ones.
- Call the API with genuine queries from your agent's actual workload.
- Try the latency modes and pick the one that fits your loop's speed budget.
- Use the right vertical, news, research, code, rather than whole-web search, and compare relevance.
- Turn on highlights and measure the token reduction on your model side.
- If you build with agents, wire it in through the MCP server and test end to end.
- Pass/fail: Exa is worth it if retrieval quality and token savings beat your current approach.
- If your build touches people-search, confirm your privacy obligations before shipping.
Exa Search API Facts
| What it is | A search API for AI agents and apps |
|---|
| Built on | Its own index, embeddings and retrieval models |
|---|
| Latency | Selectable modes from instant to deep |
|---|
| Verticals | Web, news, companies, research, people, code |
|---|
| Highlights | Token-efficient excerpts for agent context |
|---|
| Structured | Enrichments with grounded citations |
|---|
| Access | REST API, MCP server, playground |
|---|
| Security | SOC 2 Type II, GDPR, zero data retention stated |
|---|
Exa Search-API Terms
- Highlights
- Exa's token-efficient excerpts: the most relevant parts of a page, extracted so an agent processes fewer tokens.
- Latency mode
- A setting trading speed for depth, from near-instant results to a slower deep search.
- Vertical
- A focused search domain such as news, companies, research, people or code, rather than the whole web.
- Vector database
- A store of embeddings that enables fast semantic retrieval at high query volume, which Exa runs itself.