Genspark review on AInexfinder — freemium AI tool for AI Chatbots & Assistants. Features, pricing notes, and alternatives.
AI Chatbots & Assistants Review
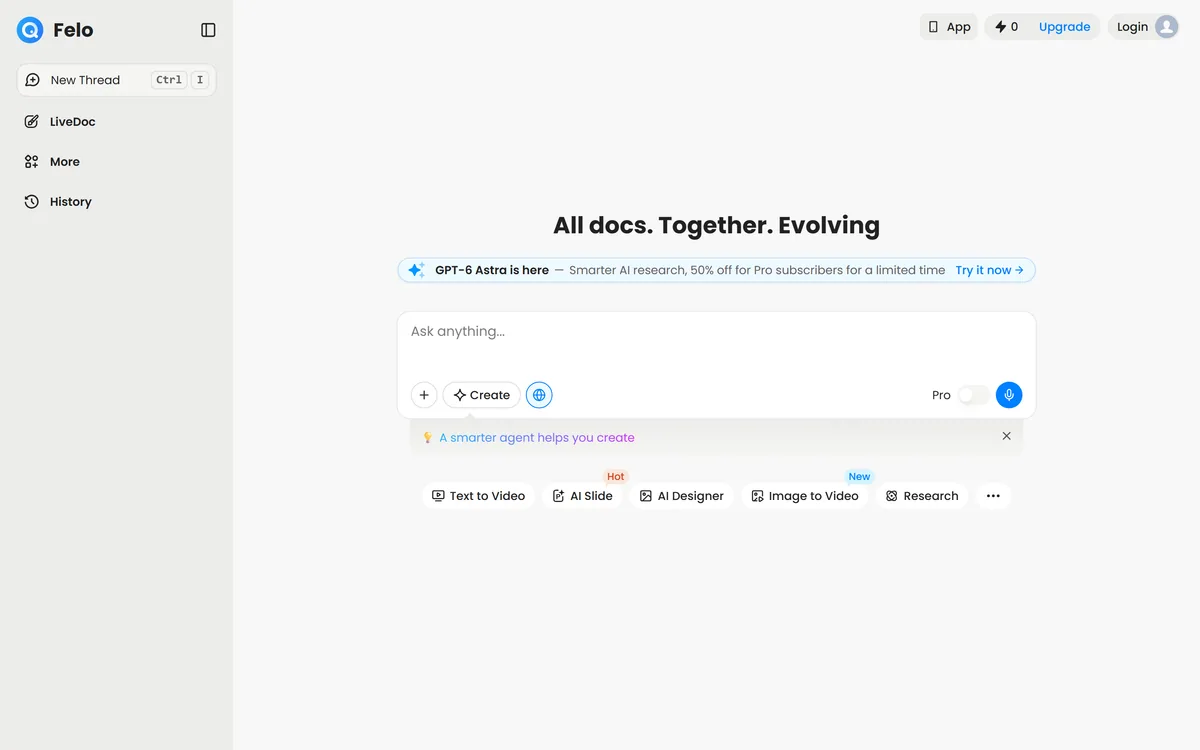
Felo is a multilingual AI search and creation platform from Felo Inc. It pairs an answer engine with Felo Slides, an agent mode, an LLM playground, LiveDoc and an API, with the multilingual layer as its distinguishing feature rather than an afterthought.
Good
Felo is worth attention for two reasons that have little to do with the answer engine itself. It treats multilingual search as the product rather than a translated interface, which matters enormously if your sources are in Japanese, Chinese or Korean and Western tools quietly ignore them. And it closes the loop from research to deliverable — an answer becomes a deck in one step, which is what most search-for-work actually ends in. It loses ground because the answer-engine layer is a crowded field where it is not obviously the strongest, and because the model behind any given feature is not disclosed. AInexfinder Editor Score: 3.9/5.
Best for: Research across Japanese, Chinese, Korean and other non-English sources; Analysts whose work ends in a deck rather than a document
The visit link goes to felo.ai, the official site. Paid placements on AInexfinder are always labelled. How we make money
Most AI search tools are built by English-speaking teams for English-speaking users, and the consequence is invisible until it matters.
Ask about a Japanese regulatory change or a Chinese manufacturing standard and you will often get an answer assembled entirely from English-language coverage of the thing, rather than from the thing itself.
Felo comes at search from the other direction. It is a multilingual platform first, and the rest of what it does — slides, agents, documents, an API — is built around the assumption that the research and the deliverable may not be in the same language.
Felo describes itself as a free multilingual AI search and creation platform, and that word does more work than it appears to.
There are two different things a tool can mean by multilingual. The weak version is a translated interface: the buttons are in your language, and the search still runs across predominantly English sources. The strong version is retrieval across languages — the tool finds Japanese sources for a Japanese question, or finds them for an English question and answers you in English.
The second is genuinely useful and much harder to build, because it requires the retrieval layer to work across scripts and search conventions that differ substantially from English.
The practical test is easy to run yourself, and worth running before committing. Ask about something where the authoritative sources are not in English — a regulation, a local market, a company that files in another language — and look at what it cites. If the citations are in the source language, the retrieval is real. If they are all English-language secondary coverage, you have the weak version.
For anyone working across Asian markets specifically, this is not a nice-to-have. The gap between what an English-first tool surfaces about Japan and what actually exists in Japanese sources is large enough to change conclusions.
The comparison to run is against whatever answer engine you already use. Perplexity is the sensible baseline, precisely because it is strong enough on general questions that anything replacing it has to win somewhere specific.
There are two things a tool can mean by multilingual: a translated interface, or retrieval that actually crosses languages. Only one of them changes your answers.
Felo Slides generates presentations, and its position inside a search product is the interesting part rather than the slide generation itself.
Think about what research for work actually ends in. Very rarely a satisfied curiosity; far more often a deck, a memo or a document that someone else reads. The search tool answers the question and then hands you a wall of text you must restructure by hand.
That restructuring is where most of the time goes, and it is also where most of the sourcing gets lost. Facts move from an answer with citations into slides without them, and the deck arrives looking more certain than the research was.
Generating slides directly from the answer closes that gap mechanically. Whether it closes it well depends on something you should check: does the deck keep the citations, or does it strip them? A sourced deck is far more defensible than a confident one.
Expect to edit heavily regardless. Generated slides are a reasonable first structure — the argument in order, the sections identified — rather than a finished deliverable, and treating them as finished is how errors reach an audience.
If the deck rather than the research is the hard part, a dedicated generator such as Gamma produces a better-looking result — at the cost of the research and the slides living in different places.
Felo's product set runs wider than search — an agent mode, an LLM playground, LiveDoc and an API — and knowing which to reach for saves time.
Search answers a question. Agent mode is for tasks with several steps that depend on each other, where the second search depends on what the first returned, and it is worth the extra latency only when the task genuinely has that shape.
The LLM playground is for comparison rather than production. It is where you find out whether a given model handles your kind of question well before building anything on it, and that is a more useful habit than most people practise.
LiveDoc extends the platform into documents, which matters if your output is prose rather than slides. The API is what makes any of it repeatable — the difference between a person doing research and a process that runs on a schedule.
Most users will live in search and Slides. The rest is worth knowing about at the point where the manual version starts repeating itself.
The free tier makes evaluation cheap, and the way to use it is to test the thing that differentiates rather than the thing everyone has.
Every AI search tool answers general questions acceptably. Comparing them on that produces a tie and tells you nothing.
Run the multilingual test first, because it is the only question where the answer could be decisive.
Two things are worth knowing before you build a workflow on this, and neither is stated on the marketing pages.
The first is which models sit behind which features. Felo offers an LLM playground, which implies multiple models are available, but the site does not say what powers ordinary search or Slides. That matters for anyone with a policy about where data goes, and for anyone whose answer quality expectations are model-specific.
The second is how the free tier is bounded. Free tiers on AI search products almost always carry limits on searches, model access or output volume, and the shape of those limits determines whether free is a trial or a usable state. The site presents a free entry point without our being able to establish where it stops.
There is a corporate footer with Enterprise, Blog, Tools, Privacy and Terms sections, which is more transparency than many AI startups offer and the right place to start if data handling is a constraint for you.
None of this is disqualifying. It is the ordinary due diligence for a tool that will hold your research questions, which are frequently more sensitive than the answers.
For academic work the gap is wider still. A literature tool like Elicit retrieves from indexed papers rather than the open web, which is a different and considerably more reliable corpus for that job.
Multilingual AI search presented as the platform's core proposition
Felo Slides for generating presentations from research output
Agent mode for multi-step research and task execution
LLM Playground for comparing model behaviour
LiveDoc for document-oriented work alongside search
API access for programmatic use
Auspia SEO automation offered alongside the core platform
A free tier for evaluation without commitment
AI search tools differ most in what they retrieve and what they hand you at the end — not in how the chat box looks.
| Tool | Distinguishing angle | Output beyond text | Best for |
|---|---|---|---|
| Felo | Multilingual retrieval as the core proposition | Slides, LiveDoc, agent mode, API | Research where the sources are not in English |
| Perplexity | Citation-led general answer engine | Threads and collections | Everyday sourced search |
| Genspark | Generated pages per query | Sparkpages | Broad topic overviews |
| Gamma | Deck generation as the product | Presentations, docs, sites | When the deliverable matters more than the research |
| Elicit | Academic literature specifically | Structured evidence tables | Research papers rather than the open web |
| Publisher | Felo Inc. |
|---|---|
| Positioning | Free multilingual AI search and creation platform |
| Core product | AI search with an answer-engine interface |
| Felo Slides | Presentation generation from research output |
| Agent mode | Multi-step task execution |
| LLM Playground | Model comparison and experimentation |
| LiveDoc | Document-oriented workspace |
| Auspia | SEO automation product listed alongside the core platform |
| API | Available for programmatic access |
| Pricing | A free tier is offered; paid structure not established |
| Footer sections | Enterprise, Blog, Tools, Privacy, Terms |
Felo sits between the answer engines and the deck generators, and both neighbours are worth knowing.
Last checked . Read from felo.ai and its footer navigation, with the screenshot above captured in the same session.
What we could not confirm: which underlying models power search, Slides or the agent; the limits that bound the free tier; the paid pricing structure; whether Slides output preserves citations from the source answer; how many languages are supported and whether retrieval genuinely crosses languages or the interface is merely localised; company size, funding or headquarters; and any independent benchmark of answer quality. We did not run comparative searches, so nothing here reflects tested retrieval performance.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Felo website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Felo earns an AInexfinder Editor Score of 3.9/5 (good). Best for: Research across Japanese, Chinese, Korean and other non-English sources; Analysts whose work ends in a deck rather than a document; Teams working across Asian markets where English coverage is secondhand.
Visit FeloLog in to write a review.
No reviews yet. Be the first to share your experience with Felo.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Felo from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Genspark review on AInexfinder — freemium AI tool for AI Chatbots & Assistants. Features, pricing notes, and alternatives.
Exa is a search API that gives AI agents real-time access to the web, built on its own large index, embedding and retrieval models, with selectable latency, search verticals, token-efficient highlights, structured enrichments and an MCP server.
Liner splits into three purpose-built agents: everyday search returning cited answers with one-click verification and mind maps, Liner Scholar for finding, comparing and citing papers and building literature reviews, and a writing agent that drafts, verifies and edits in the same window.
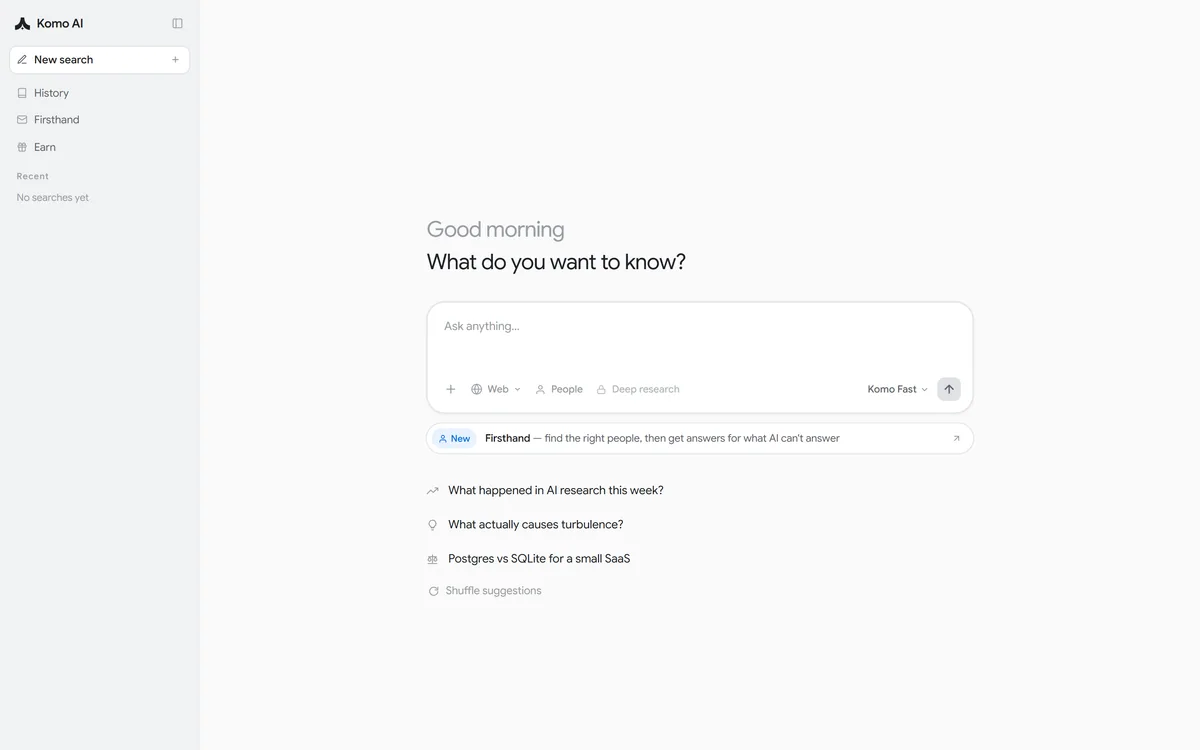
Komo is an AI search engine that answers with sources across three modes — Web, People and Deep research. Its Firsthand feature finds the right people to answer what AI cannot, and it offers a Komo Fast model, saved history and an Earn programme.

Claude is Anthropic's AI assistant, available on web, desktop, mobile, and in Chrome, with Projects for persistent context, Artifacts for generated documents and apps, Skills, Connectors, and Claude Code for developers.

ChatGPT is OpenAI's AI assistant, covering conversation, document and image work, web browsing, Projects, Tasks, custom GPTs, agent actions, and the Codex coding agent, across web, desktop, and mobile.
Related Pages