HeyGen creates realistic AI avatar videos featuring you, with consistent identity across clips, a text-based studio, translation and lip-sync in 175+ languages, and an unusually serious stance on verified identity and moderation.
Video & Audio Review
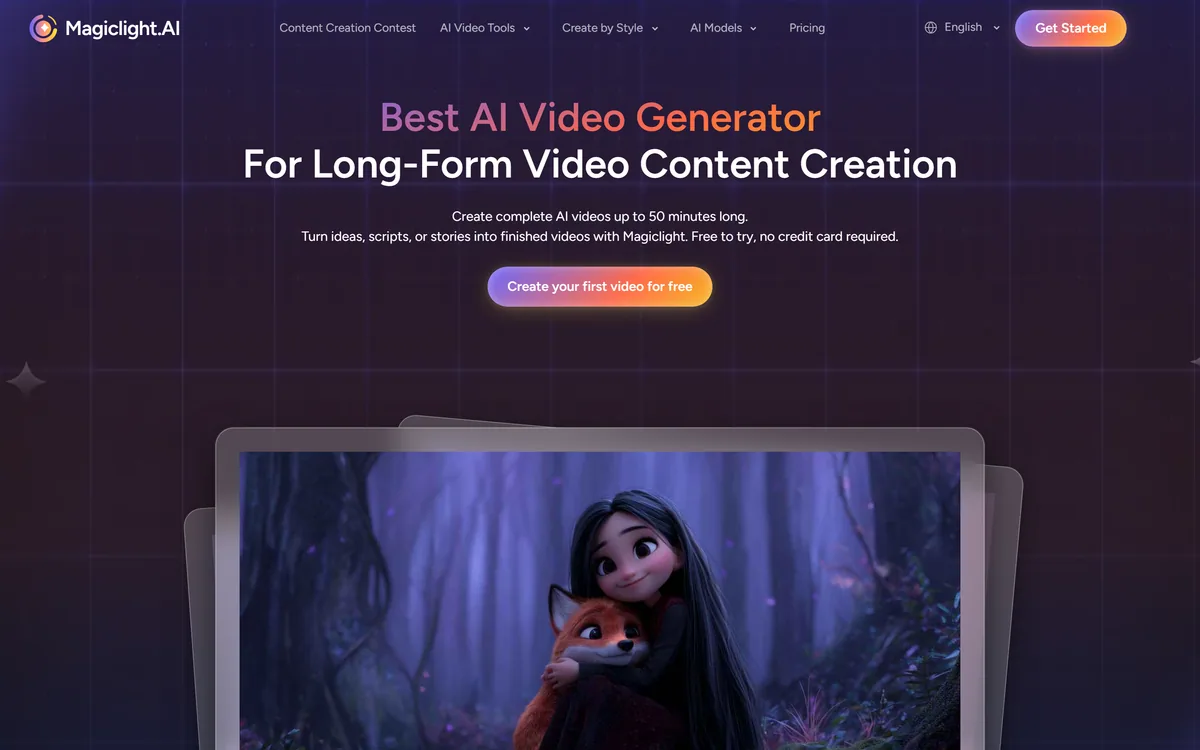
MagicLight AI generates multi-scene videos up to 50 minutes from a story, script, text, image or music track. It routes across Seedance, Kling, VEO, Sora and Wan models, and adds voice cloning, lip sync and subtitles.
Good
MagicLight AI has an AInexfinder Editor Score of 3.9/5.
Best for: Long-form narrated YouTube channels currently built as slideshows with voiceover; Children's story and folklore content where stylisation is expected
The visit link goes to magiclight.ai, the official site. Paid placements on AInexfinder are always labelled. How we make money
The generative video field has an awkward shape. Model quality per second has improved enormously, and almost every tool still hands you something between five and fifteen seconds long. Anyone who has tried to assemble a ten-minute video out of forty such clips knows where the work actually is: in the joins.
MagicLight AI attacks the other axis. Rather than competing on how beautiful one clip looks, it aims at complete videos of up to fifty minutes, with characters who remain recognisably themselves from scene to scene and transitions that hold the sequence together.
This review covers what long-form generation genuinely solves, why routing across several third-party models is a sensible design rather than a weakness, where the seams still show, and who this actually suits.
Long video generation of up to 50 minutes
Character consistency maintained across scenes
Story, script, text, image and music inputs
Routing across Seedance, Kling, VEO, Sora and Wan models
AI voice cloning from a sample
AI lip sync for generated characters
Automatic subtitle generation
AI avatar video generation for presenter-led content
AI animation generation without manual animation work
An AI video editor for refining output after generation
These tools are solving different problems, and length is the axis that separates them.
| Tool | Typical output length | Main strength | Best suited to |
|---|---|---|---|
| MagicLight AI | Up to 50 minutes, multi-scene | Assembly, consistency and audio across a long piece | Narrated long-form channels and story content |
| Runway ML | Short clips | Per-shot quality and creative control | Filmmakers who will assemble the edit themselves |
| Luma Dream Machine | Short clips | Motion quality and realism in a single shot | Individual shots destined for a real edit |
| InVideo AI | Medium-length assembled videos | Stock-led assembly with a script | Marketing videos built from existing footage |
| Fliki | Medium-length narrated videos | Text-to-video with strong voice generation | Blog-to-video and narrated explainers |
Generate one clip of a character and the model invents a person. Generate the next clip and, without something holding it steady, it invents a slightly different person — the jaw changes, the jacket shifts colour, the hair is not quite the same.
Over ten seconds, nobody notices. Over ten minutes, it is the only thing anybody notices, and it is why so much long AI video feels uncanny in a way viewers cannot articulate.
MagicLight's character consistency work is therefore not a nice-to-have feature sitting alongside the length claim; it is the thing that makes the length claim mean anything. The same applies to its scene transitions. A cut that lands wrong is survivable once and exhausting forty times.
Judge the product on this before anything else. Generate a character, put them in six scenes, and watch whether they stay one person.
Anyone can generate ten seconds. The difficulty is generating the eleventh through the six-hundredth and having them belong to the same film.
MagicLight lists integration with several third-party video models — Seedance 2.5, Kling 3.0, VEO 3, Sora 2, Wan 3.0 and others. It is an orchestration layer over models built elsewhere rather than a lab with its own.
That is worth understanding rather than holding against it. Frontier video models cost enormous sums to train, and a company competing on assembly rather than on generation can adopt whichever model is currently best instead of defending its own. When a stronger model appears, a router benefits; a single-model product has to catch up.
The trade-off is exposure. Pricing, availability and terms for the underlying models are set by other companies, and a change upstream lands on you. The other consequence is that raw clip quality is not really MagicLight's variable to control — it is roughly whatever the underlying models produce. What MagicLight owns is everything between the clips.
For a buyer, the practical reading is simple: choose this for the assembly, not for the pixels.
The input modes are not interchangeable, and picking the wrong one is the most common way to get a disappointing result.
Story to Video takes a narrative and breaks it into scenes itself. Script to Video assumes you have already made those decisions and follows your structure.
The distinction matters more than the names suggest. If you have a script, use the script path — handing a finished script to a story parser invites it to re-cut work you already did well.
Text to Video suits short pieces where you have an idea but no written structure. Image to Video animates a still you already have, which is the most controllable of all the modes because you have fixed the look before generation starts.
Music to Video builds visuals synchronised to an audio track, aimed at lyric videos and music-led content. It is the most forgiving mode for weak per-scene coherence, because music carries the through-line that narrative otherwise has to.
Voice cloning, lip sync and subtitle generation sit underneath all of the above, alongside an AI avatar generator and an AI video editor for refinement.
Lip sync is the one to test hardest. Human viewers detect mismatched mouth movement instantly and unconsciously, and a fifty-minute video with drifting sync is unwatchable regardless of how good the visuals are.
The length claim invites the wrong expectation. Nobody is producing a broadcast-quality half-hour drama here, and treating that as the benchmark guarantees disappointment.
The genuine fits are content formats where duration matters and cinematic polish does not. The site's own template categories point at exactly this — children's stories, faith content, explainers and comedy — and they share a structure: narration-led, forgiving of stylisation, and long by nature.
Long-form YouTube channels built on narrated stories are the clearest case. So are audiobook-style visualisations, extended educational sequences, and anything currently being made as a slideshow with a voiceover, where generated scenes are a straightforward upgrade.
What it is not for is anything where a single shot has to be right. Advertising, brand film, or any piece where a client will review frame by frame belongs to a different production process entirely.
Long-form generation punishes an unstructured approach far more than short clips do, because errors compound over minutes rather than seconds.
| Product type | Long-form AI video generation |
|---|---|
| Maximum length | Up to 50 minutes |
| Input modes | Story, script, text, image, music |
| Underlying models | Seedance 2.5, Kling 3.0, VEO 3, Sora 2, Wan 3.0 and others |
| Consistency features | Character consistency and scene transitions across a full video |
| Audio tools | AI voice cloning, AI lip sync, AI subtitle generator |
| Additional generators | AI animation, AI avatar video, image to video, music to video |
| Editing | AI video editor for refinement after generation |
| Template categories | Children's stories, faith content, explainers, comedy |
| Output | Downloadable multi-scene video |
| Named audiences | Content creators, marketers, educators, parents |
Generation, assembly and narration are separable problems, and different tools own different ones.
Last checked . Taken from magiclight.ai during this check, with the screenshot above captured at the same time.
Observations about consistency drift, lip sync and shot-length degradation are general characteristics of generative video and apply across the category rather than to MagicLight specifically. Model availability through a routing platform depends on third-party providers and can change.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official MagicLight AI website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
MagicLight AI earns an AInexfinder Editor Score of 3.9/5 (good). Best for: Long-form narrated YouTube channels currently built as slideshows with voiceover; Children's story and folklore content where stylisation is expected; Educators producing extended explainers rather than short clips.
Visit MagicLight AILog in to write a review.
No reviews yet. Be the first to share your experience with MagicLight AI.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research MagicLight AI from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
HeyGen creates realistic AI avatar videos featuring you, with consistent identity across clips, a text-based studio, translation and lip-sync in 175+ languages, and an unusually serious stance on verified identity and moderation.
InVideo AI wraps more than two hundred generative models — Veo, Sora, Kling, Seedance, Flux, Nano Banana Pro, ElevenLabs and others — inside one agent-driven editor with project memory, batch shot editing, multiplayer collaboration and unlimited watermark-free exports on paid tiers.
Fliki turns text, scripts, blog posts, presentations and single-line prompts into finished videos with voiceover, visuals, music and subtitles. It offers over 2,000 voices across 80+ languages, voice cloning, a Digital Twin avatar, screen recording with auto-editing, and one-click publishing to TikTok, Instagram and YouTube.
AutoShorts.ai automates faceless short-form video end to end. You choose a series topic and visual style, and it writes the script, generates the visuals, narrates it, adds music and captions, then posts to TikTok, YouTube and Instagram on a schedule without you touching it.
AI and human transcription and subtitles in 150+ languages

ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.
Related Pages