The enterprise AI problem in 2026 is not scarcity. Most large companies have a copilot licence, a handful of departmental tools and an unmeasured amount of staff using consumer chatbots on work data.
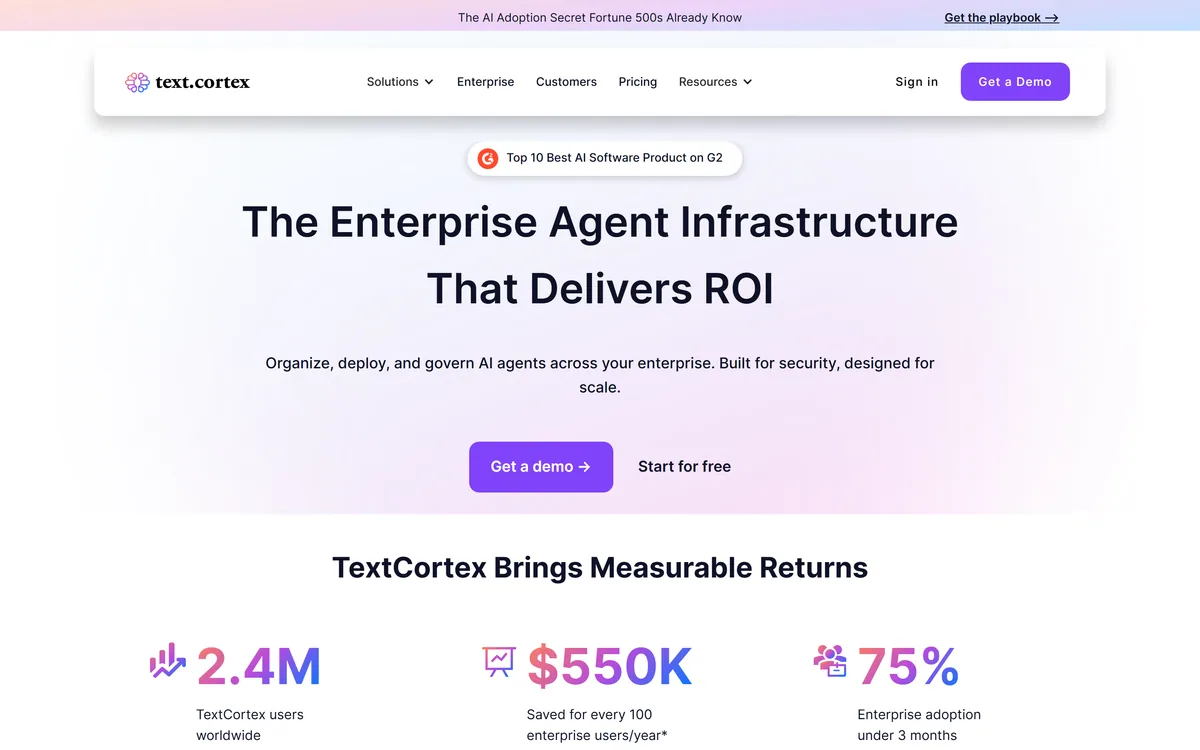
TextCortex names all three conditions on its homepage — generic copilots that miss complex workflows, in-house bots nobody owns, and shadow AI everywhere — and sells itself as the layer that consolidates them.
That framing is worth taking seriously, because it is a more accurate description of what CIOs are dealing with than most vendors in this category manage.
TextCortex: Scale And Location
| Company | TextCortex AI, developed in Berlin per the footer |
|---|
| Positioning | Enterprise agent infrastructure that delivers ROI |
|---|
| Claimed users | 2.4 million worldwide |
|---|
| Savings claim | 550,000 dollars saved per 100 enterprise users per year, from a study of 2,000 enterprise users |
|---|
| Adoption claim | 75% enterprise adoption in under three months |
|---|
| Agent builder | Visual, no-code, connected to company data |
|---|
| Interaction | @mention agents in Slack, Teams and elsewhere |
|---|
| Automation | Scheduled agents delivering results daily, weekly or monthly |
|---|
| Model access | Model hub across major providers, stated as no lock-in |
|---|
| Data policy | Zero data training, stated on the site |
|---|
| Certifications | SOC 2 and ISO 27001, with GDPR alignment stated |
|---|
| Integrations | 30,000+ apps and sites via a browser extension |
|---|
TextCortex: Agent Infrastructure For Enterprises
- Positioned as infrastructure, not an assistant — organise, deploy and govern agents across a company.
- Model-agnostic hub with access to major models, no single-vendor lock-in and a stated zero-training policy.
- Built in Berlin, with European data sovereignty, GDPR alignment, SOC 2 and ISO 27001 certification.
- Agents where people already work — @mention them in Slack or Teams, or schedule them to run unattended.
- 2.4 million users claimed worldwide, with a savings figure drawn from a study of 2,000 enterprise users.
What Problem Does Shadow AI Actually Create?
TextCortex names shadow AI as one of three hidden frictions: no central platform, employees using unapproved tools, risky data use.
It is worth being precise about why that matters, because the phrase gets used loosely and the real risk is narrower than the panic suggests.
The exposure is not that staff use AI. It is that nobody knows which data left the building, under whose terms, and whether it can be recalled. A pasted contract, a customer list in a prompt, a codebase fragment — each is a disclosure that no log records.
The second exposure is quieter and more expensive. When every team solves the same problem with a different tool, the organisation pays several times for one capability and gets no compounding benefit, because none of it is shared.
Banning tools does not fix either. It moves usage to personal devices where visibility drops to zero, which is why the credible answer is a sanctioned platform good enough that people prefer it — a governance argument that Typeface makes in marketing and TextCortex makes across the whole company.
Banning AI tools moves the usage to personal devices, where your visibility drops to zero. The fix is a sanctioned platform people prefer.
Why European Data Sovereignty Sells
Data sovereignty appears as a first-class feature here rather than a compliance footnote, alongside GDPR, ISO and SOC 2, and the Berlin origin is stated in the footer.
For a large part of the European market this is the whole purchasing conversation.
The reason is structural. A GDPR-covered organisation has to establish a lawful basis and a transfer mechanism for personal data leaving the EU, and every AI vendor whose inference runs elsewhere makes that a project rather than a checkbox.
A stated zero-training policy addresses the other half of the question, which is whether your data improves someone else's model. It is a policy commitment rather than a technical guarantee, and it should be verified in the contract rather than from a homepage.
The strategic read is that European sovereignty is a durable differentiator rather than a passing one. Regulatory divergence is widening, not narrowing, and vendors built inside that constraint have an advantage that a US platform cannot easily retrofit. Self-hostable tools such as Khoj answer the same question a different way, at a much smaller scale.
The headline states 550,000 dollars saved for every 100 enterprise users per year, footnoted as measured across a study of 2,000 enterprise users, alongside 2.4 million users worldwide and 75 percent adoption in under three months.
Attaching a footnote with a sample size puts this ahead of most vendor ROI claims, and it still needs reading carefully.
The figure works out to a substantial annual saving per user, which implies a specific conversion: hours saved multiplied by a loaded labour rate. That conversion is where every productivity study becomes contestable.
Time saved only becomes money saved if the time is redeployed to something valuable or the headcount changes. In practice it is often absorbed, which is a genuine quality-of-work improvement and not a line in a budget.
The supporting case study figures are more useful precisely because they are narrower: five hours saved per employee per week, a 71 percent activation rate, 94 percent reporting increased work quality. Activation rate in particular is the honest metric, because it measures whether people actually use the thing.
- Ask what labour rate any savings figure was converted at.
- Treat activation rate as the metric that predicts your outcome.
- Confirm the zero-training policy in the contract, not the homepage.
- Establish where inference runs before any data classification work.
- Pilot with one department that has a real recurring workflow.
Governance, Adoption And Why Both Fail
The platform pairs infrastructure with what it calls a hands-on partnership: centralising agents, aligning them with workflows and helping teams adopt them safely, plus an adoption playbook claiming 75 percent-plus user adoption in the first 90 days.
That combination is unusual and it addresses the actual failure mode of enterprise AI.
Governance without adoption produces an expensive, compliant platform nobody opens. Adoption without governance produces exactly the shadow AI problem the product exists to solve, with a corporate logo on it.
Most vendors sell one and hope the customer supplies the other. Selling both — with named framework, training academy and implementation support — is a services-shaped answer to a software problem, and it is probably the right shape.
The caution is that this makes the vendor relationship deeper than a licence. Change management delivered by the platform provider is genuinely useful and also creates a dependency worth pricing into the decision, alongside the more obvious question of what happens to your agents if you leave.
What Model Agnosticism Buys You
The model hub is described as secure access to all major models with no lock-in to one provider, and it is a more consequential feature than it first appears.
The obvious benefit is commercial: you are not exposed to a single vendor's pricing or terms, and you can move if either changes.
The less obvious benefit is that models are not interchangeable. One handles long-context reasoning, another follows structured formats reliably, another is cheap enough to run on volume. An organisation running one model for everything is overpaying for simple tasks and underserving hard ones.
There is also a continuity argument. Model versions get deprecated on the provider's schedule, and a platform that can route elsewhere absorbs that disruption instead of passing it to whoever built the agent.
The cost of agnosticism is depth. A platform abstracting over many providers exposes the common denominator, so provider-specific capabilities arrive late or not at all — an acceptable trade for governed enterprise deployment, and a poor one for a team pushing the edge of what a single model can do — which is why a developer tool like Pieces makes the opposite choice deliberately.
Rolling Out Agents Across A Company
Enterprise AI rollouts fail predictably: a broad launch, an enthusiastic first fortnight, then a platform that shows up in the budget and nowhere else.
This sequence follows the order that adoption data actually supports.
- Find where shadow AI already is — that is your real demand signal.
- Pick one department with a recurring, well-defined workflow.
- Build two or three agents for that workflow, not a catalogue.
- Put them where the work happens, in Slack or Teams, not a separate app.
- Measure activation rate weekly rather than hours saved.
- Settle data residency, retention and the training policy in writing first.