
ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.
Video & Audio Review
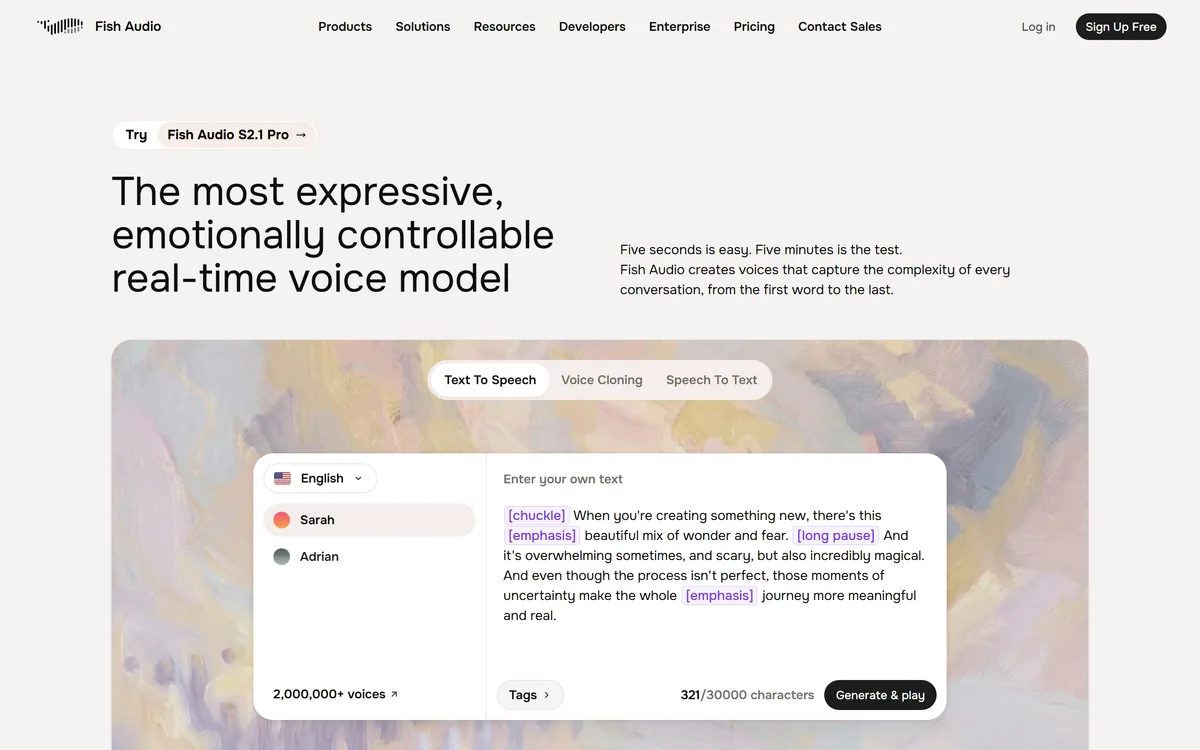
Fish Audio is a voice AI platform offering text-to-speech and voice cloning through its S2.1 Pro model, with a community marketplace of over two million voices. It supports 30+ languages, clones from about ten seconds of audio, exposes REST APIs and SDKs, and open-sources earlier model generations for self-hosting.
Very good
Open-sourcing earlier model generations is the decision that earns this its score — it means you can self-host, audit and keep working if the company changes direction, which no closed voice API offers. It is marked down because a two-million-voice community marketplace raises consent questions the site does not address, and because ten-second cloning lowers the barrier to misuse as much as to legitimate use. AInexfinder Editor Score: 4.2/5.
Best for: Developers building voice features who want to keep the self-host option; Organisations whose audio cannot leave their own infrastructure
The visit link goes to fish.audio, the official site. Paid placements on AInexfinder are always labelled. How we make money
| Category | Text-to-speech, voice cloning and speech AI infrastructure |
|---|---|
| Current model | Fish Audio S2.1 Pro, described by the vendor as ultra low latency and leading on control and expressiveness |
| Earlier generations | Fish Audio S2, S1 and Fish Speech, with open-sourced releases |
| Open source | Maintained on GitHub, with models available for self-deployment |
| Voice marketplace | More than 2,000,000 community-uploaded voices |
| Cloning requirement | Vendor states as little as 10 seconds, with 15 seconds cited for accuracy |
| Languages | 30+, including English, Japanese, Korean, Chinese, French, German, Arabic and Spanish |
| Developer access | REST API endpoints and SDKs, covering TTS and speech-to-text with streaming |
| Charging model | Free monthly generation allowance for personal use, then usage-based and subscription options for commercial rights, with self-hosting available; no prices published here |
Fish Audio open-sources earlier generations of its models, and that decision does more for a certain kind of buyer than any quality claim.
You can run it yourself. For anyone whose audio cannot leave their infrastructure — health, legal, defence, or simply a client contract that forbids third-party processing — self-hosting is not a preference. It is the only configuration that is permitted at all.
You can audit it. A security team can inspect what the model does rather than accepting a description, which is frequently the condition for approval in a regulated environment.
You are not exposed to someone else's decisions. Voice AI has consolidated fast and prices have moved. A model you hold is insurance against a repricing, a deprecation or an acquisition.
Cost changes shape. Hosted APIs charge per character or per second, so a high-volume application pays continuously. Self-hosting converts that into a fixed infrastructure cost, which flips the arithmetic entirely above a certain volume.
The trade-offs are real and worth stating. The open models are earlier generations, so you are not self-hosting the current flagship. You take on GPU costs, deployment and maintenance. And support becomes a GitHub issue rather than a contract. But the option existing at all is what distinguishes this from ElevenLabs and the other closed providers.
A hosted voice API is a rate you accept. An open model is a rate you can walk away from — which is the only leverage anyone has in a consolidating market.
The community marketplace is the headline number and it deserves careful reading rather than admiration.
The genuine upside is variety. Two million voices means you will find something close to what you want without commissioning a recording, across accents, ages, registers and languages that a curated library would never cover.
The question the site does not address is where those voices came from. A community marketplace of uploaded voices, on a platform where cloning takes ten seconds of audio, invites an obvious concern: how many of those two million are clones of people who did not consent?
That is not an accusation about this platform specifically — it is the structural problem with every open voice marketplace, and it is the reason it deserves stating plainly. Ten seconds of audio is a podcast clip, a YouTube video, a voicemail.
The practical implication for a commercial user is concrete rather than philosophical. If you build a product on a community voice and it later transpires that voice belongs to an identifiable person who never agreed, the exposure is yours as much as the platform's. A voice is a person's likeness, protected independently of copyright in several jurisdictions, with new legislation arriving specifically for synthetic voices.
The defensible approach is narrow: use your own cloned voice, use a voice you have written permission for, or use a voice the platform can confirm the provenance of. For anything commercial, ask that question before building rather than after.
Cloning from ten to fifteen seconds of audio is a genuine technical achievement and it is worth thinking about what it means in both directions.
The legitimate uses are strong. A creator can clone their own voice and narrate a back catalogue without recording sessions. An accessibility application can preserve someone's voice before a medical procedure affects their speech. A company can maintain a consistent brand voice across a content library produced over years by different people.
The other direction is equally obvious and does not require malice to cause harm. Ten seconds is a trivial amount of publicly available audio for almost anyone who has ever appeared on a podcast, a webinar, a video call recording or social media.
This is why the consent question above is not academic, and why any organisation deploying voice cloning should have a written position on it before the first clone rather than after the first incident.
For your own voice, the questions to settle are what happens to the model when you close the account, whether it can generate audio you have not authorised, and whether self-hosting lets you keep the model rather than leaving it on someone else's platform. That last one is a genuine advantage of the open-weight route.
None of this is a reason to avoid the technology. It is the diligence the technology requires, and it applies equally to every vendor in the category.
This site does not publish plan prices. Fish Audio's structure has three distinct routes and the differences matter more than the numbers.
There is a free monthly generation allowance for personal use, usage-based and subscription plans that carry commercial rights, and self-hosting of the open models as a third path entirely.
The most important thing to notice is that commercial rights are tied to the paid tiers. That is a common structure and an easy one to fall foul of — generating audio on a free allowance and shipping it in a product is the kind of mistake discovered late and awkwardly. Establish which tier permits commercial release before you build anything.
Usage-based charging is the right shape for infrastructure and it has the standard consequence: cost scales with success. For a consumer application where users generate freely, model cost per active user carefully, because voice generation is not proportional to what a user pays you.
The self-hosting route changes this completely. Above a certain volume the fixed cost of running your own inference undercuts per-character API pricing substantially, and that crossover point is worth calculating rather than assuming. It is the main reason to care that the models are open at all.
One question specific to the marketplace: whether using a community voice carries different commercial terms from using your own clone. Those are not obviously the same thing and the answer should be in writing.
Placing this accurately is more useful than praising it, and the category is unusually well differentiated.
Against ElevenLabs: ElevenLabs remains the quality and ecosystem benchmark, with more products built around the models. Fish Audio's counter is openness, the marketplace and self-hosting. If quality is the only axis, ElevenLabs; if control matters, Fish.
Against Inworld: Inworld is infrastructure obsessed with realtime latency and model routing for conversational agents. Fish Audio is closer to a voice platform with an API. They overlap on TTS and differ on what surrounds it.
Against Murf: Murf is a finished voiceover product for people who want to make a narration, not build a system. Different buyer entirely.
Against ACE Studio: singing synthesis is a genuinely different problem, and ACE Studio is where that lives.
The honest summary is that Fish Audio is the option for people who want to keep their options — developers building on voice who do not want a single vendor holding the model, the rate card and the roadmap.
Four terms that decide what you are actually comparing between vendors.
Text-to-speech with the S2.1 Pro model
Voice cloning from roughly ten seconds of audio
Community voice marketplace with over two million voices
30+ language support
Open-sourced earlier model generations for self-hosting
REST API endpoints and developer SDKs
Speech-to-text alongside synthesis
Streaming output for realtime applications
Emotional and expressive control over generated speech
The useful axis is how much control you keep, not which sounds marginally better on a demo.
| Tool | Model access | Voice source | Buyer |
|---|---|---|---|
| Fish Audio | Open weights for earlier generations, hosted current model | 2M+ community marketplace plus your own clones | Developers who want the self-host option |
| ElevenLabs | Closed, hosted only | Curated library plus cloning | Teams prioritising quality and ecosystem |
| Inworld AI | Hosted, with model routing | Own models plus third-party | Realtime conversational products |
| Murf | Closed, hosted product | Curated library | People making a voiceover, not a system |
| Speechmatics | Recognition rather than synthesis | Not applicable | Transcription accuracy across accents |
The category splits by whether you want a product, an API, or a model you can hold.
Last checked . Read from fish.audio during this check, with the screenshot above captured at the same time.
Model quality, latency and marketplace figures are the vendor's own and were not independently benchmarked. A community marketplace of two million uploaded voices on a platform where cloning takes ten seconds of audio raises consent questions the site does not address — establish provenance before using any marketplace voice commercially. A recorded voice is a person's likeness with protection independent of copyright in several jurisdictions, and commercial rights here are tied to paid tiers rather than the free allowance.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Fish Audio website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Fish Audio earns an AInexfinder Editor Score of 4.2/5 (very good). Best for: Developers building voice features who want to keep the self-host option; Organisations whose audio cannot leave their own infrastructure; High-volume applications where per-character API pricing becomes the constraint.
Visit Fish AudioLog in to write a review.
No reviews yet. Be the first to share your experience with Fish Audio.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Fish Audio from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
ElevenLabs is an AI audio platform covering text to speech, voice cloning, speech recognition, dubbing, music, and conversational voice agents, with a library of 5,000+ voices across more than 70 languages and an API behind every model.
PlayHT review on AInexfinder — freemium AI tool for Video & Audio. Features, pricing notes, and alternatives.
TTSReader turns text, PDFs, and EPUB files into speech in the browser, with voice and language selection, speed control, text highlighting, and MP3 export — the free tier runs on browser voices with no usage cap.
VMEG from PixRipple translates and dubs video into 170+ languages using 17,000+ voices, with voice cloning, lip-sync, subtitle generation, batch processing, and API and MCP access for automated localisation.
AI and human transcription and subtitles in 150+ languages

Runway is an AI video platform built around generative world models — Gen-4.5, Aleph 2.0, and Act-Two for performance capture — split across Runway Creative for filmmakers, Runway Dev for builders, and Runway Robotics.
Related Pages