
Conversational AI characters and NPCs for games Category: Emerging & Specialized.
Emerging & Specialized Review
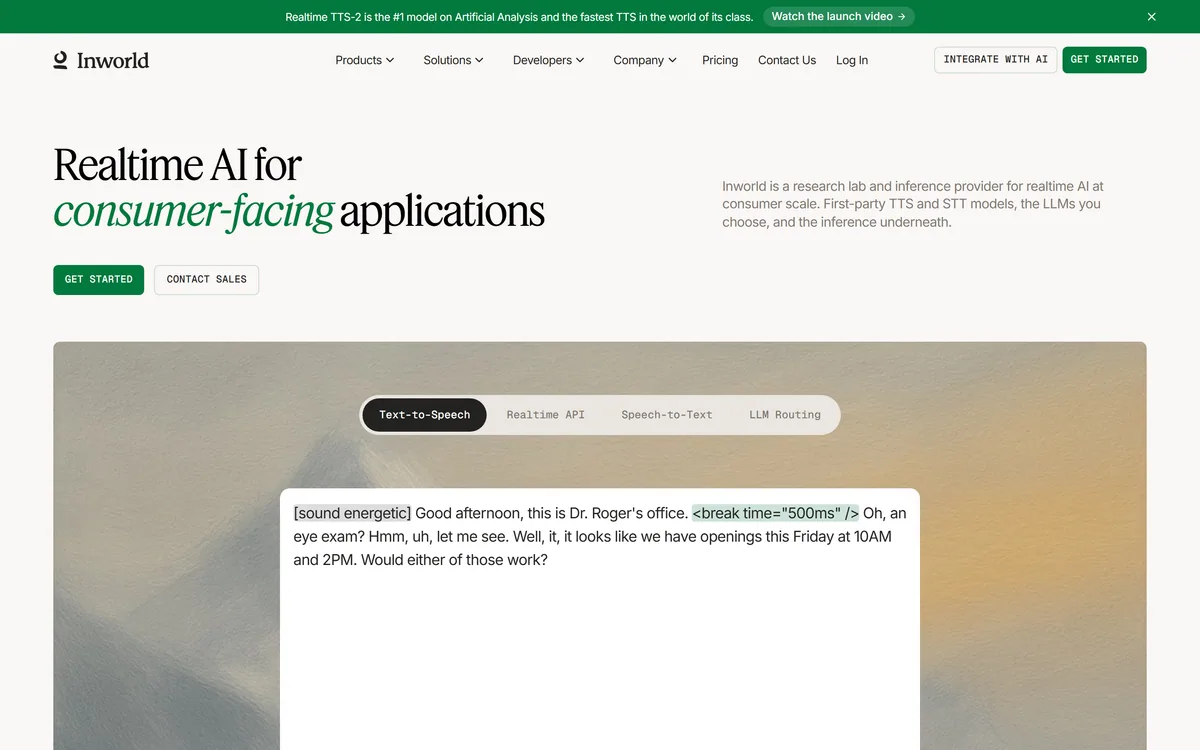
Inworld AI is a research lab and inference provider supplying realtime voice infrastructure. Its products cover text-to-speech, speech-to-text, a realtime API, its own inference, a router across 220+ language models, and compute — used to build voice agents, companions and interactive media.
Very good
Inworld AI has an AInexfinder Editor Score of 4.3/5.
Best for: Teams building voice agents, companions or conversational apps; Language learning products needing many languages and one voice
The visit link goes to inworld.ai, the official site. Paid placements on AInexfinder are always labelled. How we make money
| Category | Realtime AI voice infrastructure and inference |
|---|---|
| Company description | Research lab and inference provider |
| Named products | Realtime TTS, Realtime STT, Realtime API, Realtime Inference, Realtime Router, Compute |
| TTS models | inworld-tts-2 in research preview, and inworld-tts-2-flash for lowest latency |
| TTS language coverage | 200+ languages, with cross-lingual voice identity |
| Stated TTS latency | 100ms P90 time-to-first-byte for TTS-2; 20ms P90 for TTS-2 Flash, both server-side |
| STT models available | inworld-stt-1, plus Whisper large v3 via Groq, AssemblyAI Universal-3 and Soniox real-time models |
| Model router | 220+ language models across third-party and first-party inference tracks |
| Named customers | Wishroll/Status, Bible Chat, Talkpal |
| Stated customer result | Wishroll/Status cited as reaching 1 million users in 19 days |
| Sectors served | Companions, social apps, games, customer support voice agents, sales agents, phone agents, language learning, interactive media |
| Enterprise deployment | VPC deployments available |
| Charging model | Usage-based; no prices published here |
Four terms you need in order to read any voice infrastructure claim properly.
Inworld built its early reputation on AI characters for games — non-player characters you could actually talk to, with personalities, memories and goals. That was the story, and it attracted a great deal of coverage in games media.
The company now describes itself as a research lab and inference provider, and its product list is infrastructure: TTS, STT, an API, inference, a router, compute. No game engine integrations appear in the current material.
That is a significant change and it is worth understanding rather than glossing. The character-platform pitch asked developers to build inside someone else's framework. The infrastructure pitch sells components that go into whatever you are already building.
The strategic logic is sound. A character platform competes with every game studio's own preference for building its own systems, and it is a narrow market. Realtime voice infrastructure serves companions, support agents, phone systems, language learning and games alike — a much larger surface with a clearer buyer.
It also plays to what was genuinely hard about the original problem. Making a character feel alive was always mostly a latency problem, and latency engineering transfers to every voice application.
The practical implication: if you arrived here from an article about AI NPCs, evaluate this as a voice infrastructure vendor. The building blocks are there; the framework around them is now yours to write.
Making a game character feel alive was always a latency problem wearing a costume. Selling the latency directly reaches a far bigger market.
The latency figures are the centre of the offering and they deserve to be understood rather than admired.
Human conversation runs on roughly 200 milliseconds between turns. That gap is remarkably consistent across languages and cultures, and we are exquisitely sensitive to deviation from it. A pause noticeably longer than that reads as hesitation, confusion, or a bad line — before a single word arrives.
That 200ms is the entire budget for a voice agent, and it has to cover everything: detecting that the user stopped speaking, transcribing, sending to a language model, generating a response, synthesising speech, and network round trips in both directions.
Voice quality itself is largely solved — ElevenLabs settled that argument years ago. Time-to-first-byte for speech synthesis is one slice of that budget. At 20ms P90, the flash model consumes a tenth of it, which leaves genuine room for the model call — which is where the unavoidable time actually goes.
That is why an infrastructure company optimising this specific number matters. Every millisecond saved in synthesis is a millisecond available for thinking, and thinking is what makes the answer good.
Two caveats on reading these numbers honestly. They are server-side, so your users' network latency sits on top and can dwarf them. And P90 means one call in ten is slower — in a conversation of thirty turns, that is three noticeable pauses. Ask about P99 if you are building something that must feel consistently natural.
Realtime Router — access to 220+ models across third-party providers and Inworld's own inference — is the most strategically interesting product in the set.
The premise is that model choice should not be an architectural commitment. Models are released constantly, prices move, and the best option for a given task changes on a timescale much shorter than the life of an application.
Routing through one integration means switching is a configuration change rather than a rewrite. It also enables the pattern that actually saves money in production: sending routine turns to a cheap fast model and difficult ones to an expensive capable one, rather than paying frontier rates for every hello.
The first-party and third-party split is worth noticing. Offering both its own inference and external providers means Inworld is positioning as a neutral layer rather than only selling its own capacity — which is more credible than it would be otherwise.
The dependency to think about is the ordinary one for any abstraction layer: you are adding a hop between your application and the model provider, which introduces both a latency cost and a point of failure. In a product where latency is the selling point, that trade-off deserves measuring rather than assuming.
A specialist recogniser like Speechmatics is the alternative if transcription is your only need. Offering established third-party STT models alongside its own — Whisper via Groq, AssemblyAI, Soniox — follows the same neutral-layer logic and is a reasonable signal of confidence.
This site does not publish plan prices. Inworld's structure is usage-based, which is the correct model for infrastructure and has consequences worth planning for.
You pay for what you generate — audio synthesised, audio transcribed, tokens routed — rather than for seats or a subscription. That means cost scales directly with success, which is either reassuring or alarming depending on your product.
The specific risk in voice applications is that usage is not proportional to value. A companion app user who talks for three hours generates the same synthesis cost whether they subscribed or are on a free tier. Consumer voice products can be structurally difficult to make profitable for exactly this reason, and modelling cost per active user is more important here than in most categories.
Two things worth establishing early. First, whether the flash and standard TTS models are priced differently, since the latency premium usually is. Second, how the router prices — whether there is a margin over the underlying provider's rate, and whether first-party inference is cheaper than routing out.
VPC deployment is offered for enterprise, which changes the economics and the data posture together. For anyone in a regulated environment, or handling voice data with residency requirements, that is the conversation to start with rather than the public API.
One point specific to voice: recorded speech is biometric data under several privacy regimes, and the obligations that attach to it are stricter than for text. Settle where audio is processed and how long it is retained before you build on any voice API.
Being clear about the boundary saves the wrong buyer a wasted week.
A deployed agent such as Phonely is what a finished product looks like at this layer. It is not a finished product. There is no interface to log into and configure an agent. These are APIs and models, and you need engineers to assemble them into something. If you want a working phone agent rather than the parts of one, this is the wrong layer.
It is not a game character platform any more, whatever the historical coverage says. No engine integrations appear in the current material, and building an NPC on this means writing the character logic yourself on top of the voice layer.
It is not the reasoning. The router gives access to models; the quality of what your agent actually says is a function of the model you choose and the prompting you write, not of the infrastructure.
What it genuinely is: a specialised, latency-obsessed voice layer for people building conversational products, with the neutrality to avoid tying you to one model provider. For that buyer it is a strong offering, and the named customers — a companion app, a religious chat product, a language learning tool — fit that shape precisely.
Realtime text-to-speech with 200+ language coverage
Cross-lingual voice identity across languages
Low-latency flash TTS variant
Realtime speech-to-text with first-party and third-party model options
Realtime API for voice application development
Model router across 220+ language models
First-party inference alongside external providers
Compute offering
Enterprise VPC deployment
These sit at different layers of the stack, which is the distinction to get right before comparing quality.
| Tool | Layer | Emphasis | You supply |
|---|---|---|---|
| Inworld AI | Infrastructure — TTS, STT, routing, compute | Realtime latency and model neutrality | The whole application |
| ElevenLabs | Voice models and products | Voice quality and cloning | The application, or use their tools |
| Phonely AI | Finished phone agent product | Deployed agents with integrations | Configuration, not code |
| Speechmatics | Speech recognition | Transcription accuracy across accents | Everything downstream |
| Murf | Voiceover product | Studio-style narration | Nothing — it is an app |
Voice products are assembled from several of these, and knowing which layer you need is most of the decision.
Last checked . Read from inworld.ai during this check, with the screenshot above captured at the same time.
Latency figures are the vendor's own, measured server-side, so end-user network latency sits on top of them. P90 means one request in ten is slower than the stated figure — ask for P99 before designing around these numbers. Recorded speech is treated as biometric data under several privacy regimes, with stricter obligations than text, so settle processing location and retention before building on any voice API.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Inworld AI website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Inworld AI earns an AInexfinder Editor Score of 4.3/5 (very good). Best for: Teams building voice agents, companions or conversational apps; Language learning products needing many languages and one voice; Customer support and phone agent builders working at the API level.
Visit Inworld AILog in to write a review.
No reviews yet. Be the first to share your experience with Inworld AI.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Inworld AI from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Conversational AI characters and NPCs for games Category: Emerging & Specialized.
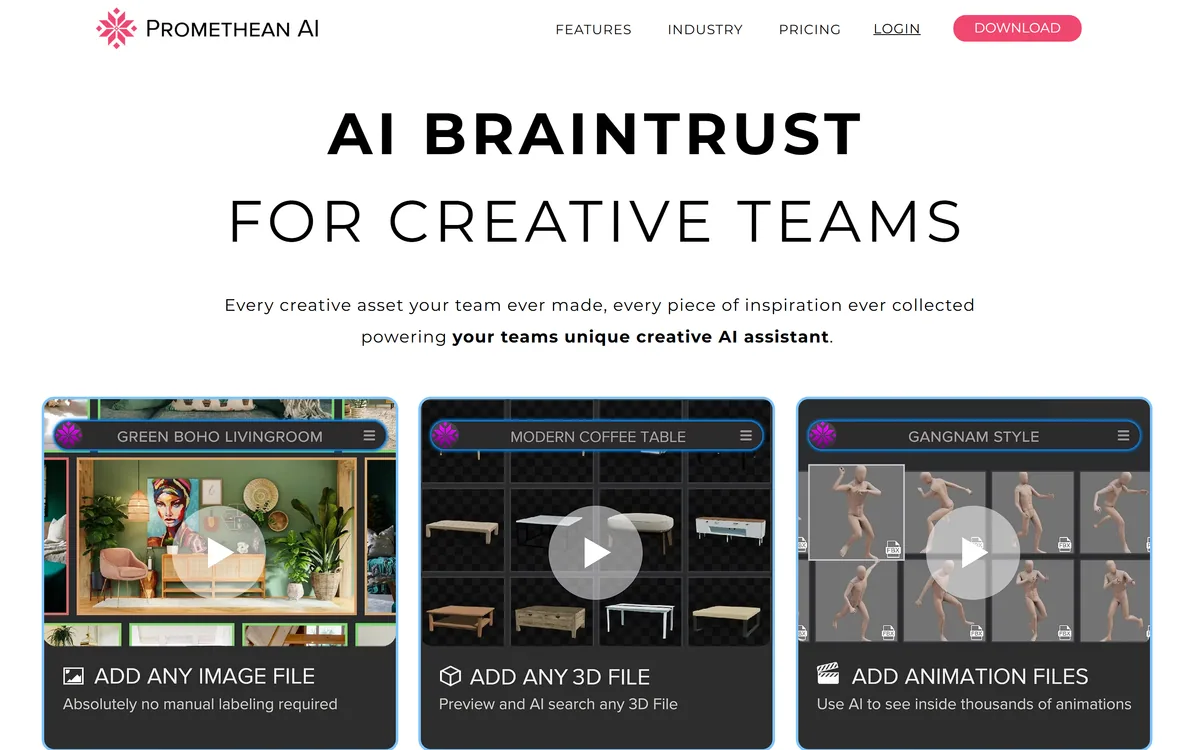
Promethean AI is a world-building assistant for digital art teams that indexes a studio's existing assets as metadata without moving or storing the files, sits on top of Unreal and other 3D editors rather than replacing them, and states over 10,000 users including PlayStation Studios.
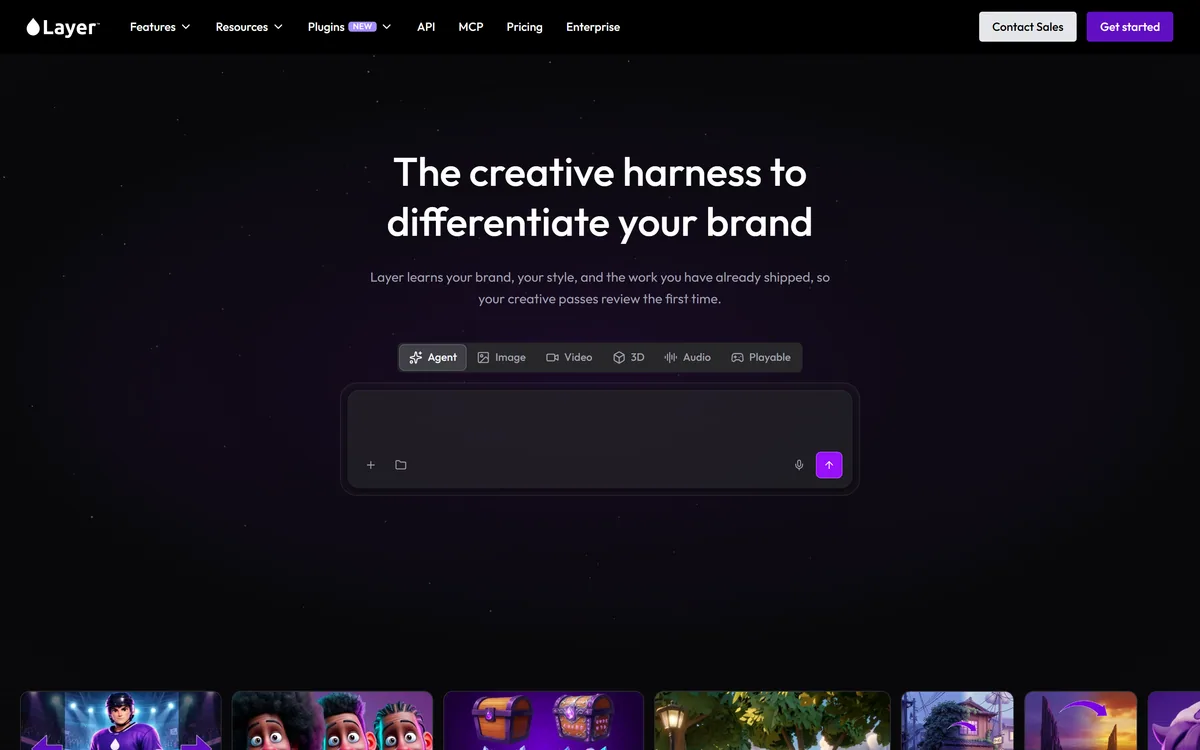
Layer AI is a creative platform for teams that learns your brand and style, then generates image, video, 3D and audio across 300+ models with an agent, LoRA training and editing, plus IP-safety, auditability and enterprise controls.
Friends & Fables runs tabletop roleplaying campaigns with an AI game master called Franz, combining world building tools, tactical turn-based combat on the 5.1 System Reference Document, maps, image generation, narration and multiplayer parties of up to six across desktop, tablet and mobile.
Seele AI's SeeleAgent is a game-focused multimodal AI agent that generates game prototypes, 2D and 3D, alongside images, video, 3D assets and code from prompts, using a skills library and Seele's own multimodal and world models. It is an early, ambitious tool best treated as a prototyping aid.
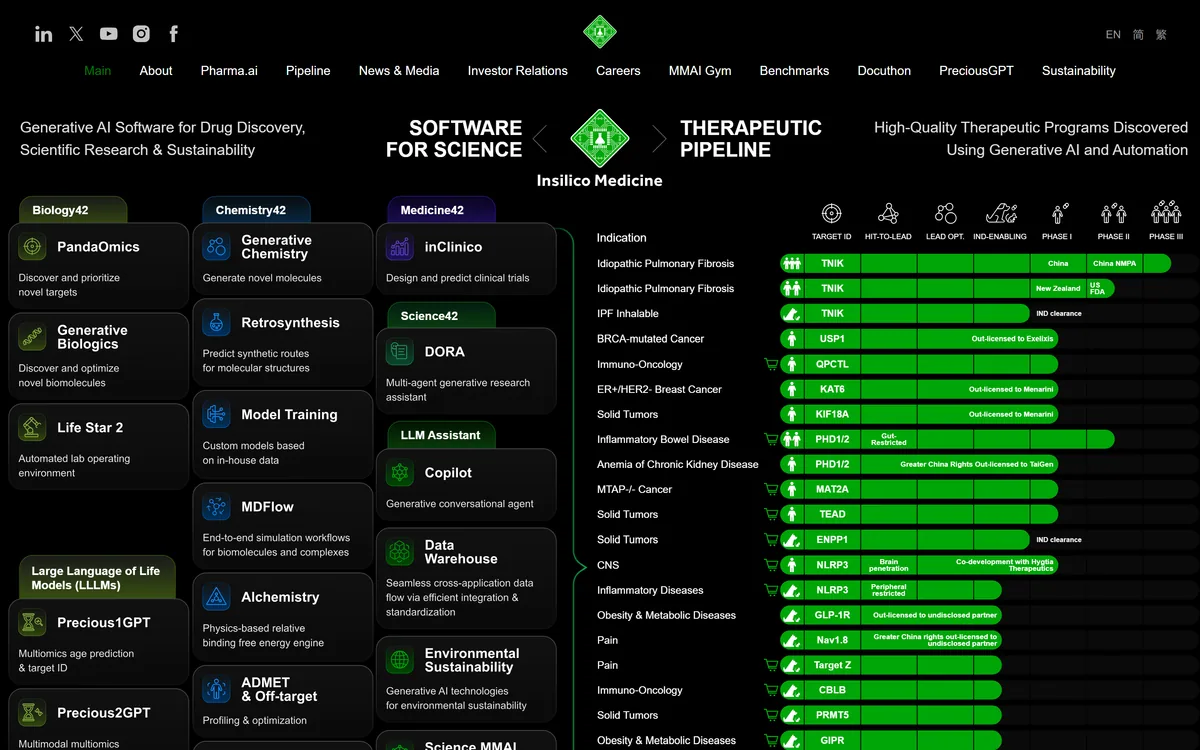
Insilico Medicine pairs the Pharma.ai software suite — PandaOmics, Chemistry42, inClinico and more — with its own clinical pipeline. Its lead candidate rentosertib, a TNIK inhibitor for idiopathic pulmonary fibrosis, has Phase IIa results published in Nature Medicine.
Related Pages