Momentic is an agentic end-to-end testing platform where AI writes tests as plain-English YAML, runs them across web, iOS and Android, and self-heals them when the UI changes, with an autonomous bug-bashing agent, an MCP server and CI integration.
Coding & Development Review
Langfuse is an open-source LLM engineering platform covering tracing, evaluation, prompt management, experiments and human annotation. Every product feature is MIT licensed, with self-hosting via Docker Compose, Kubernetes or Terraform alongside a managed cloud in US and EU regions.
Excellent
Langfuse scores highly for a licensing decision that most open-core vendors deliberately avoid: all product features are MIT licensed, not a stripped community edition with the useful parts held back. That resolves the question every platform team asks — what happens when the vendor changes direction — because the answer is that you fork it. Underneath that, the feature set is the right one: hierarchical traces that capture tool calls and retrieval rather than just completions, evaluation, versioned prompts and experiments. It loses a fraction because observability is only as good as the instrumentation you actually write, and that part is still your job. AInexfinder Editor Score: 4.5/5.
Best for: Teams building agents with multi-step retrieval and tool use; Organisations whose compliance position requires self-hosting or a region
The visit link goes to langfuse.com, the official site. Paid placements on AInexfinder are always labelled. How we make money
Debugging a language-model application is unlike debugging anything else, and the reason is that the failure is usually not an error.
The request succeeded, the response came back, the status code was 200, and the answer was wrong. Nothing in a conventional monitoring stack notices that, because nothing in a conventional monitoring stack reads the content.
Langfuse exists for that gap, and its most consequential decision is not technical. Every product feature is MIT licensed, which changes who can adopt it and what happens if the company's plans and yours diverge.
Langfuse states that all product features are MIT licensed and that you can fork, modify and contribute. That sentence is doing a great deal of work, and it is worth unpacking against how this category normally operates.
The standard arrangement is open core: a permissively licensed base with the features you actually need — SSO, audit logs, retention controls, sometimes the evaluation tooling — held behind a commercial licence. The open version exists to get you in, and the interesting part is not open at all.
MIT across the product means the escape hatch is real rather than theoretical. If the pricing changes, the roadmap moves away from you, or the company is acquired by someone whose plans you dislike, you can run what you already have indefinitely and modify it.
That matters more for observability than for most software, because observability is where your history lives. Migrating a year of traces, evaluations and prompt versions to a different platform is not a weekend, and a vendor knows it — which is precisely why lock-in in this category is so valuable to them and so expensive to you.
The honest counterweight is that a licence is not a support contract. Running Langfuse yourself means you own the upgrades, the storage growth and the 3am page, and for most teams the managed cloud is the correct choice regardless. The licence is insurance rather than a plan.
The alternative shape is a gateway. Helicone is also open source and sits in the request path instead, which is a different answer to the same worry about who holds your history.
MIT across the whole product means the escape hatch is real rather than theoretical. It is insurance, not a deployment plan.
Langfuse's observability captures hierarchical traces covering LLM calls, tool invocations and retrieval steps, and the word hierarchical is the important one.
A flat log tells you a completion happened, what went in and what came out. That is enough for a single-call application and completely insufficient for an agent, because an agent's answer is the product of a sequence: retrieve, reason, call a tool, read the result, reason again, answer.
When the final answer is wrong, the question is which step went wrong — and a flat log cannot tell you, because it does not record that the steps were related. A trace tree does, and that is the difference between debugging and guessing.
The most common finding, once teams can actually see this, is that the model was fine and the retrieval was not. The prompt asked a reasonable question of documents that did not contain the answer, and the model did what models do with insufficient context.
That single insight changes where the fix goes. Without traces, teams spend weeks tuning prompts to fix a retrieval problem, which is an expensive way to make no progress.
Langfuse offers LLM-as-a-judge, heuristic functions and human annotation, and using all three deliberately is better than picking one.
Heuristics are cheap, fast and honest about their limits. Does the output parse as JSON, contain the required field, stay under the length limit, avoid a forbidden term? These catch a surprising proportion of real failures and never disagree with themselves.
LLM-as-a-judge scales to the questions heuristics cannot express — is this answer relevant, is it grounded in the retrieved context, is the tone right. It is genuinely useful and it inherits every weakness of the model doing the judging, including a well-documented preference for longer, more confident answers over shorter correct ones.
Human annotation is the only ground truth, and it is expensive, which is why it should be spent where it settles disagreements rather than sprayed across everything. The right use is calibration: annotate a sample, check whether your judge agrees with your humans, and only then trust the judge on volume.
That calibration step is the one teams skip, and skipping it means your evaluation numbers measure the judge's preferences rather than your users' experience. Langfuse's human review workflows exist precisely so that step is possible.
This is also where framework-tied tooling such as LangSmith and evaluation-led platforms like Braintrust weight things differently, and the right choice depends on whether evaluation or tracing is your bottleneck.
Langfuse offers prompt management with version control and one-click deployment, plus a playground that runs prompts against production inputs.
The problem it solves is unglamorous and universal. Prompts start in code, then someone needs to change one without a deploy, so they move to a config file, then to a database, and within a quarter nobody knows which version is live or who changed it last.
Versioning them properly makes regressions attributable. When quality drops on Tuesday, the useful question is what changed, and a system that can answer that in seconds is worth more than one that requires archaeology.
The playground running against production inputs is the detail that separates this from a text editor. Testing a prompt on examples you invented tells you it works on examples you invented; testing on the requests that actually failed tells you something.
Experiments close the loop by letting you define test cases and compare results across versions, which is what turns prompt changes from craft into something with evidence behind it.
None of this is visible to conventional monitoring. Sentry Seer will tell you the request threw; it has no view on a prompt change that quietly made every answer worse.
The failure mode with any observability platform is not that it does not work — it is that the traces are too thin to answer the question you eventually ask.
Langfuse offers native Python and TypeScript SDKs and states 100+ integrations, including LangChain, the Vercel AI SDK, LiteLLM, Pydantic AI, CrewAI and OpenAI. An integration gets you started; it does not decide what you record.
Hierarchical tracing across model calls, tool invocations and retrieval steps
Evaluation via LLM-as-a-judge, heuristic functions and human review
Prompt management with version control and one-click deployment
Playground for testing prompts against real production inputs
Experiments comparing results across prompt and model versions
Collaborative human annotation workflows
Cost and latency dashboards with alerting
Self-hosting via Docker Compose, Kubernetes or Terraform on three clouds
These tools all watch model calls. They differ on where they sit, what they own, and whether you can run them yourself.
| Tool | Position | Licence and hosting | Best for |
|---|---|---|---|
| Langfuse | SDK-instrumented tracing, evals and prompts | MIT across all features; self-host or managed cloud | Teams that need the option to run it themselves |
| Helicone | Gateway in the request path | Open source, self-host or cloud | Seeing everything without instrumenting each call |
| LangSmith | Tracing and evals tied closely to LangChain | Commercial | Teams already committed to LangChain |
| Braintrust | Evaluation-led with tracing around it | Commercial | Making evaluation the centre of the workflow |
| Sentry Seer | Application error monitoring | Commercial | Failures that actually throw, rather than wrong answers |
| Product type | Open-source LLM engineering and observability platform |
|---|---|
| Licence | MIT across all product features |
| Observability | Hierarchical traces covering LLM calls, tool invocations and retrieval steps |
| Evaluation | LLM-as-a-judge, heuristic functions and human review |
| Prompt management | Version control with one-click deployments |
| Playground | Test prompts against production inputs |
| Experiments | Defined test cases with cross-version comparison |
| Human annotation | Collaborative review workflows |
| Monitoring | Cost and latency dashboards with alerts |
| SDKs | Native Python and TypeScript |
| Integrations | 100+ stated, including LangChain, Vercel AI SDK, LiteLLM, Pydantic AI, CrewAI and OpenAI |
| Model providers | OpenAI, Anthropic, Amazon Bedrock, Google Gemini and others |
| Self-hosting | Docker Compose, Kubernetes via Helm, Terraform for AWS, GCP and Azure |
| Managed cloud | US and EU regions |
| Compliance | SOC 2 Type II, ISO 27001, GDPR, with a HIPAA-ready region |
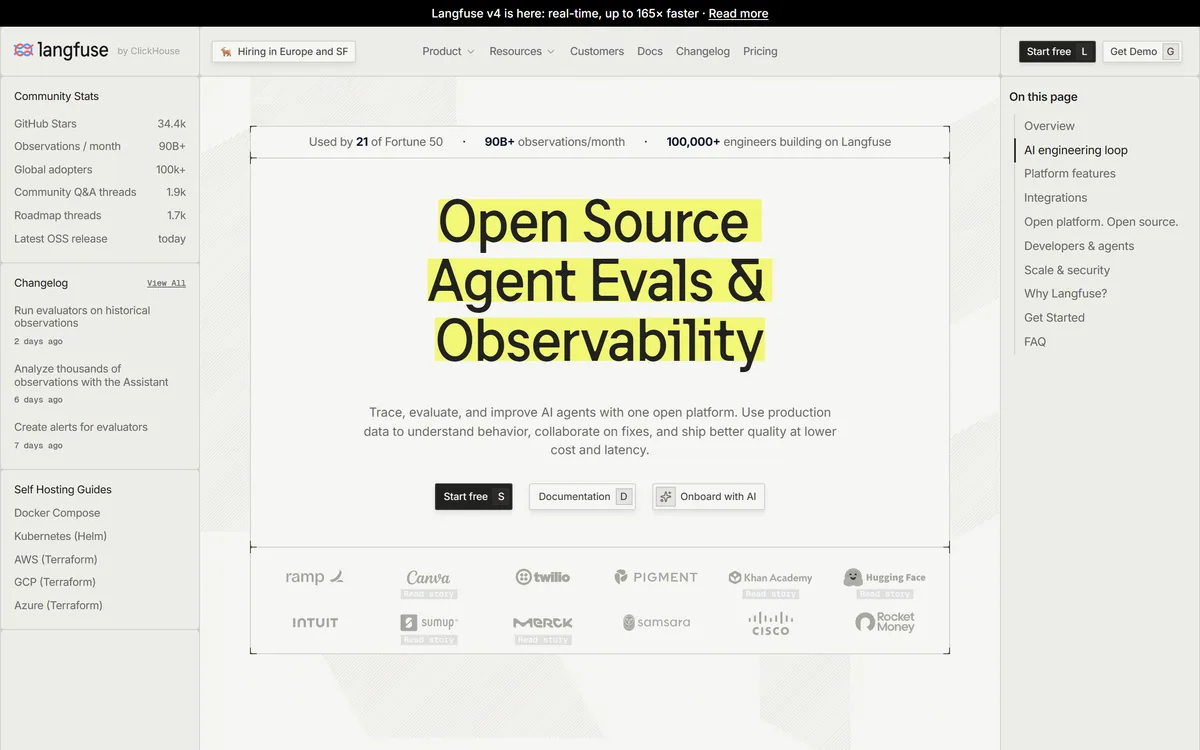
Last checked . Read from langfuse.com, with the screenshot above captured in the same session.
What we could not confirm: the operating company's legal name, headquarters or size; pricing and where the cloud tiers stop; whether any feature is cloud-only in practice despite the licence covering the product; storage and retention limits; the resource requirements of a self-hosted deployment; and independent verification of the certifications or the billions-of-events claim. We did not deploy Langfuse, so nothing here reflects tested performance.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Langfuse website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Langfuse earns an AInexfinder Editor Score of 4.5/5 (excellent). Best for: Teams building agents with multi-step retrieval and tool use; Organisations whose compliance position requires self-hosting or a region; Engineering groups that will genuinely write and maintain evaluations.
Visit LangfuseLog in to write a review.
No reviews yet. Be the first to share your experience with Langfuse.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Langfuse from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Momentic is an agentic end-to-end testing platform where AI writes tests as plain-English YAML, runs them across web, iOS and Android, and self-heals them when the UI changes, with an autonomous bug-bashing agent, an MCP server and CI integration.
Helicone is open-source LLM observability and an AI gateway. It logs and analyses requests across OpenAI, Anthropic, Gemini, Mistral, Groq, Together and OpenRouter, with sessions, user-level tracking, a query language, prompt management, datasets, a playground, rate limits and alerts.
Functionize is an AI-native test automation platform for enterprise web applications. Its Studio product uses autonomous agents to create and run end-to-end UI tests, with self-healing element resolution built on custom models rather than brittle selectors, across Salesforce, ServiceNow, Workday, SAP and bespoke apps.
Bug0 is managed AI QA: a forward-deployed engineer builds end-to-end tests on Bug0's engine, covering critical flows in seven days. Tests heal themselves when the UI changes, and every failure is verified before it reaches you. It also publishes Passmark and a substantial testing blog.

Cursor is an AI-first code editor and agent platform from Anysphere — now a SpaceX subsidiary — that plans, writes, tests, and reviews code across your repository from the desktop editor, a CLI, the web, and Slack.

GitHub Copilot is an AI coding assistant that spans completion, chat, agent mode, automated code review, and a cloud agent that opens pull requests, working across VS Code, Visual Studio, JetBrains, Xcode, Neovim, Eclipse, the CLI, and github.com.
Related Pages