
Zapier's AI layer adds agents and MCP tool access on top of its automation platform, connecting more than 9,000 apps with governed access so teams can mix AI decisions with deterministic rules under central oversight.
Productivity & Automation Review

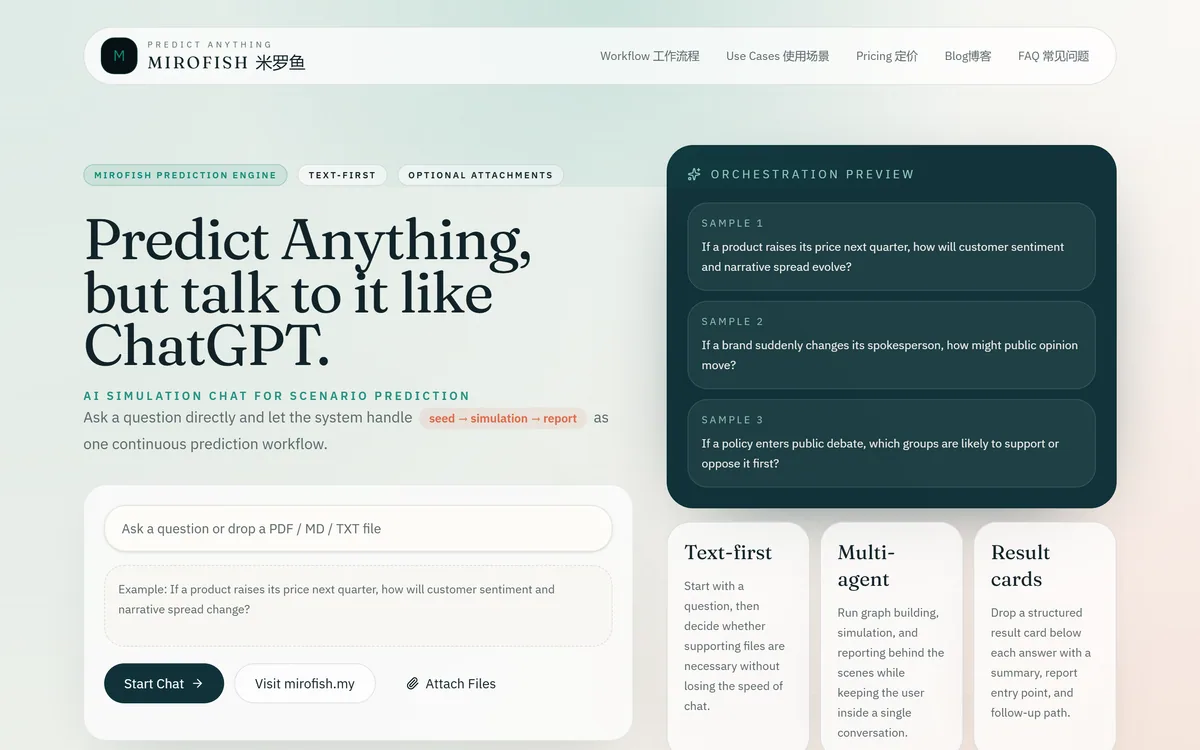
MiroFish is a multi-agent simulation platform for scenario prediction. You ask a plain-language question, attach supporting files, and it returns a structured report covering likely reactions, narrative paths, risk signals and follow-up questions.
Good
mirofish has an AInexfinder Editor Score of 3.7/5.
Best for: Strategy teams pressure-testing a decision that cannot be piloted; Product managers weighing a pricing change before committing
The visit link goes to mirofish.homes, the official site. Paid placements on AInexfinder are always labelled. How we make money
Every organisation has a version of the same meeting. Someone proposes a change — new pricing, a policy, a public statement — and the room tries to imagine how people will react. It is guesswork performed by five people who share assumptions, and its main weakness is that nobody in the room thinks like the people who will be angry.
MiroFish attacks that with multi-agent simulation. You describe the scenario in plain language, attach supporting material, and several AI agents work through likely reactions from different positions, producing a structured prediction report.
This review covers what the five-stage workflow actually does, why the report's structure is the interesting design decision, how much confidence the output deserves, and where it beats simply asking a chatbot.
MiroFish describes a workflow of Seed Material, Knowledge Graph, Agent Simulation, Prediction Report and Deep Interaction. The names are neat; the value is unevenly distributed across them.
Seed material is what you supply — the question, and any files that establish the actual situation. The platform's own guidance about using files as reality seeds is the right emphasis, because this is where a simulation is either grounded in your circumstances or floating free.
A question asked without documents produces a generic answer about how people generally react to price rises. The same question with your pricing page, your customer segments and last year's complaints attached produces something about your price rise. The knowledge graph stage structures that material into relationships the agents can reason over.
This is the part doing the differentiating work. Rather than one model producing one answer, multiple agents reason from different positions — which is a structural way of forcing the disagreement that a room of like-minded colleagues does not produce.
The honest caveat is that these agents share an underlying model, so their independence is real but bounded. They are not genuinely different minds; they are the same reasoning approached from different framings. That still surfaces more than a single pass, and it is less than the diversity of actual people.
The report arrives structured as executive summary, risk signals, narrative paths and follow-up questions, with deep interaction available to push on any part of it.
Being able to interrogate the report matters more than the report itself. A static document invites acceptance; a document you can argue with becomes a working session.
The four sections are a considered answer to how simulation output goes wrong.
Risk signals force the analysis to name what could go badly rather than producing a balanced summary that offends nobody. Balanced summaries are the standard failure of AI analysis and they are useless in a decision.
Narrative paths is the sharpest idea here. It acknowledges that reactions are not a distribution of independent opinions but stories that spread — and a modestly held objection that turns into a shareable narrative does far more damage than a widely held indifference.
Follow-up questions is the section experienced users will come to value most. The point of stress-testing a decision is rarely the answer; it is discovering the question nobody in the room asked.
And the executive summary exists because these reports have to survive being forwarded to someone who will read four sentences of it.
The useful output is not 'people will react badly'. It is the specific objection you had not thought of, phrased the way someone angry would phrase it.
Considerably less than the word 'prediction' invites, and this is the section that matters most.
Agent simulations produce plausible reactions, not probable ones. A language model reasoning about how a customer segment will respond is drawing on how such responses are generally written about, which is a real signal and not the same thing as evidence about your customers.
The failure mode is subtle and specific: the output is coherent, well structured and confidently expressed, and none of those properties correlate with accuracy. A report that reads like analysis gets treated like analysis.
Read it as a structured brainstorm with unusual discipline. It is genuinely better than a room of colleagues at surfacing angles nobody occupies, and genuinely worse than talking to five actual customers at telling you what will happen. Both statements are true simultaneously.
It also cannot know anything unusual about your situation that you did not put in the files. That is the whole argument for taking the seed material seriously.
The published use cases — campaign testing, pricing reactions, policy stress tests and market narrative — share a shape worth noticing. Each is a decision that is expensive to reverse, affects people who are not in the room, and normally gets made on intuition.
That is the sweet spot. A campaign can be tested cheaply with real audiences; a pricing change cannot be tested at all without making it, and a policy announcement gets exactly one launch.
The right sequence is to simulate first and then verify. Use MiroFish to generate the objections, then take the two or three most serious to actual customers or affected staff. That way the simulation is doing what it is good at — finding the question — while people supply the answer.
Using it the other way round, as the final check before shipping, is where organisations get into trouble.
The approach is easier to judge once these are clear.
Multi-agent simulation of audience reactions to a scenario
Plain-language question input with attached supporting files
Knowledge graph construction from supplied material
Structured prediction report with executive summary and risk signals
Narrative path analysis of how reactions might spread
Generated follow-up questions to pursue with real people
Deep interaction for interrogating the report after generation
Playbooks for prompt writing and file-based grounding
Scenario templates for campaigns, pricing, policy and market narrative
Simulation, synthetic research and real research answer overlapping questions with very different evidential weight.
| Tool | What it produces | Grounded in | Evidential weight |
|---|---|---|---|
| MiroFish | Structured prediction report with risks and narrative paths | Your uploaded documents plus model reasoning | Structured brainstorm, not evidence |
| neuroflash | Ranked reactions from simulated respondents | Over a million real survey profiles | Directional, anchored in survey data |
| Outset | AI-moderated interviews and analysis | Real participants | Genuine research evidence |
| Brandwatch | What audiences already said publicly | Observed real-world signal | Strong, but retrospective |
| Klue | Competitive intelligence and positioning | Market and competitor activity | Contextual rather than predictive |
| Category | Multi-agent AI simulation for scenario prediction |
|---|---|
| Workflow stages | Seed Material, Knowledge Graph, Agent Simulation, Prediction Report, Deep Interaction |
| Inputs | A plain-language question, plus optional supporting files |
| Report sections | Executive Summary, Risk Signals, Narrative Paths, Follow-up Questions |
| Published use cases | Campaign Test, Pricing Reaction, Policy Stress Test, Market Narrative |
| Guidance provided | Playbooks on writing sharper prediction prompts and using files as reality seeds |
| Interaction | Deep interaction to interrogate the report after it is produced |
| Comparison framing | Positioned against a single chat answer and against manual research |
| Named audiences | Strategists, product managers, policy teams |
Simulated, survey-anchored, observed and directly asked — in ascending order of evidential weight.
Last checked . Read from mirofish.homes during this check, with the screenshot above captured at the same time.
Judgements about how much confidence agent simulation deserves reflect the state of the technique generally rather than measured performance of this platform. We have not tested output accuracy against real-world outcomes, and say so rather than implying otherwise.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official mirofish website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
mirofish earns an AInexfinder Editor Score of 3.7/5 (good). Best for: Strategy teams pressure-testing a decision that cannot be piloted; Product managers weighing a pricing change before committing; Policy and communications teams preparing an announcement with one launch.
Visit mirofishLog in to write a review.
No reviews yet. Be the first to share your experience with mirofish.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research mirofish from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Zapier's AI layer adds agents and MCP tool access on top of its automation platform, connecting more than 9,000 apps with governed access so teams can mix AI decisions with deterministic rules under central oversight.
Self-maintaining AI knowledge base for teams Category: Productivity & Automation.
AI data workspace with memory and agent teams Category: Productivity & Automation.
Enterprise AI assistant for work search and agents Category: Productivity & Automation.

Notion AI is the assistant built into Notion — writing and editing in docs, agents that run recurring work like triage and reporting, AI Meeting Notes, and Enterprise Search across connected tools such as Slack, GitHub, Gmail, and Google Drive.
Gamma is a visual communication platform with an AI agent that turns an idea into presentations, documents or websites. It brainstorms an outline, designs a look from a prompt or inspiration, refines freeform, and imports and exports PowerPoint and PDF with 25+ connectors.
Related Pages