Developer-first AI security from code to runtime Category: Coding & Development.
Coding & Development Review
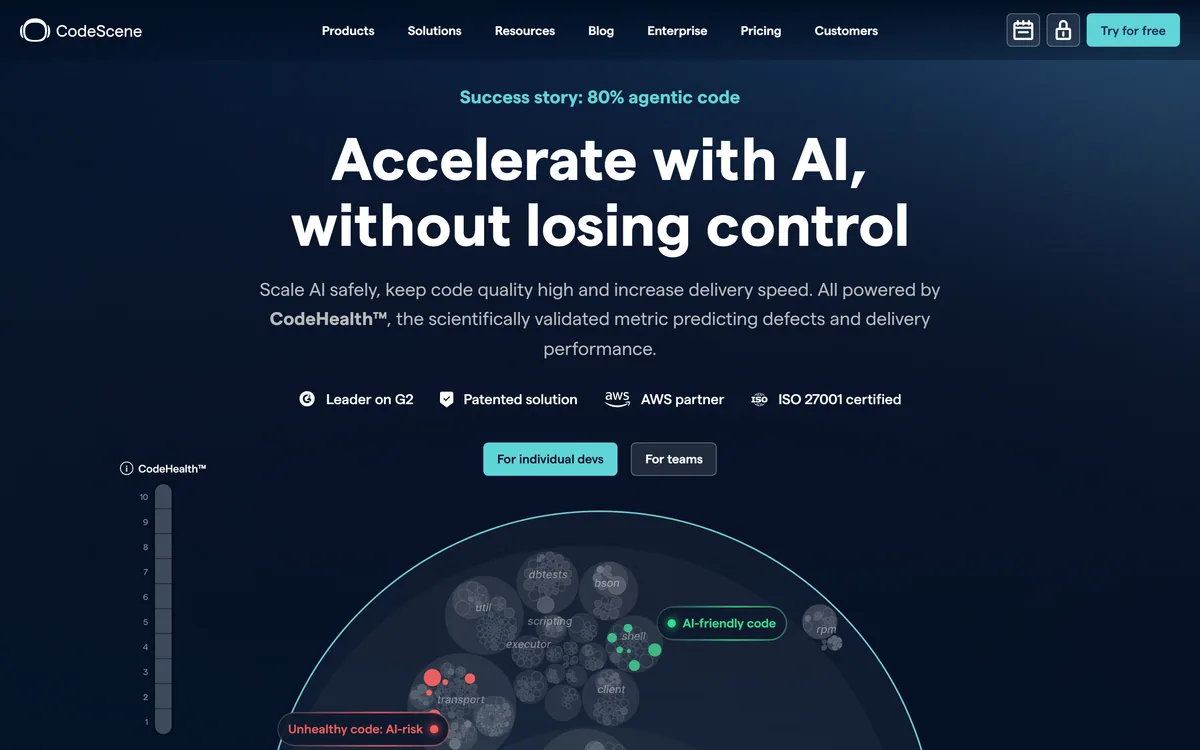
CodeScene measures code with CodeHealth, a validated metric predicting defects and delivery performance. It states the average enterprise codebase scores 5.15 out of 10 while AI needs 9.5 to work reliably, and offers an MCP server, automated reviews and IDE feedback. Operated by CodeScene AB.
Very good
CodeScene has done something most developer tools avoid: it committed to a number. Code Health is a single score, published methodology, validated against defect and delivery outcomes, and it produces uncomfortable answers — the stated average enterprise codebase sits at 5.15 out of 10 while the company argues AI agents need 9.5 to work reliably. That gap reframes technical debt from an engineering complaint into an AI-readiness problem, which is the most useful thing anyone has said about legacy code in two years. The risk with any single metric is that teams optimise the number instead of the code, and no tool can prevent that. AInexfinder Editor Score: 4.2/5.
Best for: Engineering leaders who need debt expressed as a business argument; Teams rolling out AI coding agents across a large legacy codebase
The visit link goes to codescene.com, the official site. Paid placements on AInexfinder are always labelled. How we make money
Technical debt has always been a hard argument to win. Everyone agrees it exists, nobody can size it, and the request to spend a quarter on refactoring loses every time to a feature with a date attached.
The reason is that debt was never measured in a way a non-engineer could act on. Complaints do not compete with roadmaps.
CodeScene's approach is to produce a number instead — a Code Health score with a published basis — and then to attach that number to something with immediate commercial weight: whether AI agents can work in your codebase at all.
CodeScene describes CodeHealth as a scientifically validated metric predicting defects and delivery performance, expressed on a 1–10 scale. The site states the average enterprise codebase scores 5.15, and that AI needs 9.5 to work reliably.
The value of a single score is not precision — it is that it can be discussed by people who do not read the code. A team saying this module is a mess loses to a roadmap; a team saying this module scores 3 and the ones above 8 ship twice as fast has an argument.
The gap between 5.15 and 9.5 is doing the heavy lifting in the marketing, and it is worth reading carefully. It says that the typical enterprise codebase is not merely below ideal but far below the threshold at which the company claims AI assistance becomes dependable.
That is a strong claim and it should be treated as the vendor's position rather than settled fact. The direction is well supported by ordinary experience — agents do worse in tangled code — but the specific threshold is a number CodeScene has an interest in.
What makes it useful anyway is that it is falsifiable in your own repository. Score your codebase, look at where your agents already fail, and see whether the two correlate. That is a test you can run in an afternoon.
A team saying this module is a mess loses to a roadmap. A team saying this module scores 3 and the ones above 8 ship twice as fast has an argument.
CodeScene states that AI agents introduce at least 60% more defects and burn up to 50% more tokens in unhealthy code.
The mechanism is not mysterious. An agent works from context, and unhealthy code is code where the context is expensive — long functions, deep nesting, duplicated logic, unclear names, behaviour spread across files with no obvious relationship.
Tokens are consumed reading all of that, which explains the cost figure directly. The defect figure follows from the same cause: an agent that cannot see the whole picture makes a locally reasonable change that breaks something it never read.
Human developers hit exactly the same wall, which is why this is not really an AI story. It is the old argument about maintainability with a new and more expensive consequence attached.
The practical implication is uncomfortable and correct: pointing agents at your worst code is the least effective place to use them, even though it is where the temptation is strongest. Review tooling such as cubic and DeepSource catches what comes out, but the cheaper intervention is improving what goes in.
CodeScene's framing is that technical debt matters where it impacts delivery, and its stated workflow is to prioritise and quantify debt, enforce standards with automated reviews, then prevent debt at the source with real-time IDE feedback.
Prioritisation is the part that separates this from a linter. Not all bad code costs anything — a badly written module nobody touches is a museum piece, not a liability, and refactoring it is wasted effort.
What costs money is bad code that changes often. Combining health with change frequency identifies the small number of files where debt is actually being paid for, and that list is usually far shorter than the list of files that are simply ugly.
The three-step structure then follows sensibly: find the expensive debt, stop new debt entering through automated review, and shift the feedback into the IDE so problems are caught before they are ever committed.
Real-time IDE feedback is the highest-leverage of the three, for the obvious reason that the cheapest moment to fix a design problem is while the person who created it still has it in their head.
CodeScene offers a CodeHealth MCP server, described as creating a self-correcting loop inside your AI coding assistant to safeguard AI-generated code and make legacy code AI-ready.
This is the most interesting product decision on the page. Rather than reporting on code after it exists, the metric becomes available to the agent while it is writing.
The loop matters because agents respond well to explicit criteria. An agent told only to make the tests pass will do that and nothing else; an agent that can query a health score has a second objective it can actually measure itself against.
It also changes who the tool is for. A dashboard is for engineering managers; an MCP server is for the developer and the agent, at the moment of writing, which is a much shorter path from measurement to behaviour.
The caution is the general one about optimising to a metric. An agent that can see a score will move the score, and moving a score is not identical to improving code — splitting a long function into four badly named short ones improves several standard measures and helps nobody.
Every metric buys clarity by discarding information, and it is worth being explicit about what Code Health leaves out.
Architecture is the biggest omission. A codebase can be composed entirely of clean, well-named, low-complexity functions and still be a disaster because the boundaries between components are wrong, and no file-level measure sees that.
Test quality is the second. Coverage is measurable and quality is not — a suite that asserts nothing meaningful looks identical to a good one from outside, and it is the difference between change being safe and merely appearing safe.
Domain correctness is the third and largest. Code can be immaculate and compute the wrong thing, and no static measure has an opinion about whether your business logic matches the business.
None of this argues against the metric. It argues for treating it as one input among several — the same way observability data from tools like Langfuse tells you what your system did without telling you whether it should have.
The wrong way to adopt a code quality metric is to score everything, publish a league table, and watch teams start gaming it by Friday.
This sequence establishes the baseline privately and moves to enforcement only once people trust what the number means.
The terms CodeScene uses, and what each one actually measures.
| Operating company | CodeScene AB |
|---|---|
| Core metric | CodeHealth, on a 1–10 scale |
| Stated basis | Scientifically validated for predicting defects and delivery performance |
| Average enterprise score | 5.15 out of 10, per the site |
| Threshold for AI | 9.5, per the site |
| AI in unhealthy code | At least 60% more defects and up to 50% more tokens, per the site |
| Developer surface | CodeHealth MCP server inside AI coding assistants |
| Team surface | An AI Framework covering assessment, safeguarding, uplift and ROI tracking |
| Workflow | Prioritise debt, enforce automated reviews, prevent debt in the IDE |
| Credentials | ISO 27001 certified, AWS partner, patented solution, G2 leader, per the site |
| Copyright | 2026 © CodeScene AB |
CodeHealth scoring on a 1–10 scale
Technical debt prioritised by delivery impact
Automated CodeHealth reviews as a quality gate
Real-time health feedback in the IDE
A CodeHealth MCP server for AI coding assistants
An AI Framework for assessing where AI is safe to apply
Trend tracking and ROI measurement
Refactoring target identification
Quality tools differ by whether they measure the codebase, review the change, or find the bug.
| Tool | What it measures | Where it runs | Best for |
|---|---|---|---|
| CodeScene | Code health as a validated score | Repository, CI, IDE and MCP | Making technical debt arguable in a roadmap meeting |
| DeepSource | Issues from rules plus AI review | Pull requests | Catching defects in the change itself |
| cubic | Review comments against your standards | GitHub and the IDE | Team conventions enforced conversationally |
| Codacy | Static analysis and coverage | CI and pull requests | Broad automated quality checks |
| Bug0 | Actual defects in running software | Against the application | Finding what analysis cannot see |
Last checked . Read from codescene.com in a browser session on the date above, with the screenshot captured alongside.
What we could not confirm: the published research behind the validation claim, which the site references but which we did not read at source; how 5.15 and 9.5 were derived and across what sample; the methodology behind the 60% defect and 50% token figures; pricing and plan structure; which languages are supported and how well; and the referenced Gartner report and SonarQube comparison, which we saw named in navigation but did not open. We did not run CodeScene against a codebase, so no figure here is independently tested.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official CodeScene website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
CodeScene earns an AInexfinder Editor Score of 4.2/5 (very good). Best for: Engineering leaders who need debt expressed as a business argument; Teams rolling out AI coding agents across a large legacy codebase; Organisations deciding where to spend a limited remediation budget.
Visit CodeSceneLog in to write a review.
No reviews yet. Be the first to share your experience with CodeScene.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research CodeScene from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Developer-first AI security from code to runtime Category: Coding & Development.
Snyk Code is a static application security testing tool built for developers, using DeepCode AI to find vulnerabilities in the IDE in real time and Snyk Agent Fix to propose pre-validated fixes, including coverage for AI-generated code.
AI-assisted code, supply chain and secrets security Category: Coding & Development.
Sourcery is an AI code-review tool that reviews every pull request in minutes, catching bugs, edge cases and security issues with one-click fixes, plus codebase security scanning, with a strong stance on keeping your code private.
cubic reviews pull requests in GitHub and your IDE, enforces rules written in plain English, and learns from senior engineers' PR comment history. It runs thousands of agents nightly to scan an entire codebase for bugs, pulls context from Linear, JIRA, Notion and Confluence, and is free for public repositories.
Codacy combines static analysis, SAST, SCA, secret scanning, IaC checks and test coverage in one platform, and has repositioned around AI-assisted engineering — detecting AI policy violations and unapproved model calls, with Codacy Guardrails embedding checks inside agentic workflows.
Related Pages