Developer-first AI security from code to runtime Category: Coding & Development.
Coding & Development Review
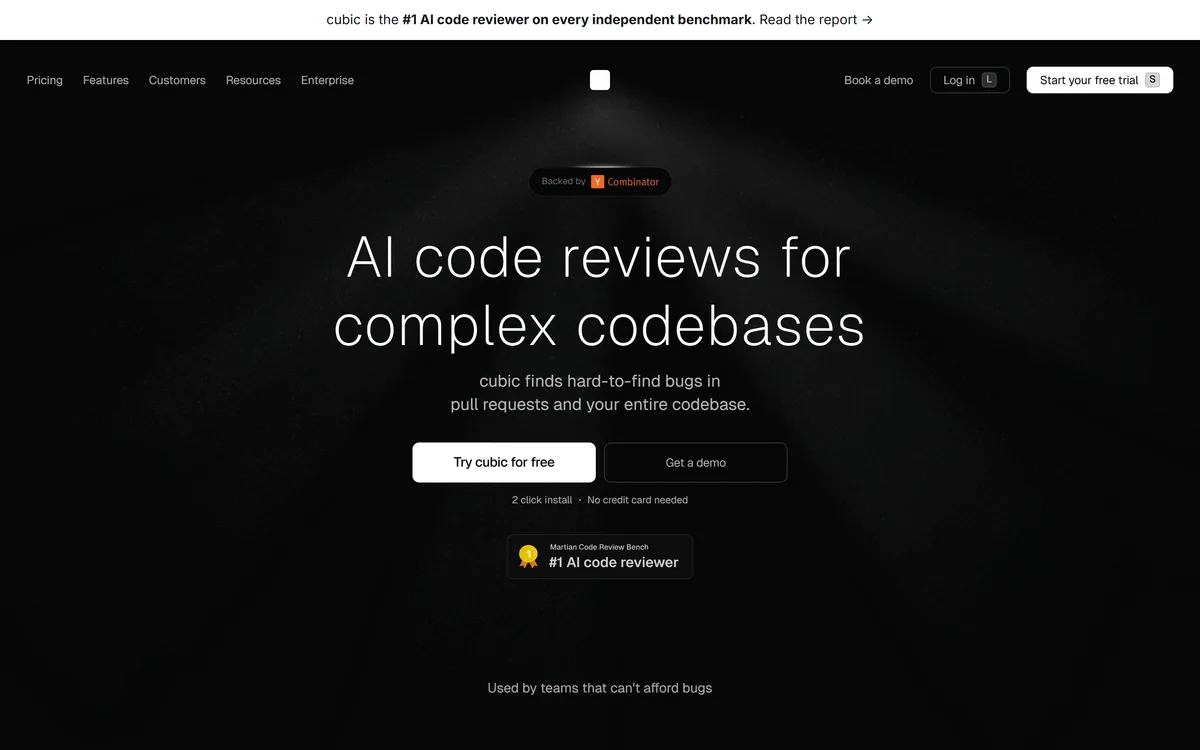
cubic reviews pull requests in GitHub and your IDE, enforces rules written in plain English, and learns from senior engineers' PR comment history. It runs thousands of agents nightly to scan an entire codebase for bugs, pulls context from Linear, JIRA, Notion and Confluence, and is free for public repositories.
Very good
AI code review is now a crowded category, and the interesting differences are no longer about finding bugs. cubic's two distinctive moves are both about fitting a specific team: rules written in plain English rather than configured, and onboarding by reading your senior engineers' past PR comments — which is a genuinely clever way to acquire conventions nobody ever wrote down. The nightly codebase scan is the more ambitious feature and the harder one to judge, since thousands of agents finding issues is only useful if the issues are real. Free for public repositories is the right instinct. AInexfinder Editor Score: 4.2/5.
Best for: Teams where senior engineers are the review bottleneck; Codebases whose conventions exist only as tacit knowledge
The visit link goes to cubic.dev, the official site. Paid placements on AInexfinder are always labelled. How we make money
Code review has two jobs. One is catching defects, which tools have been attempting for decades. The other is transmitting how this particular team writes code, which is entirely social and has never been automatable.
That second job is why review comments from a senior engineer are valuable and a linter's output is merely tolerated. The linter knows rules; the engineer knows why the rules exist here.
cubic's most interesting design decision aims squarely at that gap: it reads what your senior engineers have written in past reviews, and treats that as the specification.
cubic states that it enforces your team's standards written in plain English, identifies senior engineers and learns from their activity, and onboards by reading their PR comment history.
The plain-English part matters more than it sounds. Most team standards are not expressible as a linter rule — prefer early returns in handlers, do not add a cache without a way to invalidate it, keep database calls out of view code — and every attempt to encode them into configuration loses the nuance.
Writing them as sentences preserves the reasoning, which is what makes a rule apply correctly to a case the author did not anticipate. It also means the person who holds the standard can write it down without learning a rule syntax.
The comment-history onboarding is the cleverer half. Most conventions were never written anywhere; they exist as a decade of review comments, and any new hire learns them by having the same corrections applied to them personally.
Reading that history is a genuinely good idea. The risk is that it also inherits whatever was wrong or outdated in it — a preference somebody abandoned three years ago, a defensive pattern adopted for a system that no longer exists, or one strong personality's habits mistaken for team consensus.
Most conventions were never written anywhere. They exist as a decade of review comments, and every new hire learns them by having the same corrections applied to them personally.
The mechanism raises a question worth asking before you turn it on: who does the system consider senior?
If seniority is inferred from activity — comment volume, merge counts, tenure — it may identify the most prolific commenter rather than the best reviewer, and those are frequently different people.
It also encodes a moment in time. A team improving its practices will have a comment history that is worse than its current standard, and a tool trained on that history will pull work backwards towards the average of the past.
The mitigation is to treat learned conventions as a draft that gets reviewed. Read what the tool inferred, delete the rules nobody believes any more, and promote the good ones into the plain-English set where they are explicit and editable.
Done that way, the feature is genuinely valuable: it surfaces the tacit rules of a codebase, which is useful even if you never let the tool enforce them. Structural quality tools such as CodeScene measure whether the code is healthy; this measures what the team believes.
cubic describes an early-access capability that runs thousands of agents each night to find and fix bugs across a whole codebase, with automatic triage, ticket creation and one-click fixes.
The premise is stated bluntly on the site: your codebase is full of bugs. That is true of every codebase, and it is also why the feature is harder than it sounds.
The difficulty is not finding candidate issues — any sufficiently thorough scan finds thousands. The difficulty is that a finding is only useful if it is real, reachable, and worth someone's morning.
Automated triage and ticket creation therefore cut both ways. Routed well, they put the right issue in front of the right owner; routed badly, they generate a backlog of low-value tickets that trains everyone to ignore the tool's tickets specifically.
The honest way to evaluate this is on precision rather than volume. Run a scan, take the first twenty findings, and count how many you would actually fix. That ratio decides whether the feature is an asset or a source of noise — the same test that applies to any static analysis platform, including DeepSource and Codacy.
Writing standards as sentences instead of configuration is the feature most likely to change how a team actually works, and it has a failure mode worth anticipating.
The benefit is accessibility. A tech lead who would never write a custom lint rule will write down never call the payment API from inside a transaction, and that sentence is both a machine instruction and documentation for humans.
The failure mode is ambiguity. Natural language rules are interpreted rather than executed, so two changes that look similar to a person may be judged differently, and an occasionally-wrong rule erodes trust faster than a missing one.
This makes the review of the rules themselves important. A rule that produces false positives should be rewritten more precisely or removed, and somebody needs to own that maintenance or the rule set decays.
Started narrowly it works well: five rules everybody agrees on, tightened over a month, is a far better foundation than thirty aspirational ones that generate arguments in pull requests.
The failure mode of automated review is not wrong comments — it is too many correct but unimportant ones.
A reviewer facing forty machine comments will not read forty machine comments. They will scan for anything alarming, approve, and from that point the tool has made review worse rather than better, because it has trained people to skim.
Nit-picking is the specific danger, and it is the thing teams most hope automation will remove. cubic's own customer quote claims nit-picks are gone, which is the right thing to promise and the thing to verify in your own repository.
What automation genuinely cannot judge is whether a change is the right change. Whether this abstraction is worth its cost, whether this belongs in this service, whether the requirement itself makes sense — those are design conversations, and they are the part of review that is worth a person's time.
The best outcome is therefore a division of labour rather than a replacement: machines take the mechanical layer, humans get their attention back for the design layer. Any tool that produces the opposite result is failing regardless of how many defects it finds.
Automated review tools fail in a predictable way: enabled fully on day one, generating hundreds of comments, quietly ignored by week three.
This sequence builds trust first and widens scope only once the comments are being read.
Inline AI review comments on pull requests
Review inside the IDE as well as GitHub
Standards written as plain English rules
Convention learning from senior engineers' comment history
AI-generated pull request descriptions
One-click fixes for simple issues
Nightly whole-codebase scanning with automatic triage
Context from Linear, JIRA, Notion and Confluence
Review and quality tools differ by what they inspect and when they run.
| Tool | What it inspects | When it runs | Best for |
|---|---|---|---|
| cubic | Pull requests, plus whole-codebase scans | On PR, in the IDE, and overnight | Teams whose standards live in review comments |
| DeepSource | Changes, via rules plus AI agents | On pull requests | Low false positives across security and quality |
| CodeScene | Codebase health as a score | Continuously | Arguing for refactoring with a number |
| Codacy | Static analysis and coverage | In CI | Broad automated quality gates |
| Bug0 | Running software | Against the application | Defects analysis cannot see |
| Product type | AI code review |
|---|---|
| Surfaces | GitHub pull requests and your IDE |
| Rules | Written in plain English |
| Onboarding | Learns from senior developers' PR comment history |
| Context sources | Linear, JIRA, Notion, Confluence and others |
| Codebase scan | Thousands of agents run nightly, in early access |
| Triage | Automatic owner notification and ticket creation |
| Fixes | One-click for simple issues, Fix with cubic for harder ones |
| Summaries | AI-generated PR descriptions highlighting impact |
| Languages | Language-agnostic, including JavaScript, TypeScript, Python, Go, Ruby, Java and C# |
| Open source | Free for public repositories |
| Copyright | © 2026 cubic |
Last checked . Read from cubic.dev in a browser session on the date above, with the screenshot captured alongside.
What we could not confirm: pricing for private repositories and how reviewed-line usage is counted; the claim of being the #1 AI code reviewer on every independent benchmark, since we did not open the linked report; how seniority is determined when learning from comment history; what precision the nightly scan achieves; where code is processed and whether any of it is retained; and which models perform the review. We did not connect a repository, so no claim here is independently tested.
Neighbouring products across review, quality and knowledge.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official cubic website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
cubic earns an AInexfinder Editor Score of 4.2/5 (very good). Best for: Teams where senior engineers are the review bottleneck; Codebases whose conventions exist only as tacit knowledge; Organisations onboarding developers regularly.
Visit cubicLog in to write a review.
No reviews yet. Be the first to share your experience with cubic.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research cubic from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Developer-first AI security from code to runtime Category: Coding & Development.
Snyk Code is a static application security testing tool built for developers, using DeepCode AI to find vulnerabilities in the IDE in real time and Snyk Agent Fix to propose pre-validated fixes, including coverage for AI-generated code.
AI-assisted code, supply chain and secrets security Category: Coding & Development.
Sourcery is an AI code-review tool that reviews every pull request in minutes, catching bugs, edge cases and security issues with one-click fixes, plus codebase security scanning, with a strong stance on keeping your code private.
CodeScene measures code with CodeHealth, a validated metric predicting defects and delivery performance. It states the average enterprise codebase scores 5.15 out of 10 while AI needs 9.5 to work reliably, and offers an MCP server, automated reviews and IDE feedback. Operated by CodeScene AB.
Codacy combines static analysis, SAST, SCA, secret scanning, IaC checks and test coverage in one platform, and has repositioned around AI-assisted engineering — detecting AI policy violations and unapproved model calls, with Codacy Guardrails embedding checks inside agentic workflows.
Related Pages