Stainless generates idiomatic client libraries in seven languages, documentation that tracks the API, and MCP servers, all derived from an OpenAPI specification. Its homepage announces that the company is joining Anthropic.
Coding & Development Review
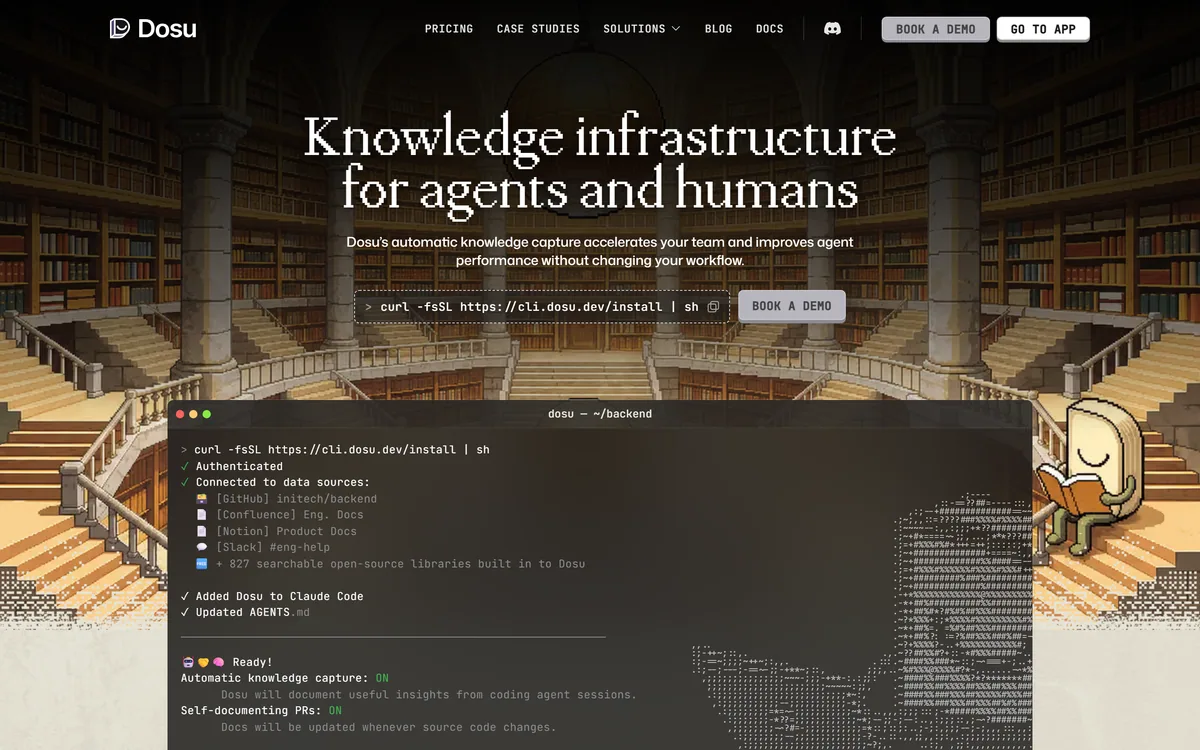
Dosu captures knowledge automatically from coding agent sessions, keeps documentation updated when source code changes, and connects GitHub, Confluence, Notion and Slack into one source of context. It states 50% fewer tokens burned, 2x faster agent performance and 200k+ engineers using it.
Very good
Dosu is built on an observation that has become obviously true in the last year: coding agents are only as good as the context they can find, and most codebases have none worth finding. Rather than asking teams to write documentation they were never going to write, it captures knowledge from agent sessions as a by-product and updates docs when source changes. That inverts the economics of documentation entirely. The published numbers — 50% fewer tokens, 2x faster agent performance — are vendor figures, but the mechanism behind them is sound and the problem is real. AInexfinder Editor Score: 4.3/5.
Best for: Teams where coding agents do meaningful daily work; Codebases with thin or stale documentation and high onboarding cost
The visit link goes to dosu.dev, the official site. Paid placements on AInexfinder are always labelled. How we make money
Documentation has always lost to features, and the reason is not laziness. Writing it is work that benefits somebody else later, which is the least motivating shape a task can have.
Coding agents have changed the arithmetic. An agent with good context is fast and accurate; an agent without it reads half the repository to answer a simple question, gets it wrong, and costs you tokens doing so.
Dosu's proposition is that documentation should be captured rather than written — extracted from the work as it happens, and updated when the code it describes changes.
Dosu positions itself as knowledge infrastructure for agents and humans, stating that automatic knowledge capture accelerates your team and improves agent performance without changing your workflow.
The mechanism is worth spelling out because it explains the token figures. An agent answering a question must first find the relevant context, and if there is no documentation it does that by reading code.
Reading code is expensive in exactly two ways. It consumes tokens proportional to how much has to be read, and it produces an inferred understanding that may be wrong — because code shows what happens, not why, and the why is where the decisions live.
Good documentation short-circuits both. The agent reads a paragraph instead of four files, and the paragraph contains the reasoning that the code cannot express.
This reframes documentation from a courtesy to infrastructure. It was always valuable and always deferrable; with agents in the loop it has a measurable per-query cost, which is the first time the argument has had a number attached to it — much as CodeScene attached a number to technical debt.
Code shows what happens, not why. The why is where the decisions live, and it is exactly what an agent cannot infer by reading more files.
Dosu's terminal output describes automatic knowledge capture as on, documenting useful insights from coding agent sessions.
This is the cleverest idea in the product. When an agent works through a problem, it necessarily reconstructs an understanding of the relevant part of the system — and that understanding is normally discarded when the session ends.
Capturing it converts a by-product into an asset. The expensive part of documentation, which is working out how something actually functions, has already been paid for; writing it down is the cheap part that never happens.
It also aligns the incentive correctly. Nobody has to remember to document anything, and the documentation that gets created is about the parts of the system people are actually working on, which is where it is most needed.
The caveat is that an agent's understanding can be wrong, and captured wrongness is worse than absence because it will be trusted by the next agent and the next person. Any system doing this needs a review path, and that is the thing to check before switching it on across a repository.
The second capability is docs updating whenever source code changes, described on the site as self-documenting PRs.
This attacks documentation's real failure, which was never that it did not exist. It was that it existed, described the system as of two years ago, and was therefore worse than nothing because people believed it.
Stale documentation is genuinely dangerous with agents in the loop. A human reading an out-of-date page usually notices the mismatch against the code; an agent may confidently act on the description instead.
Tying updates to the change that caused them is the structurally correct fix, because it removes the gap where documentation drifts. The moment the code changes is the only moment anyone knows what changed and why.
The practical question to ask is what happens when the update is wrong. A documentation change generated alongside a code change should be reviewable in the same pull request, which is where products like GitBook and cubic approach the same review surface from different directions.
Dosu makes a pointed argument about replacing a tangle of MCP servers with a single consistent source of knowledge, and lists GitHub, Confluence, Notion and Slack among its connections plus 827 built-in open-source libraries.
The problem it names is real and recent. Connecting an agent to five separate systems means five sets of credentials, five retrieval behaviours, five ways for something to fail, and no coherent notion of what the agent actually knows.
It also means duplication and contradiction. The same fact exists in a Notion page, a Slack thread and a README, in three versions of varying age, and the agent picks whichever it finds first.
A consolidation layer resolves that by deciding what is authoritative, which is a genuinely useful thing to have decided. The trade is that you have added a dependency between your agents and everything they know.
The 827 open-source libraries are the underrated part of the list. Agents routinely get third-party library usage wrong because their training data predates the current version, and a maintained index of library documentation addresses that specific and common failure.
Dosu publishes three figures: 50% fewer tokens burned by agents working with accurate documentation, 2x faster agent performance with Dosu-maintained context, and 200k+ engineers already using it.
The first two are vendor benchmarks with no stated methodology on the page, so treat them as directional. The direction, however, is well supported by ordinary reasoning: less reading means fewer tokens, and better context means less trial and error.
What makes them unusually testable is that both are things you can measure yourself. Token usage per task is already visible in your agent tooling, and so is time to a correct answer.
That puts this in a better position than most vendor claims, which rely on effects you cannot isolate. Run twenty representative tasks before and after and you have your own number, on your own codebase, which is the only one that matters.
The 200k+ engineers figure is the vaguest of the three, since it does not distinguish between people who installed it once and teams using it daily — a distinction every developer tool blurs in the same way.
The risk with automatic documentation is generating a large volume of plausible text about a system nobody has verified, which then becomes the authority.
This sequence starts where a human can check the output and expands only once the captured knowledge has proved accurate.
The vocabulary around agent context, and what each term actually means.
| Product type | Knowledge infrastructure for coding agents and humans |
|---|---|
| Positioning | Automatic knowledge capture that accelerates teams and improves agent performance |
| Install | A single CLI command, per the site |
| Data sources | GitHub, Confluence, Notion, Slack |
| Built-in index | 827 searchable open-source libraries |
| Agent integration | Adds itself to Claude Code and updates AGENTS.md, per the site |
| Capture | Documents insights from coding agent sessions automatically |
| Documentation | Updates whenever source code changes |
| Token claim | 50% fewer tokens burned by agents with accurate documentation |
| Speed claim | 2x faster coding agent performance with Dosu-maintained context |
| Scale claim | 200k+ engineers |
| Certification | SOC 2 Type II |
| Location | 1841 Market St, San Francisco, CA 94103 |
Automatic knowledge capture from coding agent sessions
Documentation updated when source code changes
A single CLI install
GitHub, Confluence, Notion and Slack connections
827 open-source libraries searchable out of the box
Automatic AGENTS.md maintenance
Integration with coding assistants including Claude Code
A consolidated alternative to multiple MCP servers
Developer tools split by whether they explain the code, review it, or measure it.
| Tool | What it produces | Who consumes it | Best for |
|---|---|---|---|
| Dosu | Documentation captured from work | Agents and humans | Codebases where agents lack context |
| GitBook | Documentation you write | Humans and, increasingly, agents | Published docs with editorial control |
| cubic | Review comments and conventions | Developers | Enforcing how a team writes code |
| CodeScene | A code health score | Engineering leaders | Deciding where debt costs most |
| Helicone | Observability for LLM calls | Engineers running AI features | Seeing what your agents actually did |
Last checked . Read from dosu.dev in a browser session on the date above, with the screenshot captured alongside.
What we could not confirm: the methodology behind the 50% token and 2x speed figures, which are presented without a stated basis; whether 200k+ engineers counts installs or active users; pricing, which routes to a separate page we did not read; the registered operating entity, which the footer does not name beyond the product; how source code and internal documents are processed and retained during indexing; and whether captured documentation is reviewable before it becomes authoritative. We did not install Dosu.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Dosu website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Dosu earns an AInexfinder Editor Score of 4.3/5 (very good). Best for: Teams where coding agents do meaningful daily work; Codebases with thin or stale documentation and high onboarding cost; Organisations running several MCP servers that have become unmanageable.
Visit DosuLog in to write a review.
No reviews yet. Be the first to share your experience with Dosu.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research Dosu from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Stainless generates idiomatic client libraries in seven languages, documentation that tracks the API, and MCP servers, all derived from an OpenAPI specification. Its homepage announces that the company is joining Anthropic.
liblab review on AInexfinder — subscription AI tool for Coding & Development. Features, pricing notes, and alternatives.
Theneo is an AI-powered API documentation and developer-portal platform where engineers, writers, PMs and AI agents co-edit API references, guides and changelogs in real time, with generation from any spec, MCP and llms.txt for agents, and private per-customer portals.
GitBook is a documentation platform that syncs with your repository for docs-as-code workflows, proactively flags content that no longer matches your product, answers user questions through an AI assistant, and connects to Claude, ChatGPT and Cursor through MCP so agents can read your docs directly.

Cursor is an AI-first code editor and agent platform from Anysphere — now a SpaceX subsidiary — that plans, writes, tests, and reviews code across your repository from the desktop editor, a CLI, the web, and Slack.

GitHub Copilot is an AI coding assistant that spans completion, chat, agent mode, automated code review, and a cloud agent that opens pull requests, working across VS Code, Visual Studio, JetBrains, Xcode, Neovim, Eclipse, the CLI, and github.com.
Related Pages