Mobile-first AI art and video generator with many styles Category: Image & Design.
Image & Design Review
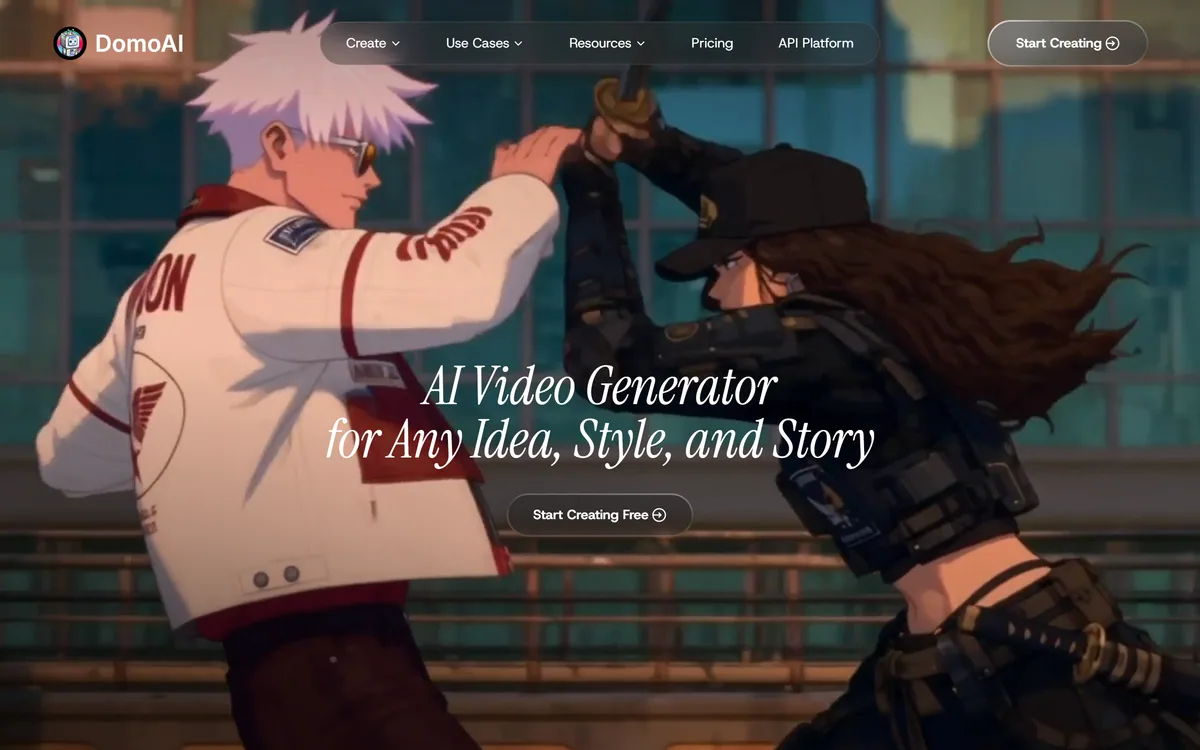
DomoAI is an AI video platform with seven generation modes including Omni Reference, Video to Video, Image to Video, Talking Avatar, Character to Video, Text to Video and Frames to Video. It names its models — DomoAI 2.5, Seedance 2.5, MiniMax H3, GPT Image 2 and Nano Banana — and offers an API. Operated by DOMOAI PTE. LTD.
Very good
DomoAI's structure is a genuine advantage rather than a feature list. Seven distinct entry points — text, an image, existing footage, a character, keyframes, references, a talking avatar — correspond to seven genuinely different starting materials, and picking the right one matters more than prompt quality. Publishing the model list, including which are new and what each is good for, is the kind of transparency almost nothing else in AI video offers. What holds it at four is the same ceiling everyone has: character continuity across a full video, and the fact that restyled footage inherits whatever was wrong with the original. AInexfinder Editor Score: 4.0/5.
Best for: Creators whose source material varies from week to week; Anyone who can shoot reference motion and wants it restyled
The visit link goes to domoai.app, the official site. Paid placements on AInexfinder are always labelled. How we make money
Most AI video tools give you a prompt box and hope your problem fits it. The trouble is that people arrive with wildly different starting materials — a script, a photograph, an hour of footage, a character design, a song — and a single interface serves one of them well.
DomoAI splits the entry point instead. Seven modes, each expecting a different kind of input, each doing something the others cannot.
That makes the first decision the important one. Choosing the wrong mode wastes far more time than choosing the wrong prompt, and it is the thing most people get wrong.
DomoAI describes Omni Reference as blending image, video and audio references into a single consistent video, and lists it first among the modes.
The problem it addresses is the central weakness of prompt-driven generation: description is a lossy way to specify a look. Cinematic, moody and warm lighting mean something to you and something slightly different to a model.
References remove that translation step. Showing the system the palette you want, the motion you want and the audio it should match is far more precise than any adjective, and it is how visual direction actually works between people.
Combining three reference types is the ambitious part. An image can carry style, a video can carry motion and pacing, and audio can carry rhythm — and a system that honours all three is closer to a brief than a prompt.
The realistic caveat is that reference conflicts have to be resolved somehow, and the resolution is not something you control. When the image's palette and the video's lighting disagree, something is discarded, and knowing which requires testing rather than reading — the same discipline that makes model-by-model tools like Argil worth driving deliberately.
Description is a lossy way to specify a look. Cinematic and moody mean something to you and something slightly different to a model.
Frames to Video takes 2–8 images and generates video with smooth transitions between every frame, which is the mode most likely to be underestimated.
It is effectively keyframing, and keyframing is how animation has always been controlled. You specify the moments that matter and let the system produce what happens between them.
That inverts the usual relationship with generative video. Instead of describing a shot and accepting whatever motion arrives, you fix the beginning, the end and several points in between — which is control you cannot get from a prompt.
It is particularly effective for things a text prompt handles badly: a specific transformation, a product rotating to a precise angle, a character moving into a defined pose.
The limit is the same as in traditional animation. Widely spaced keyframes give the system too much freedom and produce drift, so more frames means more control and less surprise — which is usually what you want for anything commercial.
DomoAI lists its models openly: its own DomoAI 2.5 alongside Seedance 2.5 and 2.0, MiniMax H3, GPT Image 2, Nano Banana 2 and Nano Banana Pro, with short notes on what each is for.
The notes are the useful part. Seedance 2.5 is described as taking up to 50 references in one prompt with 30 seconds to use them; MiniMax H3 is described as producing sound with the picture — dialogue, effects and room tone.
That level of specificity is rare and genuinely actionable. Knowing that one model handles many references and another generates audio alongside video lets you choose by requirement rather than by trial.
Running its own model alongside third-party ones is a defensible position too. It means the platform is not purely a reseller, while still inheriting improvements from frontier models as they ship.
The trade-off to note is that a multi-model platform's capabilities shift when models are added or retired, so a result you liked may not be reproducible in six months. Record which model produced anything you intend to repeat — the same advice that applies to Pollo AI and every other orchestration layer.
Video to Video transforms existing footage into anime, realistic or any style by reference, and Character to Video brings photo characters to life by uploading motion videos to specify actions.
These two modes are the most practically useful and the least discussed, because they start from something real rather than from nothing.
Restyling inherits structure from the source, which solves the hardest problem in generative video for free. Motion, timing, framing and continuity all come from footage that already worked, and the model only has to change appearance.
That is why restyled video is often more coherent than generated video, and why it is the sensible route for anyone who can shoot something. A phone recording of the actual movement you want beats a paragraph describing it.
The inherited limitation is the obvious one: restyling cannot fix bad footage. Poor framing, shaky camera work and awkward pacing survive the transformation intact, and a stylised version of a badly shot clip is a badly shot clip in a different style.
It is worth naming the shared ceiling, because no product in this category has cleared it and the marketing rarely mentions it.
Character continuity across a full video is the first. A face that stays recognisably the same person across twelve shots is far harder than one striking shot, and this is where most AI video visibly fails.
Duration is the second. Models produce short clips reliably and long ones badly, so anything of length is assembled from pieces — which puts the burden of coherence back on editing.
Text is the third and most stubborn. Legible words on signs, packaging or screens remain unreliable, which is a real problem for anything commercial where a product name has to be readable.
Physical plausibility is the fourth. Hands, liquids, reflections and anything with contact between objects are where generated video announces itself. None of this argues against using the tools; it argues for choosing shots that avoid the known failures — which is also why editors and clipping tools like Clipfly remain part of the workflow.
Almost all wasted time with a multi-mode tool comes from starting in the wrong mode and blaming the prompt.
This sequence picks the mode from what you already have rather than from what you imagine.
| Operating company | DOMOAI PTE. LTD. |
|---|---|
| Product type | AI video generation platform |
| Positioning | AI video generator for any idea, style and story |
| Modes | Omni Reference, Video to Video, Image to Video, Talking Avatar, Character to Video, Text to Video, Frames to Video |
| Frames to Video | 2–8 images, with transitions generated between every frame |
| Models | DomoAI 2.5, Seedance 2.5, Seedance 2.0, MiniMax H3, GPT Image 2, Nano Banana 2, Nano Banana Pro |
| Seedance 2.5 | Up to 50 references in one prompt, 30 seconds to use them, per the site |
| MiniMax H3 | Sound generated with the picture — dialogue, effects, room tone, per the site |
| Image tools | Text to image, editor, upscaler, background remover, face swap, extender, photo restoration |
| Editing | Upscaling, background replacement, lip sync and motion control |
| API | An API platform with documentation |
| Programmes | Affiliate, student and educator |
| Copyright | © 2026 DOMOAI PTE. LTD. |
Omni Reference blending image, video and audio references
Video to Video restyling of existing footage
Image to Video animation from stills
Talking Avatar generation with lifelike speech
Character to Video using uploaded motion clips
Text to Video from prompts
Frames to Video from 2–8 keyframe images
Upscaling, background replacement, lip sync and motion control
Video generators differ by how many ways in they offer and whether they name their models.
| Tool | Entry points | Models named | Best for |
|---|---|---|---|
| DomoAI | Seven distinct modes | Yes, with notes on each | Varied source material in one place |
| Argil | Playground, Director, Templates | No | Repeatable video formats |
| Pollo AI | Many models, one interface | Yes | Comparing generators directly |
| BeatViz | Music video specifically | Yes | Turning a track into a video |
| Kling 3.0 | One frontier model | It is the model | Driving a single generator directly |
Other generators and editors covering neighbouring parts of the same workflow.
Last checked . Read from domoai.app in a browser session on the date above. The homepage renders slowly, so this was captured after a longer settle than usual.
What we could not confirm: pricing and how credits are consumed per mode, which is the main practical question with a seven-mode platform; output resolution and duration ceilings; commercial and distribution licensing for generated video; whether models can be selected per generation or are assigned by mode; what happens to uploaded footage and reference images after generation; and how the platform's own DomoAI 2.5 model compares with the third-party ones. We did not generate any video.
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official DomoAI website.
Visit official website for pricingVendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
DomoAI earns an AInexfinder Editor Score of 4.0/5 (very good). Best for: Creators whose source material varies from week to week; Anyone who can shoot reference motion and wants it restyled; Producers needing exact moments hit rather than approximate ones.
Visit DomoAILog in to write a review.
No reviews yet. Be the first to share your experience with DomoAI.
Assigned reviewer
Daniel ReedSenior AI Tools Reviewer
Daniel leads AInexfinder's tool reviews. He researches each tool from its own pricing, documentation and policies, checks its claims against independent sources, and writes up what it does well, where it falls short and who it genuinely suits.
Daniel and the AInexfinder editorial team research DomoAI from its own website, pricing, documentation and policies, checked against independent sources. This review is research-based: unless its method note says otherwise, we have not bought a plan or run hands-on tests. The Editor Score is our editorial judgement, and payment never changes it.
Similar Tools
Mobile-first AI art and video generator with many styles Category: Image & Design.
Scenario review on AInexfinder — subscription AI tool for Image & Design. Features, pricing notes, and alternatives.
Patternaly is an AI pattern generator that turns a text prompt into seamless, tileable patterns for print-on-demand, textiles, packaging and wallpaper, with 19 artistic styles, a seamless checker, product mockups and HD export, and commercial rights on paid plans.

Midjourney is an AI image generator known for its distinctive aesthetic quality, currently on model V8.2, with a full web app alongside the original Discord workflow, plus an Editor, moodboards, style profiles, and five-second image-to-video.
Canva AI is the Magic Studio suite built into Canva — Magic Write for copy, Dream Lab for images, Magic Edit, Expand and Eraser for photos, Magic Switch for reformatting, Magic Charts for data, and Canva Code for interactive widgets.
GPT Image 2 launched on 21 April 2026 as ChatGPT Images 2.0 and as the gpt-image-2 API model. Its distinguishing capabilities are dense, accurate text rendering, layout fidelity for infographics and packaging, up to 3840px output, prompt-guided masking, and reasoning applied to image structure before generation.
Related Pages