Every sales organisation runs the same cycle. New messaging arrives, reps are trained, everyone certifies, and within a month the calls sound exactly like they did before.
The reason is not that the training was bad. It is that nothing checked. Certification measures whether a rep could say the words once in a room; it says nothing about whether they say them under pressure to a buyer who is not cooperating.
Hyperbound's design targets that specific failure — the gap between the practice room and the pipeline — by scoring the real calls too.
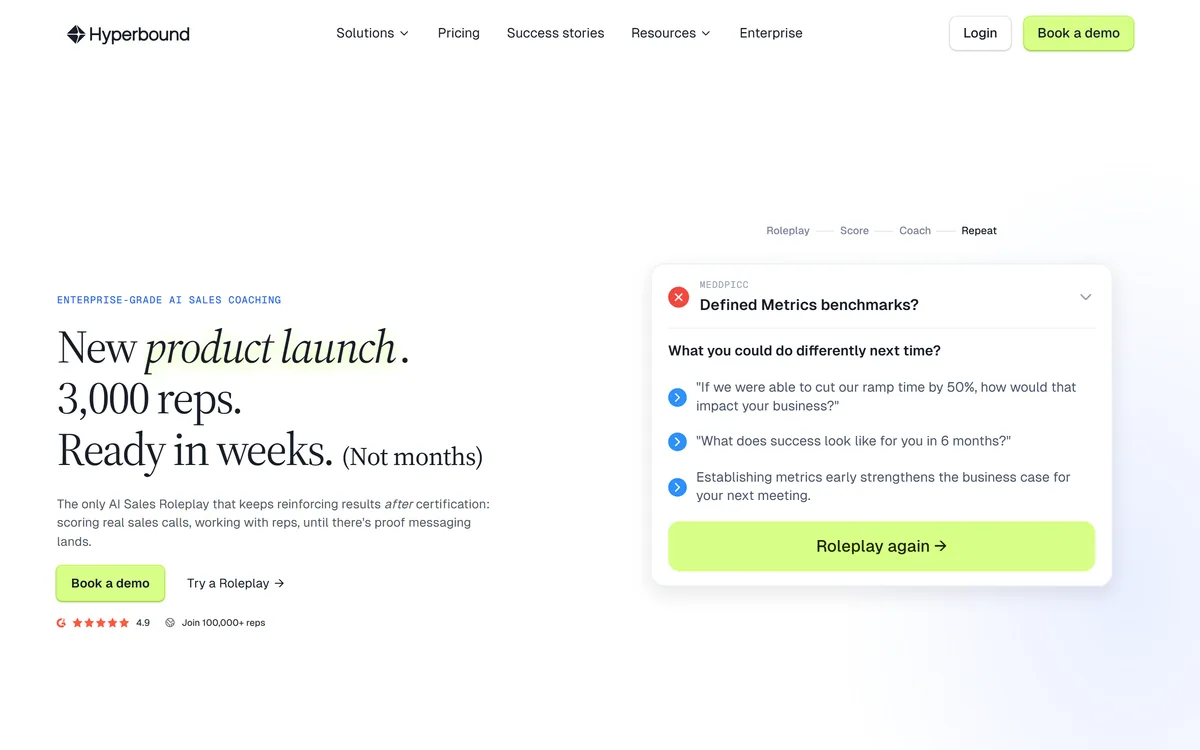
Hyperbound: Roleplay, Score, Coach, Repeat
- Roleplay built from your own material — your methodology, historical deals and top-performing reps, not generic scenarios.
- It does not end at certification: real calls are scored afterwards to test whether the messaging actually lands.
- Agents connect calls, deals and roleplays into automated coaching delivered where reps already work.
- 3,000 reps ready in weeks is the stated enterprise claim, alongside 100,000+ reps and a displayed 4.9 rating.
- IntelligentSystems Corp., with published case studies from named companies including Nivoda and JumpCloud.
Does AI Roleplay Actually Build Sales Skill?
Hyperbound describes roleplays built from your sales methodology, historical deals and top-performing reps, with a scored loop of practise, perform and activate.
The case for roleplay at all is strong and predates AI. Sales is a performance skill, performance skills improve with repetition against feedback, and reps get almost no repetition — a rep runs perhaps four discovery calls a week, all of them live, all of them with revenue attached.
What AI changes is the supply. A rep can run twenty roleplays in an afternoon, which is more discovery practice than a normal quarter provides, and none of it costs a real opportunity.
Building the persona from your own historical deals is the part that separates this from generic training. A simulated buyer who raises the objections your buyers actually raise is a fundamentally different exercise from one improvising a plausible enterprise CTO.
The honest limit is that repetition builds fluency, and fluency is necessary rather than sufficient. A rep who can deliver the discovery framework smoothly has removed one obstacle; whether they can read a room and abandon the framework when it is not working is not something a roleplay teaches.
A rep runs perhaps four discovery calls a week, all of them live, all of them with revenue attached. That is not enough repetition to get good at anything.
Where Simulated Buyers Fall Short
Simulated buyers differ from real ones in ways that matter, and knowing them prevents over-reading a roleplay score.
They are engaged. A real prospect is doing something else, joined late, and has already decided this call is a favour to a colleague. An AI buyer participates fully, which removes the single most common condition a rep actually faces.
They are coherent. Real buying committees contradict themselves, have a shadow decision-maker who never joined, and change what they want between calls for reasons nobody explains.
They also cannot be genuinely rude, bored or dismissive at the level real people manage, and handling that is a large part of the job. A roleplay that is uncomfortable is still substantially more comfortable than a bad call.
This is why the real-call scoring half matters more than the roleplay half. Practice builds the motion; only recordings of actual conversations show whether it survives — which is the same argument call platforms such as Aloware and CloudTalk make about their own recording features.
Scoring Real Calls, Not Just Practice Ones
Hyperbound states it is the only AI sales roleplay that keeps reinforcing results after certification, scoring real sales calls and working with reps until there is proof messaging lands.
The word proof is doing a lot of work there, and it is the right thing to be claiming. Sales enablement has historically been unable to demonstrate that anything it did changed what happened on calls.
Scoring real conversations against the same rubric used in practice closes the measurement gap. You can see whether the framework a rep certified on appears in their live calls, or whether it evaporated the moment revenue was at stake.
That produces uncomfortable findings, which is a sign it is working. The usual discovery is that adoption is bimodal — a few reps changed everything, most changed nothing, and the average conceals both.
The caution is about what a rubric can see. Automated scoring recognises whether questions were asked and topics covered; it is much weaker at whether the conversation was any good, and a rep who mechanically recites every required question can score well while conducting an interrogation.
- Judge the tool on real-call scores, not on roleplay completion rates.
- Expect bimodal adoption — the average will hide it.
- Watch for reps optimising the rubric rather than the conversation.
- Build personas from lost deals, not just won ones.
- Keep human coaching for the judgement a rubric cannot see.
Agents That Connect Calls, Deals And Roleplays
The third piece is described as agents turning what happens across calls, deals and roleplays into automated coaching, insights and actions delivered where you already work.
The argument for connecting these is genuine. A coaching suggestion is far more useful when it knows this rep's last six calls and the state of the deal, rather than being a generic reminder about discovery.
Delivered where you already work is the operationally important half. Coaching that requires opening a separate platform gets read on the day it launches and never again, which is why most enablement content is unopened.
What deserves scepticism is the volume. Automated coaching that arrives after every call becomes noise within a fortnight, and the difference between useful and ignored is entirely about restraint.
The question worth asking in an evaluation is how the system decides *not* to send something. A coaching agent that speaks only when it has something specific is worth ten that comment on everything.
What Roleplay Cannot Fix
Practice tools have a boundary, and mistaking a structural problem for a skill problem is an expensive error.
It cannot fix a product nobody wants. If calls are failing because the offer does not match the market, better discovery questions will produce better-articulated rejections at exactly the same rate.
It cannot fix targeting. Reps talking to the wrong accounts will improve at talking to the wrong accounts, which is why pipeline quality is usually the higher-leverage intervention — the problem tools like Kronologic and attribution platforms such as Cometly address from opposite ends.
It cannot fix a compensation plan that rewards behaviour the training discourages. Reps respond to how they are paid faster than to any enablement programme, and no roleplay outscores a quarterly quota.
And it cannot fix a hiring problem. Coaching moves a middling rep meaningfully and does not turn the wrong hire into the right one, which is a harder conversation than any software purchase.
Rolling Out Roleplay Across A Sales Floor
Enablement rollouts fail the same way: mandated for everyone at once, completed grudgingly, and abandoned when the quarter gets tight.
This sequence proves the loop on a small group before it becomes a mandate.
- Build personas from your lost deals first — that is where the real objections are.
- Start with one team, not the whole floor, and pick one that wants it.
- Baseline their real-call scores before any roleplay happens.
- Run the practice cycle, then re-score real calls against the same rubric.
- Look at the distribution rather than the average, since adoption is bimodal.
- Only mandate it once you can show the gap closing on live conversations.
Hyperbound: The Coaching Loop
| Operating company | IntelligentSystems Corp., per the footer |
|---|
| Product type | AI sales roleplay and coaching |
|---|
| Positioning | Enterprise-grade AI sales coaching |
|---|
| Core loop | Roleplay, score, coach, repeat |
|---|
| Persona sources | Your sales methodology, historical deals and top-performing reps |
|---|
| Beyond practice | Scoring of real sales calls after certification |
|---|
| Agents | Automated coaching and actions across calls, deals and roleplays |
|---|
| Frameworks | MEDDPICC referenced in the interface |
|---|
| Scale claims | 3,000 reps ready in weeks, 100,000+ reps joined, a displayed 4.9 rating |
|---|
| Named customers | Nivoda and JumpCloud case studies |
|---|
| Industries | B2B SaaS, sales trainers and agencies, call centres, banking and financial advisers |
|---|
| Meeting recorder | A Hyperbound recorder joins live calls, per the interface shown |
|---|