Salesken: What Gets Analysed
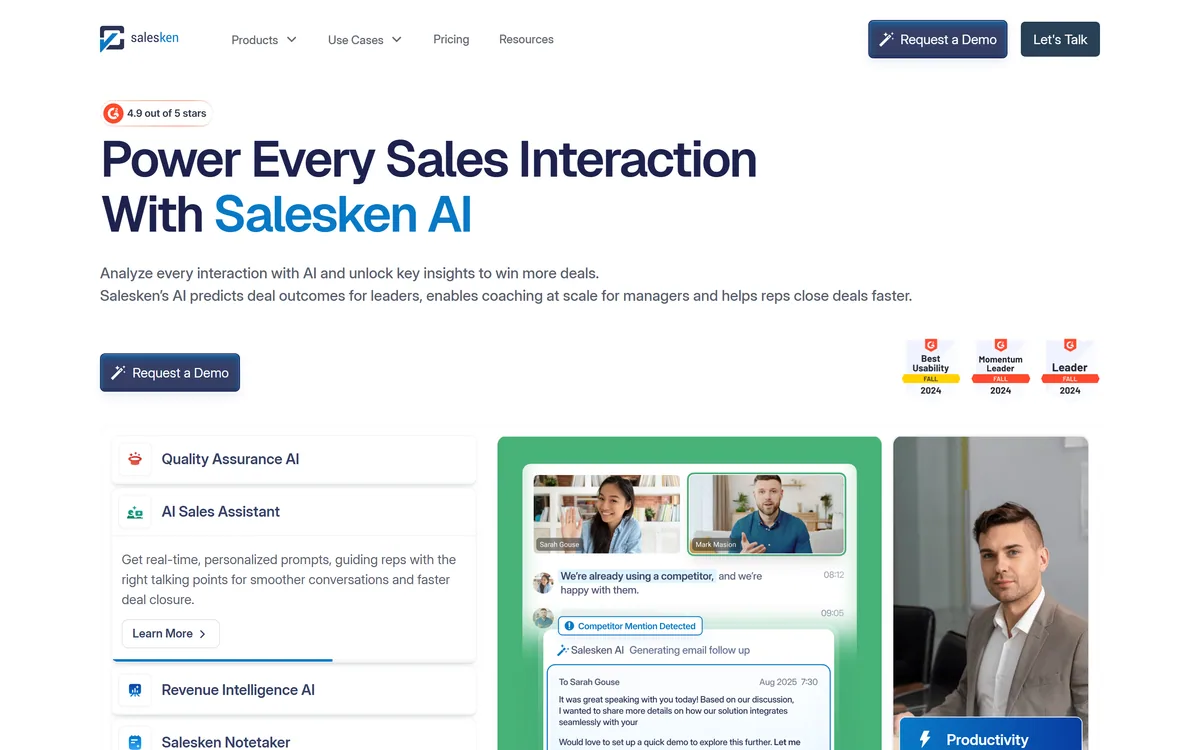
- Every conversation, not a sample — quality assurance across 100 percent of calls.
- Live in-call prompts giving reps talking points while the conversation is happening.
- Deal prediction with risk alerts, buyer intent signals and automated qualification.
- CRM enrichment: transcripts, summaries and action items logged automatically.
- SOC 2, ISO 27001 and GDPR stated, with a published data processing addendum.
| Category | Conversation intelligence and revenue intelligence for sales teams |
|---|
| Coverage | Stated as evaluating 100 percent of conversations rather than a sample |
|---|
| Products | Quality assurance AI, sales assistant, revenue intelligence, notetaker, field sales analytics |
|---|
| Real-time | In-call prompts with talking points and objection handling |
|---|
| Prediction | Deal outcome forecasting, risk alerts and automated BANT qualification |
|---|
| Compliance monitoring | Breaches, objections and critical moments flagged during calls |
|---|
| CRM | Transcripts, summaries and action items auto-logged |
|---|
| Languages | Analysis, coaching and scoring stated across multiple languages |
|---|
| Field sales | Conversations captured outside the contact centre for performance analysis |
|---|
| Adoption | Stated as 200-plus businesses worldwide |
|---|
| Security | SOC 2 certified, ISO 27001 certified and GDPR compliant |
|---|
| Legal | Privacy policy, data processing addendum and terms published in the footer |
|---|
Salesken: Every Call Analysed, Not Sampled
The clearest claim on the site is also its best: evaluate 100 percent of conversations with AI, and ditch random sampling.
That is a statistical argument dressed as a feature, and it is worth taking seriously on those terms.
Traditional sales quality assurance works by sampling. A manager listens to two or three calls per rep per month, scores them against a rubric and gives feedback. It is the only thing that was ever possible, and it is close to worthless as measurement.
A rep making forty calls a week has roughly one in fifty reviewed. Whatever conclusion the manager draws is based on a sample far too small to distinguish a pattern from a bad afternoon, and reps know it — which is why QA feedback is so often received as arbitrary.
Scoring every conversation changes the epistemic status of the exercise entirely. You move from an anecdote to a population, and a rep can no longer reasonably say the reviewer caught them on a bad day. That alone justifies the category.
A rep making forty calls a week has one in fifty reviewed. Whatever the manager concludes from that is an anecdote wearing the costume of a measurement.
Consent, Recording And Two-Party Rules
Any product that records and analyses conversations carries obligations that the marketing page will not walk you through, and they belong in the evaluation rather than in the implementation.
Recording law varies sharply by jurisdiction. Some places require only one party's consent; others require everyone on the call to agree, and the obligation falls on the business doing the recording.
Under GDPR the analysis raises separate questions again, because a recording of a customer conversation is personal data, and inferring intent, sentiment or buying signals from it is processing that needs a lawful basis and a retention policy.
The compliance foundations here are appropriate for the category — SOC 2, ISO 27001, GDPR and a published data processing addendum — which is the necessary groundwork rather than the answer to your specific question.
There is also the internal dimension. Analysing every call means analysing every employee continuously, and how that is introduced determines whether it lands as coaching or as surveillance. Teams that share scores with reps and use them for development get a different reception from teams where the dashboard is management-only. Meeting transcription tools such as Otter.ai raise the same consent questions at lower stakes.
What Changes When You Review Every Conversation?
The claimed consequence is full pipeline visibility beyond CRM data, going past logged activities to reveal deal risks, buyer intent and next-best actions.
The gap between what a CRM records and what happened is the real subject here, and every sales leader knows it exists.
A CRM contains what a rep chose to log, written after the fact, in a state of mind shaped by wanting the deal to look healthy. Nobody records that the buyer sounded unconvinced, or that a competitor came up three times, or that the decision-maker was never actually on the call.
Those are precisely the signals that predict outcomes, and they only exist in the conversation itself.
The second thing that changes is what coaching can be built on. Comparing every call against calls that closed produces specific, evidenced feedback rather than a manager's impression — one of the site's own testimonials describes exactly that, feedback on what to say and how to say it, benchmarked against successful calls. The published outcome figures are notably modest: a 12 percent reduction in QA costs, a 2 percent conversion improvement and a 4 percent reduction in managerial costs. Small honest numbers read better than large unexplained ones.
- Confirm recording law for every jurisdiction your team calls into.
- Decide whether reps see their own scores before you switch it on.
- Test live prompting with your best rep and your newest one.
- Treat risk scores as triage, never as a reason to abandon a deal.
- Check what qualification the model infers, and whether you agree.
Real-Time Prompts During A Live Call
The sales assistant is described as delivering real-time personalised prompts with the right talking points, and live in-call guidance for handling objections.
This is the most ambitious feature in the platform and the one that deserves the most scepticism before deployment.
The appeal is obvious. Feedback delivered a week after a lost call is useless; the moment a rep needs to know how to answer an objection is while the objection is being raised. Closing that gap addresses a genuine failure in how sales coaching works.
The difficulty is cognitive rather than technical. A rep reading a suggestion while listening and speaking is doing two demanding things at once, and the result can be worse than either alone — a noticeable pause, a switch in register, a scripted phrase in the middle of a natural conversation. Buyers hear it.
Our expectation, which a trial should confirm or refute, is that this helps a new rep considerably and irritates an experienced one. The onboarding case is strong: a person in their second week genuinely does not know what to say, and a prompt beats silence. The site's own framing of faster rep ramp-up is the most credible version of the claim. Artisan approaches the pipeline from the other end, automating outreach rather than assisting the call.
Predicting Deal Outcomes And Its Limits
Revenue Intelligence AI is described as identifying at-risk deals, understanding buyer intent, generating forecasts and running automated qualification assessment.
Deal prediction from conversation signals is more defensible than prediction from CRM fields, and it still carries two problems worth stating.
The first is that the model learns from your historical outcomes, so it encodes how your team has sold rather than how your market buys. A pattern that predicted losses last year may be a pattern about a rep who left.
The second is self-fulfilment. A rep told a deal is at risk will spend less time on it, and the deal will then fail — confirming a prediction that helped cause the outcome. Any team using risk scores should watch for this deliberately, because the metrics will look excellent while it happens.
Automated qualification has a milder version of the same issue. Inferring budget, authority, need and timeline from what was said is a reasonable heuristic, and it is not a fact — buyers are vague about budget for tactical reasons, and a model reading that as absence of budget is drawing the wrong conclusion. Used as triage across a large pipeline these are genuinely useful. Used as verdicts on individual deals they will be wrong often enough to matter. Forecasting-first platforms like Aviso make the same trade at the portfolio level.
Coaching A Sales Team With Evidence
The difference between this landing as coaching and landing as surveillance is set in the first fortnight, not in the configuration.
This order gets adoption rather than resistance.
- Confirm recording and consent requirements for every region you call.
- Tell the team what is analysed and who sees it, before it is switched on.
- Give reps their own scores from day one, not only their managers.
- Build the rubric from calls that actually closed, not from a generic template.
- Pilot real-time prompting with new starters before rolling it wider.
- Audit whether risk scores are changing rep behaviour and causing the outcome.