Perplexity AI is an answer engine that runs live web searches and returns cited answers, with Deep Research for long agentic reports, Spaces for persistent projects, the Comet browser, and the Sonar API for developers.
Perplexity AIperplexity.ai62,008 viewsAdded June 10, 2025100M+ visitors
Perplexity AI answers questions by searching the web first and citing what it used. That ordering is the whole point — the answer is assembled from sources you can click, not recalled from training data.
It is best understood as a search replacement rather than a chatbot. People who adopt it tend to stop opening a search engine for factual questions, which is a different habit from occasionally asking an assistant.
This review covers how the citation model actually behaves, what Deep Research and Spaces are for, where the Comet browser fits, and the specific ways cited answers can still mislead you.
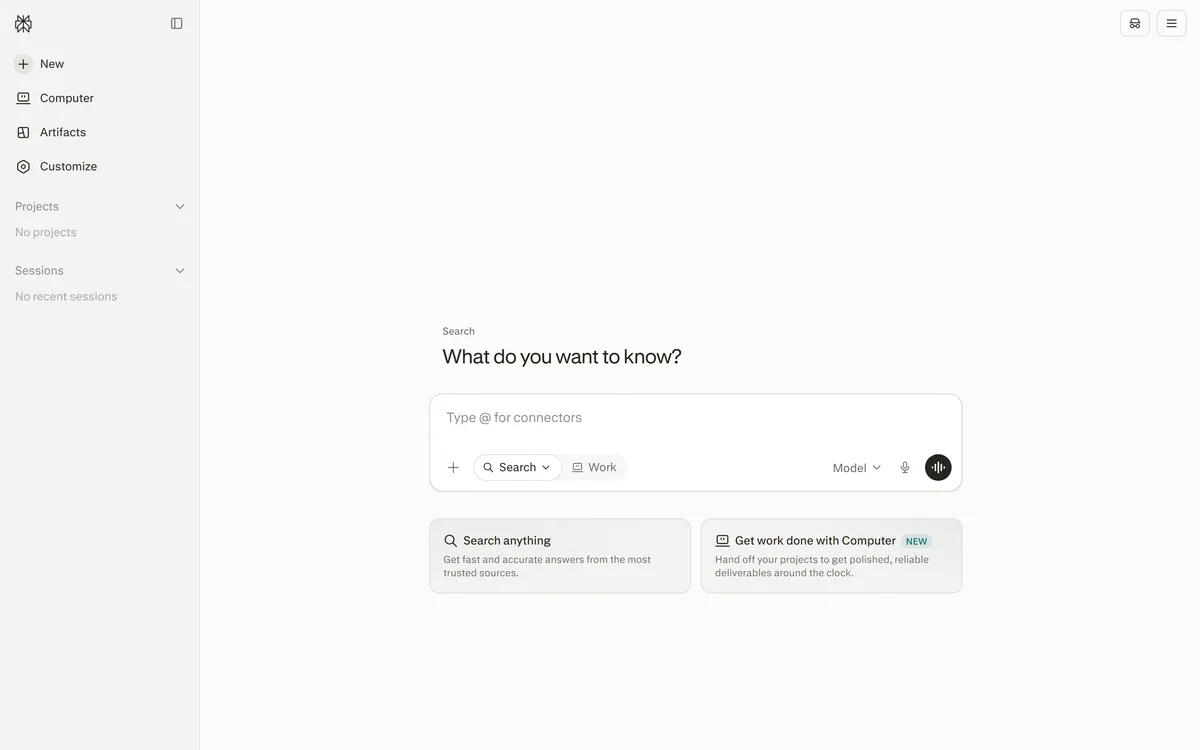
Perplexity opens on a search box rather than a chat thread — the framing is deliberate.
Perplexity At A Glance
Category
AI answer engine with live web search
Core behaviour
Runs searches, then answers with inline citations to the sources used
Research mode
Deep Research decomposes a question, runs many searches, and returns a cited report
Project workspace
Spaces hold uploaded files and web sources for ongoing work
Browser
Comet, a Chromium-based browser with an assistant on every page
Developer access
Sonar API, including a deep research model
Model choice
Perplexity's own Sonar family plus selectable third-party frontier models
Platforms
Web, iOS, Android, and the Comet desktop browser
Free plan
Yes
Citations Change What You Can Trust
Every answer carries inline references to the pages behind it. That single design choice removes the worst failure of general chatbots — a confident claim with no way to check it.
The practical effect is that verification takes seconds rather than a separate search. You read the claim, click the source, and confirm it says what the summary says.
It is not a guarantee of accuracy, and treating it as one is the mistake to avoid. Citations tell you where a claim came from, not whether the source was any good.
Deep Research: When To Spend The Time
Deep Research is a different mode, not a longer answer. It breaks a question into sub-questions, runs a large number of searches, and returns a structured report with citations throughout.
It takes minutes rather than seconds, which is the correct trade for genuine research — competitive landscapes, technical comparisons, background on an unfamiliar field.
Using it for a quick factual lookup wastes both your time and the depth. The standard answer mode already handles that well.
Spaces Keep A Project's Context
Spaces are persistent containers for ongoing work. You add uploaded documents and web sources, then ask questions across the whole collection rather than re-establishing context in each new thread.
The difference from a normal chat is permanence. A chat forgets when it ends; a Space keeps accumulating, which suits a piece of work running over weeks.
This is the feature that turns Perplexity from a lookup tool into somewhere a project lives. It is also the most underused part of the product.
The Comet Browser
Comet is a Chromium-based browser with the assistant present on every page rather than in a separate tab. Ask about what you are reading and it answers with that page in context.
For research-heavy work the removal of copy-paste friction matters more than it sounds. The assistant already sees the page, so the question can simply be asked.
Whether you want your browser and your AI assistant supplied by the same vendor is a reasonable question to sit with before switching.
Model Choice And The Sonar API
Perplexity runs its own Sonar model family and also lets you select third-party frontier models, so a quick factual question and a hard reasoning task need not use the same engine.
The Sonar API exposes the same search-grounded answering to developers, including a deep research model. This is how Perplexity ends up inside other products — teams that want cited, current answers without building a retrieval pipeline themselves.
If you are choosing between building retrieval-augmented search and calling an API, this is the comparison worth running properly.
How Cited Answers Still Go Wrong
The most common failure is source quality. Perplexity cites what it finds, and on contested or commercial topics that can mean content marketing rather than authoritative material. A citation to a weak source still looks like a citation.
Summarisation drift is subtler and more dangerous. The answer occasionally states something slightly stronger or more general than the linked page supports, which only shows up if you actually open the source.
Recency also cuts both ways. Live search means current information, but it also means a widely repeated recent error can propagate into an answer faster than a correction does.
What It Means For Publishers
Perplexity answers questions without sending most readers onward, which is a genuine shift for anyone who publishes. A cited answer satisfies the question at the point of asking, and the click that used to follow often does not.
The flip side is that being cited is now its own form of visibility. Content that states things clearly, attributes claims, and is structured enough to quote gets pulled into answers more readily than content that buries its point.
If you publish, the practical response is not to fight the format but to write for it — clear claims, real evidence, and a reason to click through that the summary cannot satisfy on its own.
Using It Well
Read the sources on anything that matters. The citations exist to be clicked, and the tool is most valuable when treated as a fast route to primary material rather than a replacement for reading it.
Match the mode to the job — quick answers for lookups, Deep Research for genuine investigation, Spaces for work that spans sessions. Most disappointment comes from using one mode for all three.
Ask questions that a search engine handles badly. "How do these two approaches differ and who says so" plays to its strengths far better than a query you could have typed into a search box.
Verdict On Perplexity
Perplexity is the strongest option available for factual questions where you want to see the evidence. The citation model genuinely changes how much you can rely on an AI answer, and Deep Research produces work that would otherwise take an afternoon.
Choose it if your questions are about current, checkable facts, if you research topics that span sessions, or if you want search-grounded answers in your own product through the API. Choose a general assistant instead for writing, coding, and open-ended reasoning, where live search adds little.
Check perplexity.ai for current plans — the free tier is genuinely usable, and the paid tiers mainly buy depth and model choice rather than basic access.
Key features of Perplexity AI
Live web search with inline citations on every answer
Deep Research mode producing long, structured, cited reports
Spaces for persistent projects with uploaded files and web sources
Comet, a Chromium-based browser with a page-aware assistant
Selectable models across Perplexity's Sonar family and third-party frontier models
Sonar API for adding search-grounded answers to your own applications
Pros & cons
Pros
5
Citations make answers checkable in seconds rather than on trust
Deep Research replaces hours of manual comparison work
Spaces keep long-running research context instead of losing it per chat
Genuinely useful free tier, not just a teaser
API exposes the same grounded answering to developers
Cons
5
Cites whatever ranks, so weak sources can look authoritative
Summaries occasionally overstate what the linked page actually says
Live search can amplify a recent error before corrections circulate
Weaker than general assistants at writing, coding, and open-ended reasoning
Bundling browser and assistant from one vendor is a real consideration
Best For
Researchers and analysts who need sources alongside answers
Anyone replacing a search engine for factual questions
Teams running comparisons and landscape reviews
Writers who need current, checkable material rather than prose help
Developers embedding cited, search-grounded answers via an API
Editor's Verdict
4.6/5
Perplexity AI has an AInexfinder Editor Score of 4.6/5.
Perplexity AI pricing
AInexfinder does not list plan prices or billing details. For current pricing, plans, and trials, visit the official Perplexity AI website.
Vendor pricing, credits, and billing policies change over time. Always confirm on the official site before you buy.
Frequently asked questions
How is Perplexity different from a general AI chatbot?
It searches the live web before answering and cites the pages it used, so answers reflect current information you can verify. A general chatbot answers mainly from training data, which is why it cannot show you where a claim came from.
What is Perplexity Deep Research for?
Genuine investigation rather than lookups. It splits a question into sub-questions, runs many searches, and returns a structured report with citations. It takes minutes, so use standard answers for anything quick.
What are Perplexity Spaces?
Persistent containers for ongoing work. You add your own documents and web sources, then query across the whole collection, so research context survives between sessions instead of ending with each chat.
What is the Comet browser?
A Chromium-based browser from Perplexity with the assistant available on every page, so you can ask about what you are reading without copying it elsewhere.
Can I trust Perplexity's citations?
Trust them as pointers, not proof. Perplexity cites what its search finds, which on commercial topics can mean marketing content, and summaries occasionally state something slightly stronger than the source supports. Open the sources on anything important.
Does Perplexity have an API?
Yes. The Sonar API exposes search-grounded answering to developers, including a deep research model, which is how other products add cited answers without building their own retrieval pipeline.
Is Perplexity free?
There is a free tier, and it is genuinely usable rather than a teaser. Paid tiers mainly add depth, higher limits, and model choice. Check perplexity.ai for current plan details.
Daniel reviews AI tools the slow way — by actually using them on real projects. His reviews cover what works, what breaks, and who each tool is genuinely a good fit for.
Daniel and the AInexfinder editorial team research Perplexity AI using public product information, listing evidence, and (when available) hands-on checks. Scores reflect listing completeness and transparency — not paid placement.
Listings may include affiliate or sponsored placements, which are labeled when present. Editorial scores and cons are not sold. See our affiliate disclosure and review methodology.
Claude is Anthropic's AI assistant, available on web, desktop, mobile, and in Chrome, with Projects for persistent context, Artifacts for generated documents and apps, Skills, Connectors, and Claude Code for developers.
ChatGPT is OpenAI's AI assistant, covering conversation, document and image work, web browsing, Projects, Tasks, custom GPTs, agent actions, and the Codex coding agent, across web, desktop, and mobile.
JAIS Chat is a bilingual Arabic and English conversational assistant launched by Core42, part of the UAE's G42 group. It runs on the Jais family of Arabic large language models developed by Inception with MBZUAI and Cerebras, and is built to handle Arabic dialects and cultural context rather than translated English.
Kimi is Moonshot AI's assistant, running on its K3 model and positioned for agentic coding and knowledge work. Its interface opens on a set of output surfaces — slides, sheets, documents, websites, design, deep research and a multi-agent Swarm — alongside scheduled tasks, projects and a desktop app.
Reka is an AI research lab building omni models — Spark, Edge, Flash and Core — that process video, image, audio and text in a single architecture rather than bolting modalities together. It also runs Reka Cloud for training and deployment, video infrastructure available by API or MCP, and a training-data division.
Duck.ai is DuckDuckGo's free AI chat that gives anonymised access to a selection of popular models from major providers, with image creation and a deliberately light, privacy-first footprint. It is a privacy-focused front-end rather than its own frontier model.