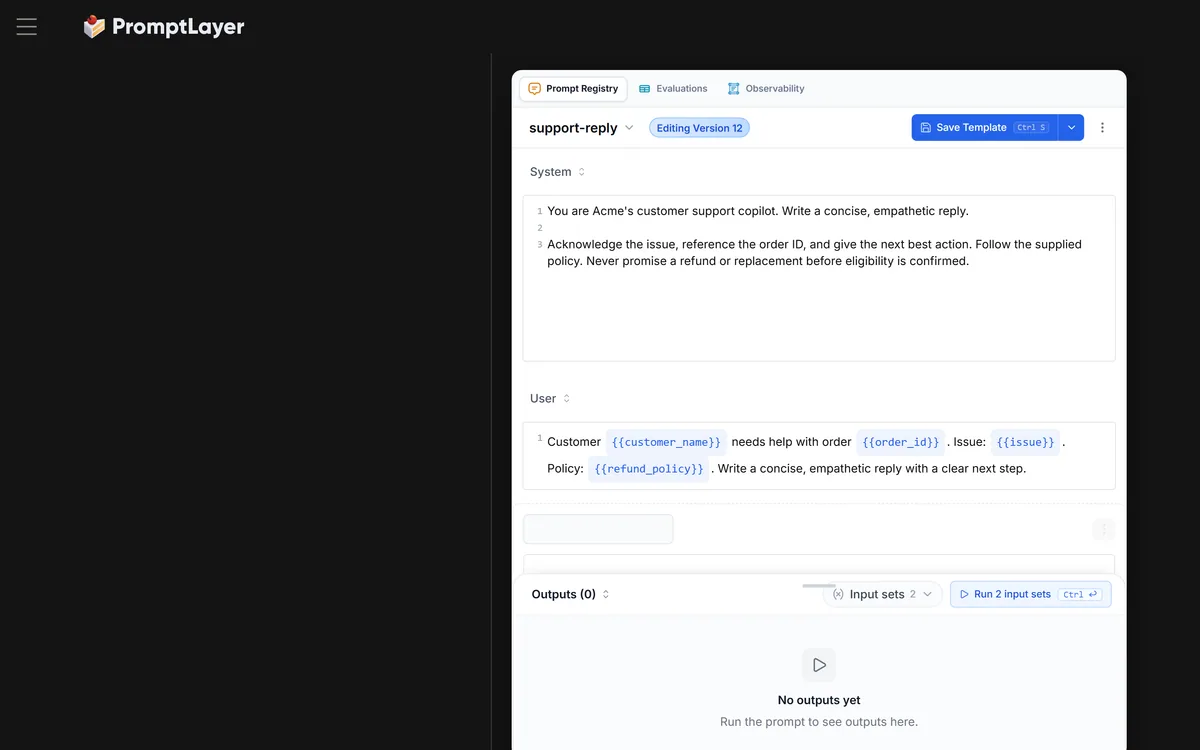
- A prompt CMS with visual editing, versioning, diffs, rollback and A/B releases.
- Evaluations: dataset-backed tests, human review, automated graders and historical backtests.
- Observability connecting production traces to the exact prompt version that ran.
- Non-engineers can ship — prompt deploys are decoupled from application releases.
- SOC 2 Type 2, HIPAA and GDPR compliance stated, with a public trust centre.
PromptLayer: Prompts Out Of The Codebase
The positioning is a single sentence and an unusually accurate one: the prompt CMS, eval harness and observability stack you would build eventually, shipped today, letting domain experts collaborate without touching your codebase.
The words you would build eventually are doing the persuading, and they are correct.
Every team that ships an AI feature follows the same path. Prompts start as string literals. Someone moves them into a constants file. Someone adds an environment variable so staging can differ. Then a request arrives to change a prompt without a deploy, and a small internal admin tool appears.
Six months later that tool has versioning, an approval flow, a logs viewer and nobody who wants to maintain it. It is the classic accidental internal product.
The claim here is not that this is impossible to build. It is that you will build it, badly, while your actual product waits. The counter-argument is real too: a bespoke tool fits your workflow exactly, and it is not obvious that a hosted registry is worth the dependency until the team crosses a certain size.
One line in the feature list gives the cleanest reason to move: prompts should not be scattered through your codebase. Most teams recognise that description immediately.
Prompts start as string literals, become a constants file, then an internal admin tool with versioning and an approval flow that nobody wants to maintain.
Regression Testing A Prompt Change
The evaluation feature set is specific: historical backtests against past data, regression tests triggered whenever a prompt updates, model comparisons, and one-off bulk jobs against batches of test inputs.
Regression testing is the capability that makes fast prompt iteration safe rather than reckless, and the reason is a property of prompts that surprises people.
Prompt changes are non-local. Adding a line to fix one failing case changes behaviour on inputs that had nothing to do with it, because you have shifted the model's whole conditioning rather than patched a branch. Nothing about the edit tells you which other cases moved.
Without a dataset and automatic scoring, the only feedback is a support ticket a week later, and by then three more changes have shipped on top.
Backtesting against historical data is the sharper version of the same idea, because it answers the question that actually matters: would this version have done better on the traffic we really received? Dedicated harnesses like Promptfoo go deeper on evaluation alone; the argument here is that the eval belongs next to the registry that triggered it.
Why Should Prompts Live Outside Your Code?
The stated benefit is decoupling engineering releases from prompt deploys, with versions published interactively to production and development.
That is an operational change with a larger organisational consequence than it first appears.
When a prompt lives in the repository, changing it requires an engineer, a review, a merge and a deploy. The cost is not the typing; it is the queue. A content lead who notices the assistant is too formal files a ticket, waits, and by the time it ships has stopped noticing.
When a prompt lives in a registry, the same person edits it, tests it against a dataset and publishes it — and the iteration loop shortens from a week to minutes.
The obvious objection is that letting non-engineers change production behaviour sounds alarming. It is only alarming without the surrounding machinery. Immutable version history, diffs, comments, rollback and evals that run on every update are exactly what makes it safe, and they are the same controls engineers already expect for code.
The site's own case studies describe the outcome directly: a curriculum team compressing months of work into a week, and lawyers owning prompt iteration and catching regressions before updates reach hundreds of litigators.
- Move prompts to a registry before you build the internal tool.
- Require a regression eval on every prompt update, not just risky ones.
- Keep release labels as the deploy mechanism, so rollback is instant.
- Give domain experts the editor and the dataset together.
- Link every production trace to a prompt version from day one.
Evals, Traces And What Connects Them
Observability is described as connecting production traces to prompt versions, inspecting failures, and tracking cost, latency and token usage — with a stated benefit of not jumping between separate analytics and monitoring tools.
The connection is the product, more than any individual capability.
Three things are typically owned by three different systems: the prompt lives in a repository, the logs go to a monitoring stack, and evaluations run in a notebook someone wrote. Each works. Together they cannot answer the one question that matters, which is whether the change you shipped on Tuesday made things better or worse.
Answering it requires the trace to know which prompt version produced it, and the eval score to attach to that version too.
For agents this stops being a convenience and becomes a necessity. A multi-step workflow that fails gives you a bad final answer and no indication of which step went wrong — the site's Ellipsis case study describes jumping from a workflow ID to the exact failing run in a few clicks, which is the entire debugging story for agent systems. General LLM observability tools such as Langfuse cover the tracing half well; the differentiator here is that the registry and the graders sit in the same place.
Letting Domain Experts Iterate Directly
The strongest claim on the site is a position rather than a feature: building good AI is about understanding your users, which is why subject matter experts are the best prompt engineers.
The community framing extends it — lawyers, doctors, educators and even software engineers, in that order.
The claim holds up under scrutiny. Prompting is not a technical skill in any meaningful sense. It is the ability to specify a task precisely, anticipate how it will be misread, and recognise a good answer from a plausible one. A teacher knows what a well-graded essay looks like. An engineer does not, and no amount of prompt technique substitutes.
The named case studies are consistent with that reading and are specific enough to check: support automation scaled twentyfold at an e-commerce support company, over a million grades shipped by a curriculum and engineering team building pedagogical evals, newsroom agents processing thousands of stories daily, and a launch handling 1.5 million requests through a viral spike.
The privacy posture matches the customer list — SOC 2 Type 2, HIPAA and GDPR compliance stated with a public trust centre, which is what selling into legal, healthcare and education actually requires. The integration list is long enough to matter, covering the major model providers, the common agent frameworks and OpenTelemetry. Proxy-level tools such as Helicone capture cost and usage without touching the prompt layer at all.
Shipping Prompt Changes Safely
The risk in fast prompt iteration is not a bad prompt. It is a good prompt that quietly broke something nobody was testing.
This order makes speed safe rather than merely fast.
- Move prompts into the registry before writing your own admin tool.
- Build a dataset from real production inputs, including the failures.
- Wire regression evals to run on every prompt update automatically.
- Give domain experts editing rights and the dataset at the same time.
- Ship through release labels so rollback is one action.
- Backtest each new version against historical traffic before promoting it.